This is the full developer documentation for Autonoma
# Introduction
> Autonoma is an agentic end-to-end testing platform. Connect your repo and every pull request gets reviewed automatically on a live preview environment - no test scripts to write or maintain.
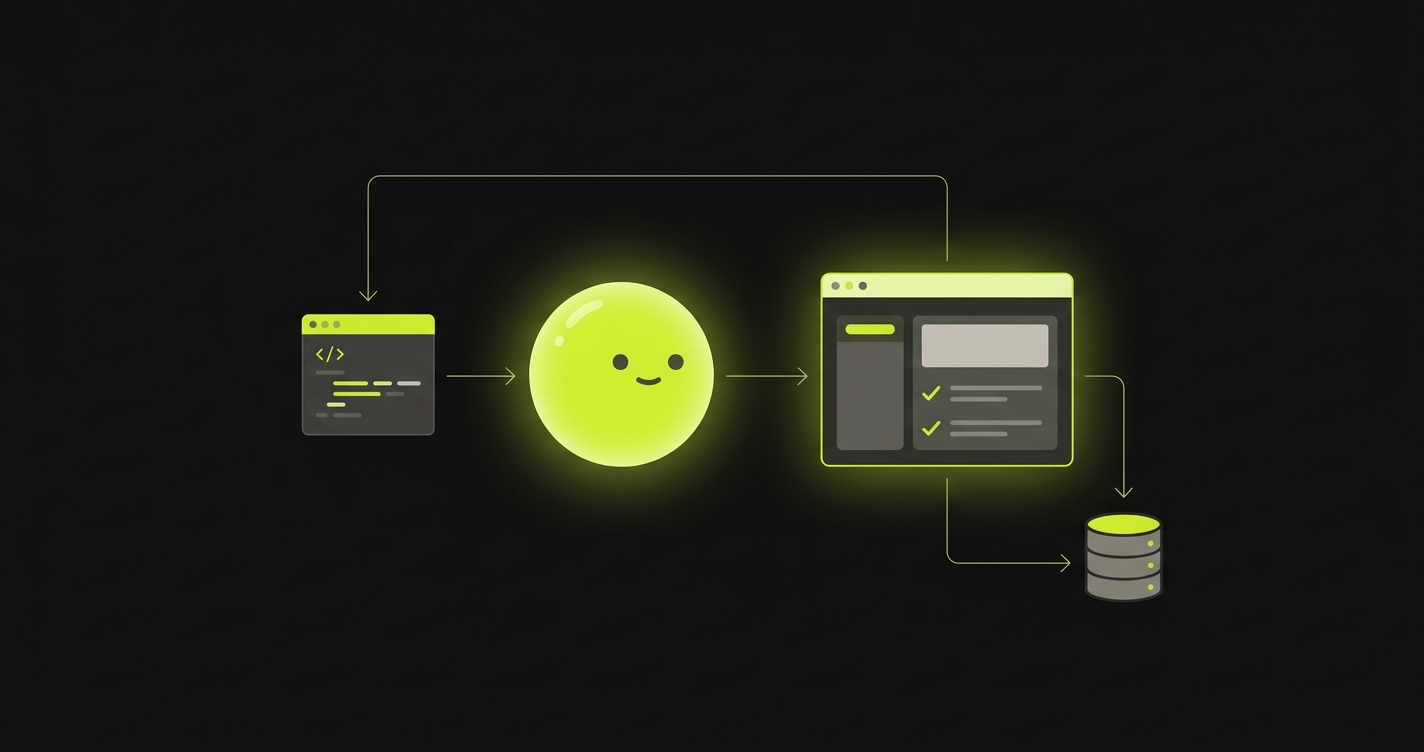
Autonoma is an agentic end-to-end testing platform. Connect your repository and every pull request gets reviewed automatically on a live preview environment - an AI agent exercises your app in a real browser, checks that it still works, and reports back on the PR.
You don’t write or maintain test scripts. There are no selectors to update when a button moves. Autonoma generates a suite of natural-language tests from your codebase, and an agent figures out how to run them - picking elements, making assertions, and healing itself when your UI changes.
## How it works
Every pull request runs through the same loop, from opening the PR to a reviewed result:
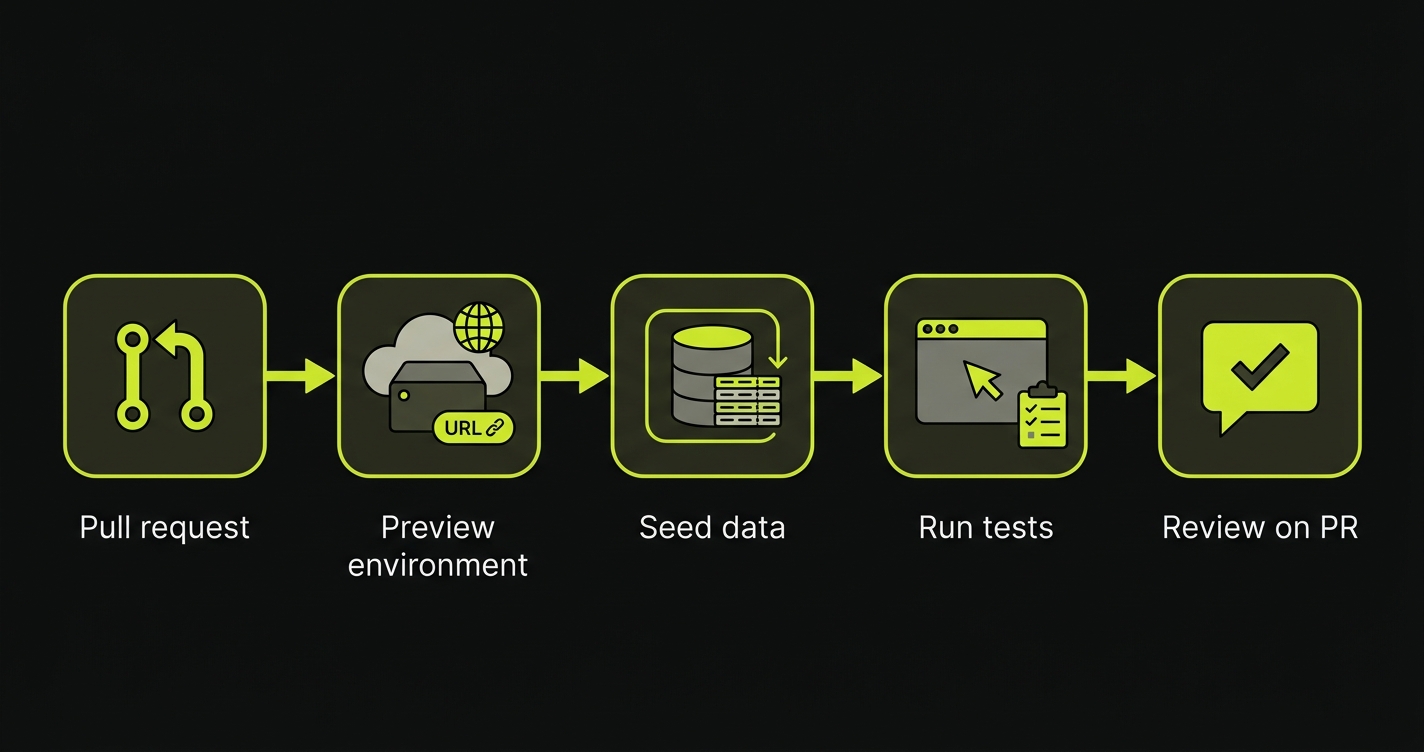
1. **Pull request** - you open a PR (or push a change to one).
2. **Preview environment** - a [preview environment](/preview-environments/) builds an isolated, full-stack preview of your app for that PR and gives it a live URL.
3. **Seed data** - the [Environment Factory](/environment-factory/) creates fresh, isolated test data so every run starts from a known state.
4. **Run tests** - the agent runs your test suite against the preview, exercising the app in a real browser.
5. **Review on PR** - Autonoma reviews each run, confirms what passed and what broke, and comments the result back on the pull request.
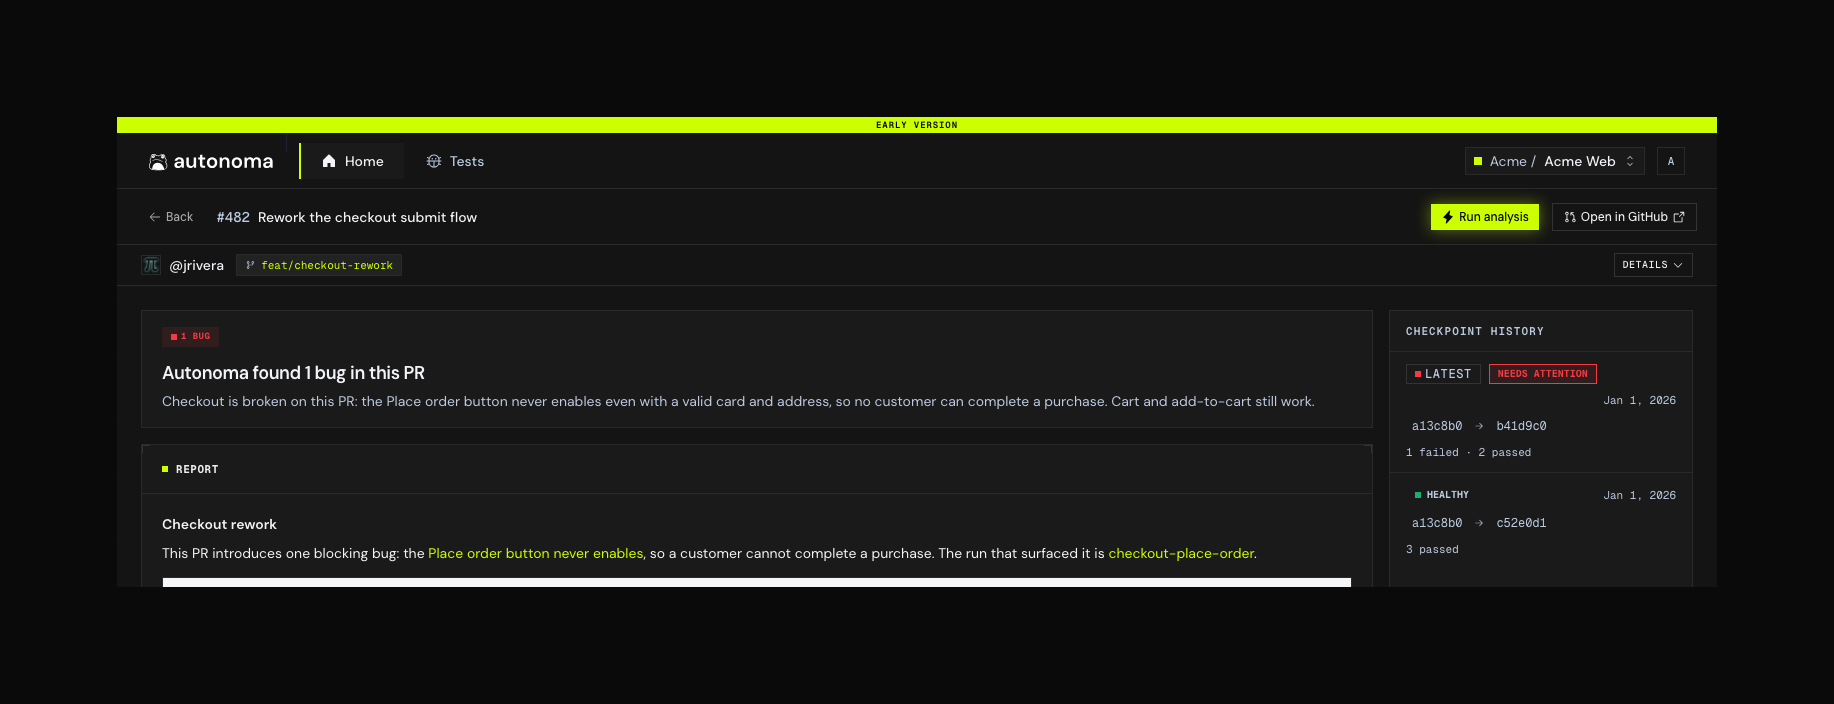
That last step is the one you live with day to day: a written verdict on the pull request, the bugs separated from the infrastructure noise, and the evidence for each.
When the PR closes, the preview environment and its data are torn down automatically.
## What you set up
Autonoma gets you value in two stages: **connect your repo** to go live with preview environments and automated PR reviews, then **deepen coverage** by generating a test suite and wiring up real test data. Three pieces, set up in order:
1\. Preview Environments
Install the GitHub app and configure your stack. Every PR then gets a live, isolated preview - and an automated review. This alone gets you live.
[Set up Preview Environments →](/preview-environments/)
2\. The Planner CLI
Reads your codebase and generates a complete, natural-language E2E test suite - pages, flows, and scenarios. One command.
[Run the planner →](/test-planner/)
3\. The Environment Factory
One endpoint in your backend that creates isolated test data before each run and tears it down after, so tests always start clean.
[Set up the Environment Factory →](/environment-factory/)
The Environment Factory has an SDK for every major stack - TypeScript, Python, Elixir, Java, Ruby, Rust, Go, and PHP. [Copy a working endpoint for yours.](/environment-factory/examples/)
## Using these docs with AI
Every page is available as plain text for coding agents. Point Claude Code, Cursor, or Copilot at the file below and it can pull in exactly the pages it needs:
```plaintext
https://docs.autonoma.app/llms.txt
```
A single [complete file](/llms-full.txt) with all pages concatenated is also available.
## Contributing
Want to run Autonoma locally or work on the platform itself?
Development setup
Clone the repo, install dependencies, and get the platform running locally.
[Get started →](/development/setup/)
Architecture overview
How the monorepo fits together and the key design decisions behind it.
[Read the overview →](/development/architecture/)
# Troubleshooting
> The questions people actually hit - what Autonoma supports and does not, why setup stalls, why a run has not started, how credits and billing work, and what we do with your code and data.
The problems people run into most often, and what to do about each. If your question is about the Environment Factory specifically, the [error-code reference](/environment-factory/security/) goes deeper.
## Is this supported?
The short answers, so you can find out in one line whether Autonoma fits.
| You want to | Supported |
| ----------------------------------------------------------- | -------------------------------------------------------------- |
| Connect a **GitHub** repository | Yes - this is the only source host |
| Connect GitLab, Bitbucket, or Azure DevOps | No |
| Test a **web** application | Yes |
| Test an iOS or Android app | No |
| Use Autonoma without a repository | No - reviews are driven by pull requests |
| Sign in with something other than Google | No |
| Push results to Jira, Xray, or another test-management tool | No |
| Have a coding agent act on the results | Yes - every PR gets a review comment written to be read by one |
| Run the planner without your own LLM API key | Yes - it runs on managed Autonoma credits |
If something you need is missing, tell us in the in-app chat. Knowing what people are blocked on is how this list gets shorter.
## Setting up
### The onboarding is stuck on step 1 after installing the GitHub App
Usually the app was installed by someone else - an organization owner approving the request - or straight from GitHub rather than from a link in Autonoma, so the install was never tied back to a workspace.
Sign in to Autonoma and you will land on **Add your app**, with a note saying the app is installed on GitHub but not yet connected to a workspace. Click **Install GitHub App** and pick the same GitHub account. GitHub sees the app is already installed there, so it only asks you to confirm - nothing is installed twice - and you come back connected.
Do this while the installation is still fresh. Autonoma only connects an installation that GitHub created in the last half hour, so that an old installation id cannot be pointed at the wrong workspace. If you leave it longer, you will be told the installation is too old to connect this way: uninstall the app from that GitHub account and install it again from Autonoma, which creates a new installation and connects immediately.
### I installed the GitHub App but Autonoma does not see my repository
Check the app’s repository access. If it was installed with **Selected repositories**, the repo you want has to be in that list. Use **Grant access to it on GitHub** on the GitHub settings page to add it - that opens the installation you already connected, so nothing else changes.
If the repository lives under a *different* GitHub account, see the next entry.
### Can I connect a second GitHub organization?
Not today. Autonoma connects one GitHub account per workspace, and every repository it reads goes through that one installation.
If you try to install Autonoma on a second GitHub account, the install is refused and your existing connection is left exactly as it was - you will see a message naming both accounts. Nothing breaks, and nothing needs undoing on your side beyond removing the installation you just created if you do not want it sitting there.
Two ways forward:
* **Keep the account you have** and grant its installation access to the repository you need, if the repository can be shared with it.
* **Move to the other account** by disconnecting the current one first, on the app’s GitHub settings page, and then installing on the account you want. Disconnecting unlinks every application’s repository, so only do this if you mean to move the whole workspace.
If the second account is already connected to a *different* Autonoma workspace, disconnect it there first - it cannot be connected to two workspaces at once.
### Can I delete an application and start over?
Not from the dashboard today. Ask in the in-app chat and we will remove it.
## The planner CLI
The planner is a command-line tool that reads your codebase and writes your test suite. It runs on your machine, not on ours. Full reference: [Test Planner](/test-planner/).
### Where do I run the command?
In your own terminal, from the root of the repository you want to test. The planner reads your code, so it has to be somewhere it can see it.
Copy the command from the **Upload test artifacts** step of onboarding - it comes with your token and generation id already filled in - and paste it into your terminal. It has this shape, with real values where the stand-ins are:
```bash
AUTONOMA_SHARED_SECRET= AUTONOMA_DISTINCT_ID= AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= npx @autonoma-ai/planner@latest
```
If your frontend and backend live in separate repositories, run it somewhere it can reach both, or point it with `--frontend` and `--backends`.
### It says my AUTONOMA\_API\_TOKEN is a placeholder
You ran an example rather than your own command. The snippets on this site write every credential as a stand-in - ``, `` - and pasting one unchanged sends that stand-in as your token, which authenticates nothing.
Your real command lives on your app’s connect screen at [autonoma.app](https://autonoma.app), with the token and ids already filled in. If you are running standalone, mint a key under **Settings → API keys** and set `AUTONOMA_API_TOKEN` to it yourself.
The planner checks this before it starts, so the run stops immediately instead of failing its first step over and over with nothing that explains why.
### It says my coding agent is on my PATH but could not be run
Your machine refused to execute it. The planner found the binary where it expected to - that is what “on your PATH” means - and the operating system declined to start it, which is a different problem from a missing or broken install. Reinstalling produces the same refusal.
On Windows this is usually an execution policy (AppLocker, Software Restriction Policies) or an endpoint-security agent blocking `cmd.exe`, which is what npm-installed CLIs are launched through. On Linux and macOS it is most often a `noexec` mount or a missing execute bit. Confirm it by running the agent on its own in the same terminal - `claude --version` or `codex --version`. If that is refused too, the planner was never the problem.
If you have a second agent installed, the planner switches to it by itself and carries on.
### It has been on the same step for ages - is it stuck?
Probably not. A full run takes **an hour or more**. Building the knowledge base is the slowest early step because it reads every page in your app.
The terminal dashboard shows you it is alive: the activity feed at the bottom logs each thing the agent does, and the pane on the right streams the file being written right now. If both have been frozen for a long stretch, that is worth reporting.
### I closed my terminal - do I have to start over?
No. Progress is saved continuously.
```bash
npx @autonoma-ai/planner@latest --resume # pick up where it stopped
npx @autonoma-ai/planner@latest status # see how far it got
```
`npx` does not install anything on your `PATH`, so a bare `autonoma-planner` will not work.
### The run finished but an artifact is missing
The **Upload test artifacts** step shows four chips - `recipe.json`, `qa-tests/`, `AUTONOMA.md`, `scenarios.md` - and will not complete until all four arrive. The one that most often does not is `recipe.json`, because it is produced and sent separately during the test-data step, while the other three go up together at the very end.
**Do not re-run the whole planner, and do not use `--resume`.** Every step already finished, so there is nothing to resume - it will print `All steps complete.` and exit without uploading. Re-send what is already on your disk instead:
```bash
AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= \
npx @autonoma-ai/planner@latest upload
```
The dashboard shows this exact command, with your values filled in, in the warning under the chips. It is idempotent, so it is safe to run more than once.
If `recipe.json` is still missing afterwards, it was never generated - the test-data step did not finish. That happens when no supported coding agent was available for the handoff, in which case the planner wrote the integration instructions to `~/.autonoma//integration-prompt.md`. Complete that, then run `upload` again.
### Does it commit anything to my repository?
The test suite, knowledge base, and scenarios are written to `~/.autonoma//` on your machine and uploaded to Autonoma. None of it is committed to your repo.
The one exception is the test-data step, which is real code: your coding agent implements the Environment Factory on **its own branch** and opens a pull request for you to review. Nothing lands on your default branch unreviewed.
### Where do I write the tests?
You do not. The planner generates them from your codebase as natural-language markdown - not Playwright or Cypress scripts - and uploads them itself.
### It is asking for an LLM API key
It should not be. The planner runs on managed Autonoma credits and needs no key of your own. Use `--model` to pick a different Autonoma-hosted model, still without a key. If something is prompting you for one, you are on an old version - re-copy the command from the dashboard.
## Test data
The Environment Factory is the endpoint that creates test data before each run. Its [error-code reference](/environment-factory/security/#error-codes) covers the full list; these two come up most in setup.
### `CONFIGURATION_ERROR` - shared secret and signing secret must be configured
Both `AUTONOMA_SHARED_SECRET` and `AUTONOMA_SIGNING_SECRET` have to be set in the environment where your backend actually runs.
The usual miss is setting them locally but not in the deployed app Autonoma is calling. Check the environment of the running service, not your shell. They must be two different values - see [the two secrets](/environment-factory/security/#the-two-secrets).
### `UNRESOLVED_TOKEN` - unresolved token `{{something}}`
Your recipe uses a `{{token}}` that nothing defines.
Every token in `create` needs a matching entry under `variables`, with one exception: [`{{testRunId}}` and `{{testRunShortId}}`](/reference/scenario-recipe-schema/#built-in-tokens) are built in and need no declaration. So `{{org_name_1}}` in a `create` block with no `org_name_1` variable fails the whole provisioning step.
Either declare the variable or fix the typo in its name.
## Runs and results
### What actually triggers a test run?
Pull request activity. Opening a PR, pushing to it, or reopening it builds the preview and runs the suite against it. Closing the PR tears the environment down.
A repository can also keep a standing main-branch environment, which redeploys on every push to that branch.
### Where is the preview URL?
Autonoma comments it on the pull request, and keeps that comment updated as the PR changes. One PR can expose several apps, each with its own hostname.
### My test generations have been pending for a long time
Generation runs behind the planner upload, so it will sit idle until the CLI finishes and uploads. If the upload has completed and generations still have not moved, that is a problem on our side - report it in the in-app chat with your organization name.
### The CLI says it uploaded, but the dashboard is empty
Try a hard refresh first (`Ctrl` + `Shift` + `R`). If it is still empty, report it - the CLI and the dashboard disagreeing is a bug, not something you can fix from your side.
## Billing and credits
Autonoma is **pay as you go**, metered in credits. New organizations start with a free balance, so you can run real tests before paying anything.
Credits are spent on generating tests, running them, and on the planner CLI. When you run low, buy a top-up under **Settings → Billing**, or turn on auto top-up to have it happen automatically at a threshold you set. That page also shows your current balance, split between subscription and top-up credits, and your full transaction history.
Rates are configured per organization, so the billing page is the source of truth for what your account is charged. For a quote, or if a purchased top-up has not appeared on your balance, ask in the in-app chat.
## Your code and your data
**Your code is not used to train models.** Autonoma does not train on customer codebases.
**Your codebase is not stored.** It is cloned when a test run or an analysis needs to read it, used for that run, and not kept.
What is retained is **conversations** - agent runs, reviews, and support threads - which we keep for debugging and to improve the product. Those transcripts can quote fragments of your code where an agent read a file while working, so treat them as containing excerpts rather than nothing.
If you need this in writing for a review or an auditor, ask in the in-app chat.
## Still stuck
Use the in-app chat. Two things make it much faster to help:
* **Your organization or application name**, so we can find the right account.
* **The exact error text**, copied rather than described.
Never paste a signing secret, shared secret, or API token into the chat. We do not need it, and anything pasted into a support conversation should be rotated afterwards.
# Preview environments
> Vercel-style preview environments for every pull request. Configure your stack in the Autonoma dashboard, open a PR, get a live URL.
Preview environments give every pull request its own live, isolated, full-stack preview of your app. They're the foundation Autonoma reviews run against - and the first thing you set up when you connect a repo.
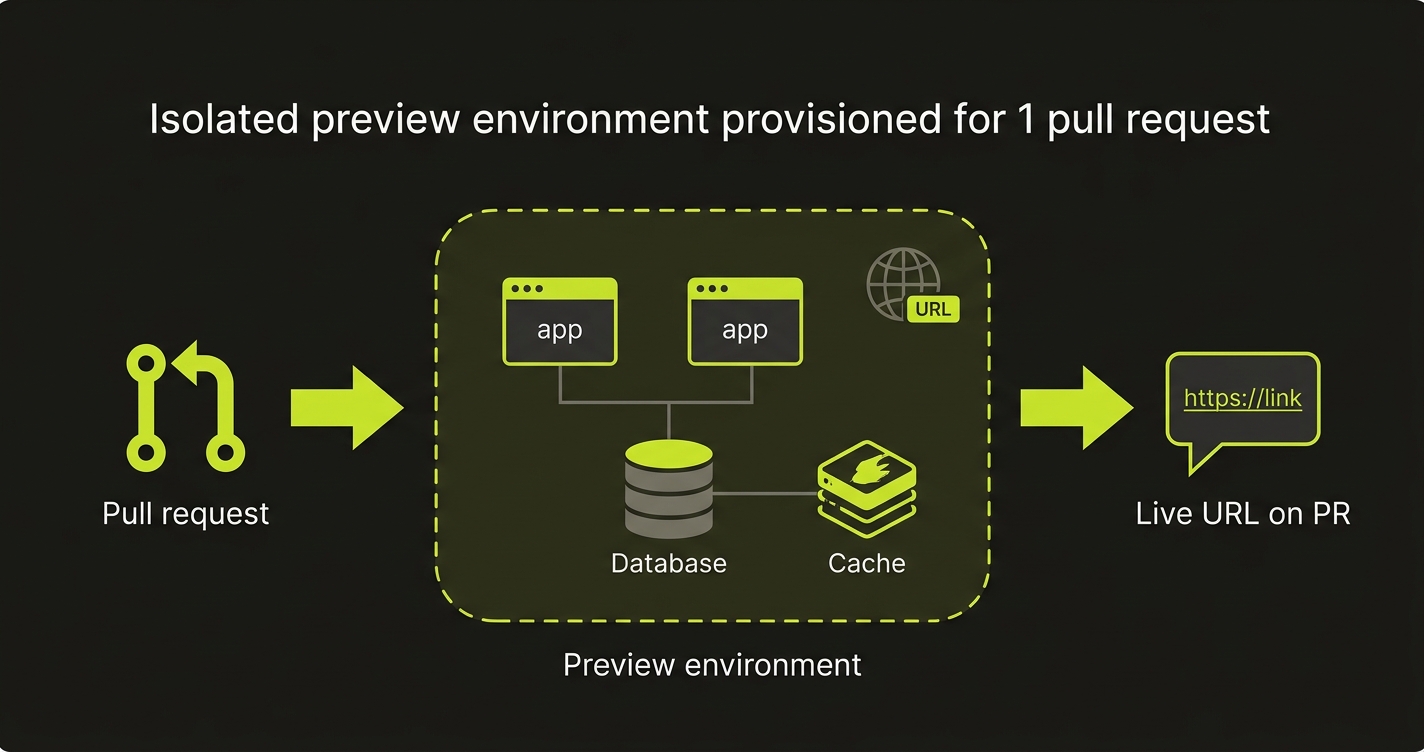
You describe your stack once - apps, the databases they need, and their environment variables - and Autonoma handles the rest: building the containers, provisioning the databases and extra services, running setup tasks, wiring environment variables, and posting the URL back to the PR.
> **Note:**
>
> Already build a preview for every pull request? You can connect those instead, and Autonoma will build nothing - see [Use your own deploys](/preview-environments/your-own-deploys/). Which to pick comes down to whether a test run can leave data behind in a shared database; that page has the trade-off. The rest of this section describes the Autonoma-hosted path.
## How it works
Once the Autonoma GitHub App is installed on your repository, every `pull_request` event triggers the pipeline:
1. **Opened / synchronized / reopened** - Autonoma fetches the head commit, builds each app, provisions the databases and extra services it needs, runs the database setup tasks, deploys to a dedicated Kubernetes namespace, and comments the preview URL on the PR.
2. **Ready for review** - a draft PR gets no preview by default, so marking it ready is what first builds one.
3. **Closed** - Autonoma deletes the namespace and all resources tied to that PR, then updates the comment.
Draft pull requests are skipped deliberately, to avoid building a preview for work still in progress.
Each preview gets a stable, unguessable URL - a short hash derived from the service name, PR number, and repo, so the same PR always resolves to the same address. One PR may expose several apps, each with its own hostname under `preview.autonoma.app`.
A repository can also have a standing **main-branch environment**: a preview deployed from the repository’s main branch instead of a PR. Once it exists, every push to that branch redeploys it at the new head automatically, the same way a new commit updates a PR’s preview.
## What you configure
You set up your stack in the Autonoma dashboard (the preview environment onboarding flow), which saves the configuration for your repository. The flow leads with a coding agent: pair your agent to the app and it fills the configuration in for you, while you watch read-only. See [Set up a preview with a coding agent](/mcp/configure-preview/) for that path - the rest of this section describes what it is configuring, and applies either way.
To fill it in yourself, decline the agent twice: **Answer a few questions instead** on the preview step (a short questionnaire about your stack, which is what routes you to this path), then **Configure manually** on the config step that follows. The manual flow has three required steps - **Apps**, **Database**, and **Variables** - plus two optional pieces most projects never need. A final **Finish** screen confirms the configuration, where **Save and deploy** builds it. It declares:
* **Apps** to build and deploy (each becomes a public HTTPS URL) - see [Apps and builds](/preview-environments/apps/)
* **Databases** the apps need (Postgres, MySQL, MongoDB, Redis / Valkey), each with guided setup for schema, seed data, and migrations - see [Databases](/preview-environments/databases/)
* **Variables** - environment variables and secrets for each app and database, with templates that resolve hostnames at deploy time and a per-variable **Source** control choosing whether a value is a stored secret or a connection to something else in the preview
* **Extra services** (optional) - non-database Docker images like Sentry or an OTel collector - see [Extra services](/preview-environments/services/)
* **Lifecycle hooks** (optional) - commands that run around each deploy - see [Lifecycle hooks](/preview-environments/hooks/)
Extra services and lifecycle hooks sit off the main path: the flow finishes at Variables, and you reach them only if your setup needs them.
## The setup flow, end to end
Connecting a repository walks through three phases, shown across the top as **Create app**, **Config previews**, and **Test data**:
| Phase | What happens |
| ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| **Create app** | Install the Autonoma GitHub App, pick the repository, and name the application. |
| **Config previews** | A short set of questions works out which setup fits - whether you already deploy previews per branch, where your backend runs, and how your data is scoped. From there you either connect deploys you already have, or configure PreviewKit to build them. Then Autonoma deploys one and verifies it is reachable. |
| **Test data** | Upload test artifacts with the [planner](/test-planner/), implement the [Environment Factory](/environment-factory/), and dry-run your scenarios. |
The button to know about is **Start generating tests**, at the end of Config previews. Pressing it does two things at once: it takes the app live, so Autonoma begins reviewing pull requests, and it moves you into the **Test data** phase. There is no separate screen that turns reviews on.
It does not end onboarding. Test data is the third phase of the same flow, and it is what lets Autonoma provision real data for your tests. Onboarding is one continuous flow with no way out until all of it is done, so plan to run it in one sitting - and note that the planner upload alone usually takes over an hour, since it reads your whole codebase to generate the suite.
## How apps are built
Each app builds one of two ways, chosen per app:
* **Manual** - pick a runtime (Node, Python, Go, and more), then write a short bash build script and an entrypoint. No Dockerfile required.
* **Dockerfile** - point Autonoma at an existing Dockerfile in your repo, built with [BuildKit](https://github.com/moby/buildkit).
Either way, images are pushed to a private registry and pulled by the preview cluster - you never touch credentials. See [Apps and builds](/preview-environments/apps/) for the full reference.
## Secrets
Secrets such as API keys and third-party tokens are stored encrypted and kept out of your stack configuration. Flag any value as a secret with the **Source** control in the onboarding **Variables** step, or manage them out-of-band via the REST API (handy for CI and rotating values without editing the config). A secret belongs to an application (or to the organisation), and every preview of that application sees it - there is no per-PR scoping. Autonoma also injects a few [built-in environment variables](/preview-environments/secrets/#built-in-environment-variables) (`AUTONOMA_PREVIEWKIT`, `AUTONOMA_PREVIEWKIT_PR`, `AUTONOMA_PREVIEWKIT_URL`) into every preview so your app can detect it’s running in a preview. See [Secrets](/preview-environments/secrets/).
## What’s next
* [Apps and builds](/preview-environments/apps/) - build methods, runtimes, and per-app settings
* [Databases](/preview-environments/databases/) - engines, guided setup tasks, and where they run
* [Extra services](/preview-environments/services/) - non-database side containers
* [Lifecycle hooks](/preview-environments/hooks/) - commands that run around each deploy
* [Multiple repositories](/preview-environments/multirepo/) - pull apps from more than one repository
* [Manage secrets](/preview-environments/secrets/) - REST API reference
* [Use your own deploys](/preview-environments/your-own-deploys/) - connect previews your pipeline already builds
# Use your own deploys
> Connect the preview environments your pipeline already builds. Autonoma deploys nothing - your pipeline makes one signed call when a preview is live, and Autonoma runs its tests against that URL.
If your project already builds a preview for every pull request, Autonoma does not need to build another one. Point it at the previews you have: your pipeline makes one signed HTTP call when a preview goes live, and Autonoma runs its tests against that URL.
This is the alternative to [Autonoma-hosted preview environments](/preview-environments/). You choose between them during onboarding - either by answering a short questionnaire or by letting a coding agent decide from your repo - and you can still switch while you are setting up.
On this path Autonoma builds nothing, provisions nothing, and holds no stack configuration for your app. There is no Dockerfile to point at and no database to declare. The entire integration is the one call described below.
## Which path to pick
The question is not “do previews already exist” - it is **where the test data lands**.
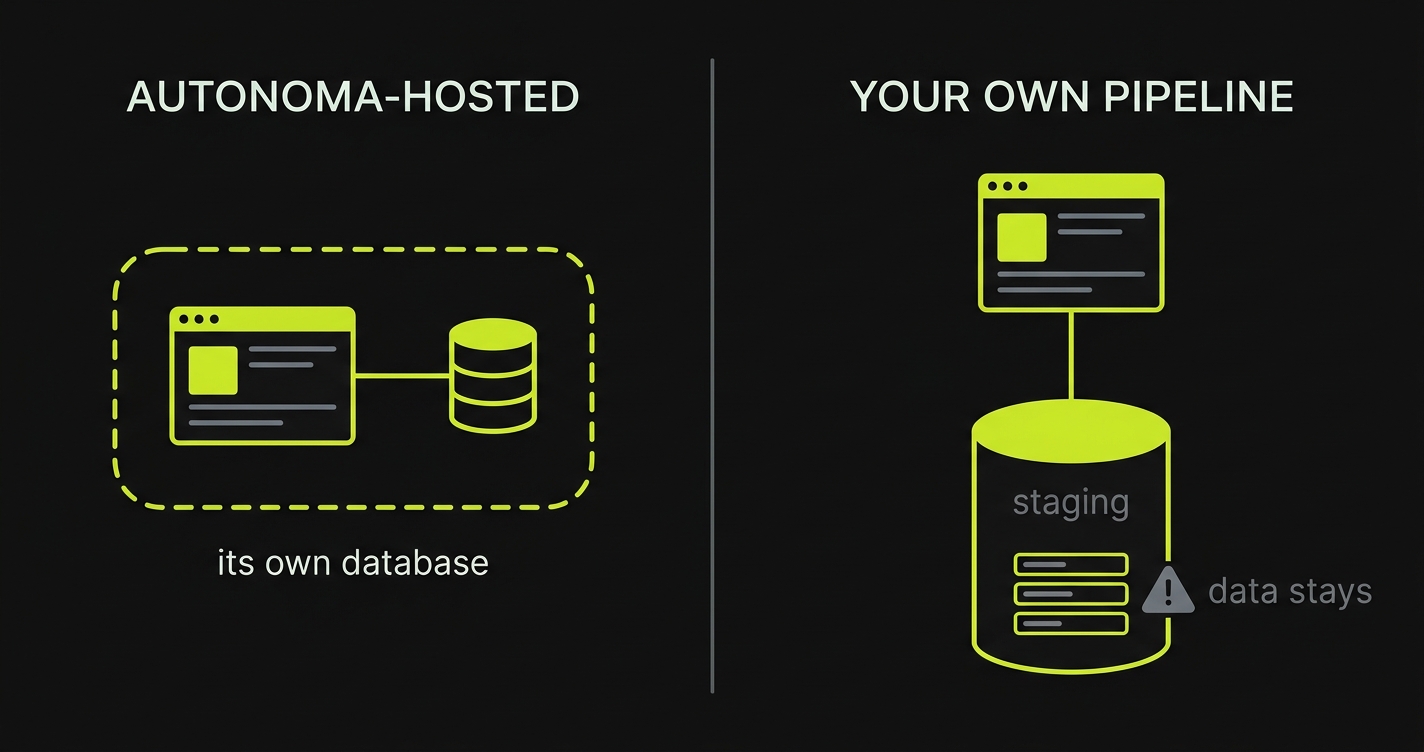
An Autonoma-hosted preview gets its own database, so a test run creates and destroys rows in an environment nothing else shares. Your own previews usually point at a real shared database - commonly staging, sometimes production. A test run writes into it, and anything it creates that no tenant owns **stays there**. Picture a marketplace whose previews share one database: a run creates listings, and real users see them.
| Your situation | Pick |
| ----------------------------------------------------------------------------------------------------- | ------------------------------------------------------ |
| No preview environments today | Autonoma-hosted - there is nothing to connect to |
| Previews today, and every row hangs off a tenant (an org, account, or workspace you can delete whole) | Either. Your own is less to change |
| Previews today, but the data is **not** cleanly tenant-scoped | Autonoma-hosted, despite the previews you already have |
| Not sure | Autonoma-hosted |
The two mistakes are not symmetrical. Choosing Autonoma-hosted when you did not need to costs a preview environment we build for you anyway. Choosing your own pipeline when your data is not tenant-scoped writes test data into your real database, in front of your users, and it cannot be taken back.
Autonoma-hosted is therefore the default, and it is the one a coding agent will pick on its own.
**A coding agent will never choose this path for you.** It is available on any host - Vercel or the signed webhook below - but it always takes your own decision, so the agent has to pass your answer back before Autonoma will accept it.
What differs is whether it raises the option. On Vercel our integration makes it a genuine choice, so the agent will ask. Anywhere else it will set up Autonoma-hosted previews and say nothing about this path; ask for it and it will explain both sides first. Either way you can pick it yourself in the Autonoma UI, which routes on the same questions.
> **Note:**
>
> “Tenant-scoped” means a test can create everything it needs underneath one deletable owner. If a test signs up an organization, works inside it, and deleting that organization removes every row it touched, you are tenant-scoped. Global tables that all tenants read - a shared product catalogue, a public listings table, a global search index - are what break this.
## The contract
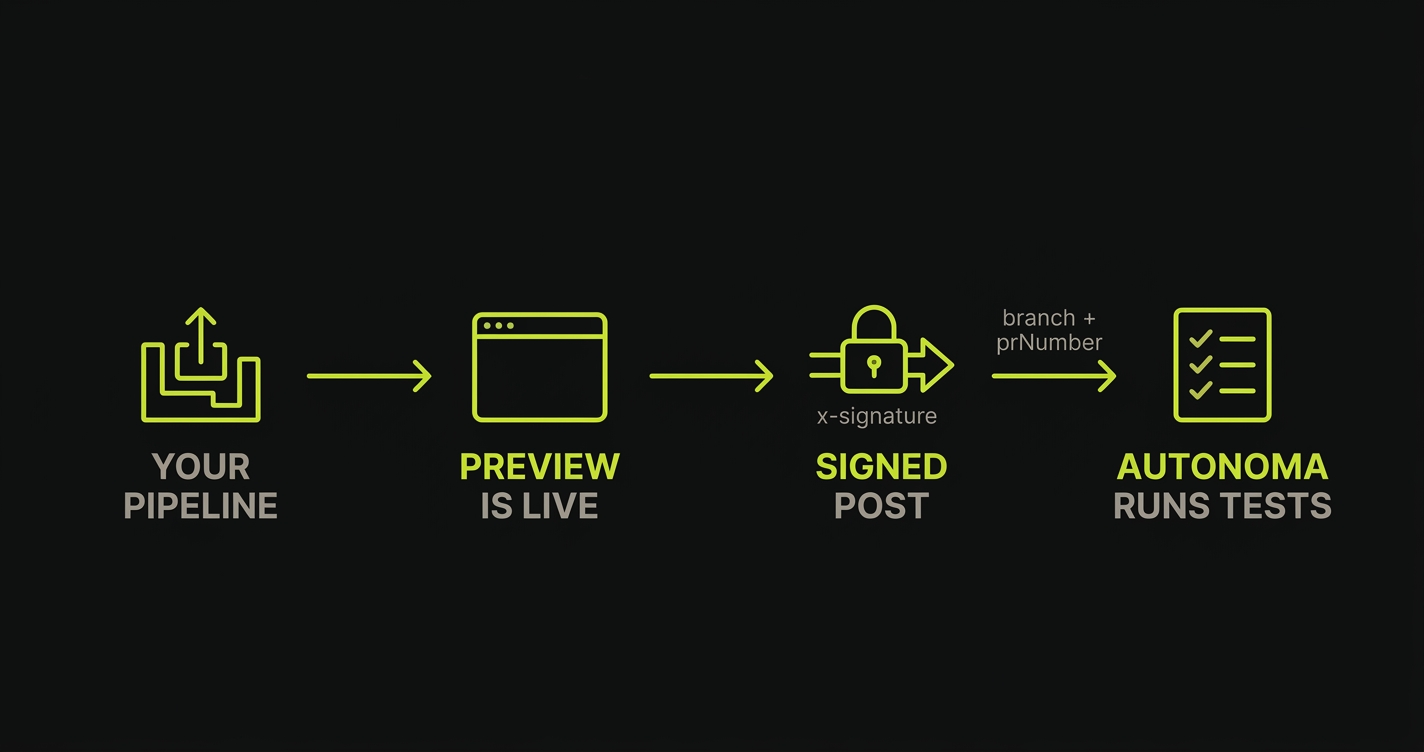
One `POST`, signed with a shared secret:
| | |
| ------------- | ------------------------------------------------------------------------------------------------------------ |
| **Endpoint** | `https://api.autonoma.app/v1/onboarding/deployment-signal` |
| **Method** | `POST`, `content-type: application/json` |
| **Signature** | `x-signature: ` - HMAC-SHA256 of the **exact raw body bytes**, keyed with your shared secret |
| **Secret** | Shown on the **Connect your deploys** onboarding step; store it as `AUTONOMA_SHARED_SECRET` in your pipeline |
Sign the exact bytes you send. Serializing the JSON a second time after signing - a re-`JSON.stringify`, a formatter, a proxy that rewrites the body - changes the digest, and the call is rejected.
### Body
| Field | Required | What it does |
| --------------- | -------- | --------------------------------------------------------------------------------------------------------------- |
| `applicationId` | yes | The app this preview belongs to. Shown on the onboarding step |
| `previewUrl` | yes | The URL Autonoma opens in a browser |
| `branch` | pair | The deployed branch. Send **with** `prNumber` |
| `prNumber` | pair | The pull request number. Send **with** `branch` |
| `sdkUrl` | no | Only when your [Environment Factory](/environment-factory/) endpoint is on a different origin than `previewUrl` |
| `sha` | no | The deployed commit |
| `provider` | no | Free-text label for where the deploy came from |
`branch` and `prNumber` travel together, and this is the detail most worth getting right:
* **Neither** - the signal is recorded as a main-branch deploy. Fine for the standing preview of your default branch.
* **Both** - Autonoma reviews that pull request. This is what turns a signal into a per-PR review.
* **`branch` without `prNumber`** - the signal is **dropped entirely**. Never send one without the other.
### Only signal the app Autonoma should browse
If one pull request deploys several things - a frontend, an API, a database - signal only the one Autonoma should open in a browser. Every signal overwrites the stored preview URL, so signalling all of them means whichever deploy finishes last wins, and that may well be your API rather than your frontend.
## A starter workflow
The **Connect your deploys** step hands you a GitHub Actions workflow, and your coding agent can fetch the same one over MCP. Treat it as a **template, not a requirement**.
It hangs off GitHub’s `deployment_status` event, which is convenient when your host reports deployments back to GitHub - and which plenty of pipelines never emit. Autonoma requires only the signed call. If your project does not emit `deployment_status`, do not bend your pipeline to fit the sample: make the same call from whatever step already knows a preview is live - a deploy job, a post-deploy script, your host’s own webhook.
.github/workflows/autonoma-preview\.yml
```yaml
name: Autonoma preview signal
on:
deployment_status:
jobs:
notify:
if: github.event.deployment_status.state == 'success'
runs-on: ubuntu-latest
steps:
- name: Notify Autonoma
env:
AUTONOMA_SHARED_SECRET: ${{ secrets.AUTONOMA_SHARED_SECRET }}
AUTONOMA_ENDPOINT: https://api.autonoma.app/v1/onboarding/deployment-signal
AUTONOMA_APPLICATION_ID: your-application-id
PREVIEW_URL: ${{ github.event.deployment_status.target_url }}
PREVIEW_SHA: ${{ github.event.deployment.sha || github.sha }}
run: |
BODY=$(jq -nc \
--arg applicationId "$AUTONOMA_APPLICATION_ID" \
--arg previewUrl "$PREVIEW_URL" \
--arg sha "$PREVIEW_SHA" \
--arg provider "custom" \
'{applicationId:$applicationId,previewUrl:$previewUrl,provider:$provider}
+ (if $sha == "" then {} else {sha:$sha} end)')
SIG=$(printf '%s' "$BODY" | openssl dgst -sha256 -hmac "$AUTONOMA_SHARED_SECRET" -hex | sed 's/^.* //')
curl -sS -X POST "$AUTONOMA_ENDPOINT" \
-H "content-type: application/json" \
-H "x-signature: $SIG" \
--data "$BODY"
```
Copy it from the onboarding step rather than from here - that copy has your real `applicationId` filled in.
Note what this sample does **not** send: `branch` and `prNumber`. As written it records a preview URL but never asks for a pull-request review. Adding them is the main edit most projects make - on a pull-request deploy, look the PR up (`gh api` from the workflow, or whatever your pipeline already knows) and send both.
Put the secret in your pipeline’s secret store rather than committing it:
```bash
gh secret set AUTONOMA_SHARED_SECRET
```
## Verifying it works
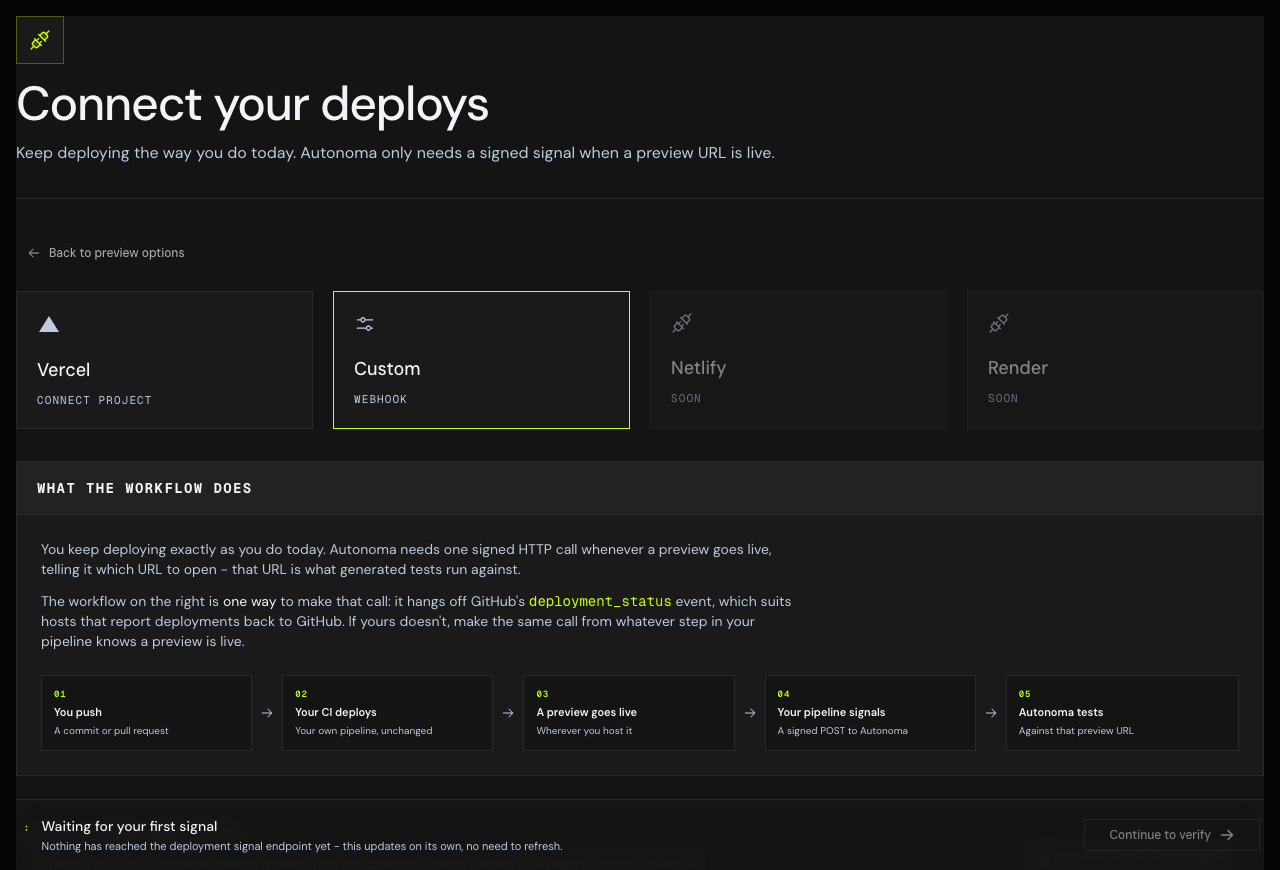
The onboarding step waits for your first real signal and unlocks **Continue** only once one arrives. That gate is deliberate: a signal is the only proof the wiring works.
Prove it with an actual run of your pipeline - push the branch and let it deploy. A hand-written `curl` proves your `curl` works, not that your pipeline calls us.
Watch for two separate milestones:
1. **A signal landed.** The wiring is correct and Autonoma has a preview URL.
2. **A signal carried a `prNumber`.** Until this happens, your app records preview URLs but no pull request is ever reviewed - which is the thing you are actually here for. A main-branch signal alone is not a finished integration.
## Do it with a coding agent
Your agent can do all of this - read how your pipeline actually deploys, write the call into the right step, open a pull request, and poll Autonoma until it sees a real signal land. Run the command Autonoma gives you during onboarding; it starts your agent on the job. See [set up a preview with a coding agent](/mcp/configure-preview).
See [Set up a preview with a coding agent](/mcp/configure-preview/) for the install and the tools it uses on this path: `get_signal_setup`, `get_signal_status`, `confirm_signal_setup`, and `go_live` to take the app live.
## After the preview is connected
From here the two paths converge. Autonoma has a URL, and the rest of onboarding is identical:
* [Environment Factory](/environment-factory/) - the `/api/autonoma` endpoint that creates and tears down each test’s data
* [Scenario recipes](/reference/scenario-recipe-schema/) - the JSON your handler follows to build that data
## Troubleshooting
**Every call comes back rejected.** The signature is over the raw bytes you POST. If you build the body, sign it, and then re-serialize it before sending, the digest no longer matches. Sign and send the same string.
**Signals land but no pull request is reviewed.** Your call is not sending `prNumber`. Check `branch` and `prNumber` go together on pull-request deploys.
**A signal was accepted and then nothing happened.** A signal carrying `branch` without `prNumber` is dropped by design. Send both or neither.
**The preview URL points at the wrong service.** More than one deploy in the pull request is signalling. Signal only the app Autonoma should browse.
**Autonoma opens a stale URL.** Every signal overwrites the stored URL, so the last one to arrive wins. If your pipeline signals from several jobs, keep the one that deploys the app under test.
# Apps and builds
> How Autonoma turns each app in your repo into a running container - the build method, the runtime catalog, build context, and the per-app settings.
An app is the unit Autonoma builds and deploys: a piece of your repo that becomes a container with its own public HTTPS URL in every preview. This page covers how each app is built and the settings on its card.
Most projects have one app - your web server. A repo can declare several (a frontend, an API, a worker), and each is configured the same way: pick how it builds, then fill in a few fields about how it runs.
## Build method
Every app builds one of two ways, chosen with the **Build method** toggle at the top of the app card:
| Method | Use it when | What you provide |
| -------------- | ------------------------------------------------------------------- | -------------------------------------------------------------------- |
| **Manual** | You don’t have a Dockerfile, or you want a fast, transparent build. | A runtime (Node, Python, …), a bash build script, and an entrypoint. |
| **Dockerfile** | Your repo already has a Dockerfile you trust. | The path to that Dockerfile. |
Manual is the default because it needs nothing in your repo - you pick a language and describe the build in two boxes.
### Manual builds
A manual build starts from a language image, installs your dependencies with a build script, and runs your app with an entrypoint. You pick a **runtime** from the catalog:
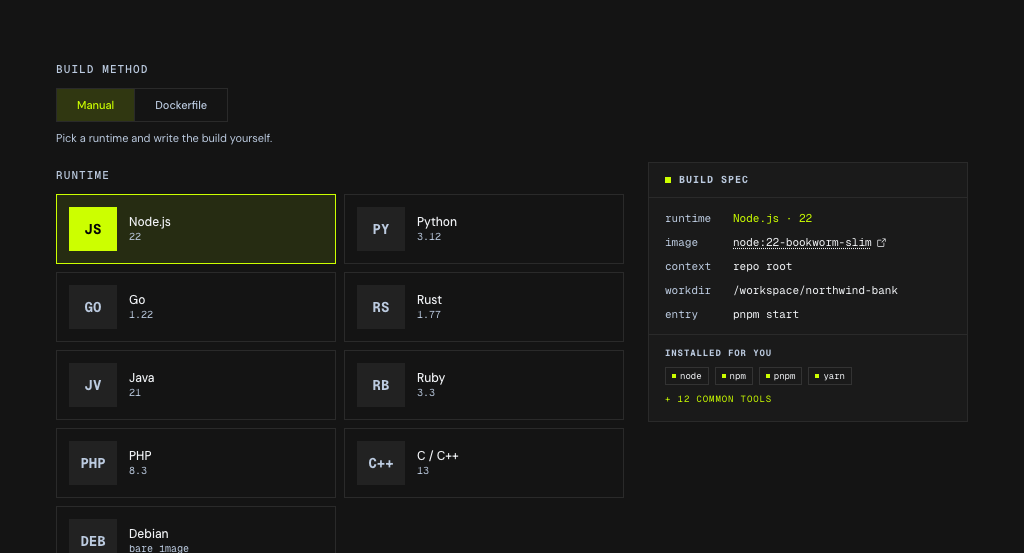
The **Build spec** rail on the right is live: it resolves the base image, context, working directory and preinstalled toolbelt as you choose, so you can see what you are about to get before you deploy.
| Runtime | Base image | Default version |
| ------- | -------------------------------- | --------------- |
| Node.js | `node:{version}-bookworm-slim` | 22 |
| Python | `python:{version}-slim-bookworm` | 3.12 |
| Go | `golang:{version}-bookworm` | 1.22 |
| Rust | `rust:{version}-slim-bookworm` | 1.77 |
| Java | `eclipse-temurin:{version}-jdk` | 21 |
| Ruby | `ruby:{version}-slim-bookworm` | 3.3 |
| PHP | `php:{version}-cli-bookworm` | 8.3 |
| C / C++ | `gcc:{version}-bookworm` | 13 |
| Debian | `debian:{version}-slim` | bookworm |
Pick **Debian** when you want a bare base image and will install everything yourself. Any published tag works in the **Version** field - the default is only a starting point, so a repo pinned to an older toolchain is never forced onto ours.
Two boxes describe the build:
* **Build script** - bash that runs at image build time, from the repo root. Selecting a runtime prefills a sensible default (for Node, `npm install` then `npm run build`). It’s optional - leave it blank for an app that needs no build step.
* **Entrypoint** - the command that starts the container (for Node, `npm start`).
The **Build spec** panel on the right previews exactly what you’ll get: the runtime and version, the resolved image, the build context (**the repo root**), the working directory (`/workspace/`), and the entrypoint. Because a manual build copies the whole repo, you don’t set a Path or build context for it - the build script and entrypoint define everything.
Every manual runtime also ships a common toolbelt so your scripts have what they need without an install step: `git`, `curl`, `wget`, `jq`, `rg`, `make`, `ssh`, `tmux`, `sqlite3`, `tar`, `zip`, and `unzip`, plus the language’s own tools (for Node, `npm`, `pnpm`, and `yarn`).
### Dockerfile builds
If your repo already has a Dockerfile, pick **Dockerfile** and give its path. Autonoma builds it with [BuildKit](https://github.com/moby/buildkit), pushes the image to a private registry, and pulls it into the preview - you never handle registry credentials.
The Dockerfile path is resolved **relative to the build context**, which is where the two location fields below come in.
## Dockerfile build settings
These fields appear only for Dockerfile builds (a manual build always uses the repo root):
* **Path** - the directory of the app inside the repo, e.g. `apps/web`. It sets the default build context and is checked to exist in your repo. In a single-app repo, leave it blank for the root.
* **Root directory** - the Docker **build context**: the folder Docker builds from, and everything a `COPY` in your Dockerfile can read. Leave it blank to inherit **Path**; set it explicitly when a Dockerfile deeper in the repo needs to `COPY` files from higher up.
* **Start command** - overrides the container’s default start command.
For a monorepo web app whose Dockerfile lives at `apps/web/Dockerfile` but copies a shared `packages/` folder from the repo root, set Path to `apps/web`, Root directory to `.` (the repo root - not blank, since blank inherits Path), and the Dockerfile path to `apps/web/Dockerfile` (it resolves relative to the build context).
## Per-app settings
A few fields apply to every app, whichever build method you pick:
| Field | What it does |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Name** | Lowercase identifier used in resource names and the preview URL. |
| **Repository** | The GitHub repository (`owner/repo`) the app builds from. Defaults to the repository you open pull requests against; any other value pulls the app from a [connected repository](/preview-environments/multirepo/). |
| **Port** | The port your app listens on inside the container. |
### The frontend app
When a project has more than one app, one is marked the **frontend** with a toggle. The frontend is the app Autonoma’s agents open in the browser to test, and its URL becomes the preview’s primary URL. Each project has exactly one frontend; the others still get their own URLs but aren’t the entry point.
### The SDK app
A second toggle marks the app that serves your [Environment Factory](/environment-factory/) handler at `/api/autonoma`. That’s where Autonoma sends the `up` and `down` calls that seed and clean up test data before each run, so it has to point at the app whose code actually mounts the handler.
It’s independent of the frontend toggle. A full-stack app (Next.js, Rails, Django) serves the pages the agents browse *and* the handler, so it carries both. A split project marks the browser-facing app as the frontend and the API service as the SDK app.
The handler can live in a [connected repository](/preview-environments/multirepo/) too - a frontend project whose API is a separate repo marks that repo’s app as the SDK app, and Autonoma targets it.
Leave it unset and Autonoma falls back to the frontend, which is right for a single-app project - but in a split project it sends every `up` to an app with no handler, and scenario setup fails with a 404.
### Depends on
Once your project pulls in a [connected repository](/preview-environments/multirepo/), each app gets a **Depends on** control for start ordering: the app waits for the apps and services it lists before it starts. Use it when, for example, your frontend shouldn’t boot until an API from another repository is reachable.
## Next steps
* [Environment variables and secrets](/preview-environments/secrets/) - wire config and credentials into each app
* [Multiple repositories](/preview-environments/multirepo/) - pull apps from more than one repository into the same preview
# Databases
> Add every database your preview needs - Postgres, MySQL, MongoDB, Redis / Valkey - each with its own engine, version, and repo-aware setup tasks for schema, seed data, and migrations.
A database is a first-class part of every preview: pick the engines your app needs, and Autonoma runs the schema, seed, and migration steps that bring each one to life, from one of your own apps' images - so the files and tooling those steps depend on are the ones your app already has.
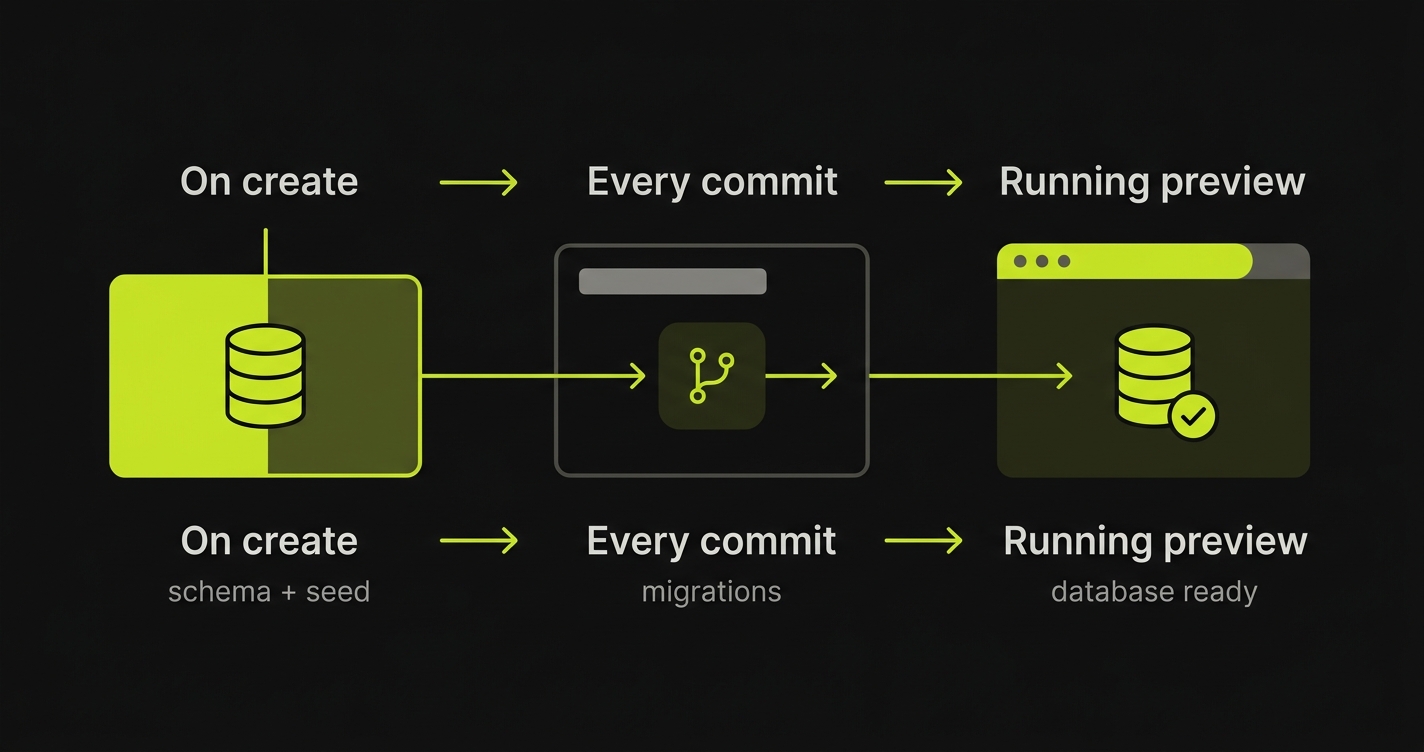
Databases are their own step in onboarding. Most apps declare at least one; many declare several. Add as many as your app needs - each gets its own card and its own setup.
## Add the databases your app needs
A preview can run more than one database at once - Postgres for your data, Redis for your cache, Mongo for a document store - side by side. You add each from the engine palette, and each becomes an independent card where you choose a **version**:
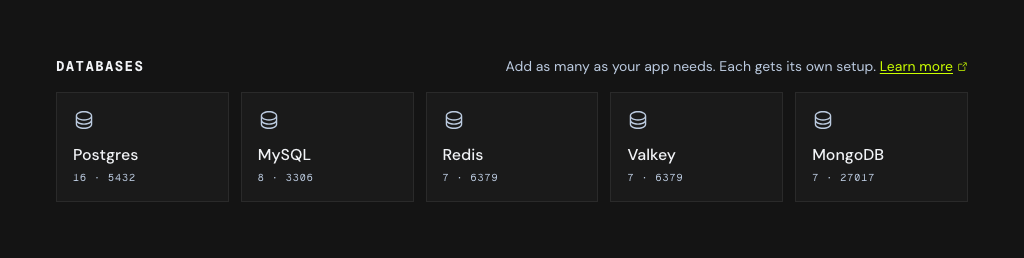
| Engine | Default port | Example version |
| -------- | ------------ | --------------- |
| Postgres | 5432 | 16 |
| MySQL | 3306 | 8 |
| MongoDB | 27017 | 7 |
| Redis | 6379 | 7 |
| Valkey | 6379 | 7 |
The engine sets the default port and pulls the right image; the **Version** field pins the exact tag, so a repo on an older engine is never forced onto ours. The **Name** is filled in for you (`db`, `cache`, `mongo`, …) and is what the connection string uses - edit it if you want a different one. Add a card per database, and the preview brings them all up together.
Caches usually need no setup tasks. Add a version and you’re done - or add an on-create task if you pre-warm the cache.
## Setup tasks
An empty database rarely matches what your app expects. It needs tables, seed rows, and the migrations that have accumulated since. Those steps almost always live **in your repo** - a `db/schema.sql`, a `seed` script, a `migrate` command - not in the database image, which is built for production and often ships none of them.
So Autonoma runs each setup task as a one-off job **from one of your apps’ built images**, and you choose which app. That image is what the command sees.
For an app using the **Manual** build method this means your repo is right there - the build copies the repository in, so `psql < db/schema.sql` finds the file. For an app built from a **Dockerfile**, the command sees only what that Dockerfile put in the image. A production Dockerfile that copies build output and nothing else will not have `db/schema.sql`, so either use a task whose app has the file, or add it to the image.
Tasks are split by **when** they run, with sensible defaults you can override. Both sections are optional.
> **On create:**
>
> A run-once task is marked complete against the database, not against the task, and the volume survives redeploys. So editing a seed command - or adding a new run-once task to a database that already exists - will not re-run it on the next deploy. Recreate the preview, or move the work to a task that runs on every commit.
### Run once - on create
Schema and seed data go here - the tasks that bring a fresh database to life the first time it’s created. The command runs from the chosen app’s image, so `db/schema.sql` is available if that image contains it - which a Manual build does, since it copies the repository in.
```bash
# on create
psql < db/schema.sql
npm run seed
```
If your app already builds its own schema on boot, leave this section empty - or, once you’ve added tasks, **Skip - my app handles this** clears them in one click.
### Run on every commit / PR
Migrations go here, so every preview reflects the current branch:
```bash
# on every commit
npm run migrate
```
These run on every full preview deploy - each new commit pushed to the PR. A per-app redeploy from the dashboard re-rolls just that one app and does not re-run setup tasks, so reach for a full redeploy when you need migrations applied. Skippable too, if the app migrates itself on startup.
**Defaults, not rules.** Schema and seed belong on-create; migrations belong on every-commit. Nothing is forced, but a task’s group is fixed when you add it - you choose by which group’s **Add task** you press, so moving one means deleting it and adding it back in the other group.
## Where a task runs
Every setup task runs as a one-off job from a chosen app’s image, after the databases are up and before your apps start. What you choose is which app’s build the command borrows:
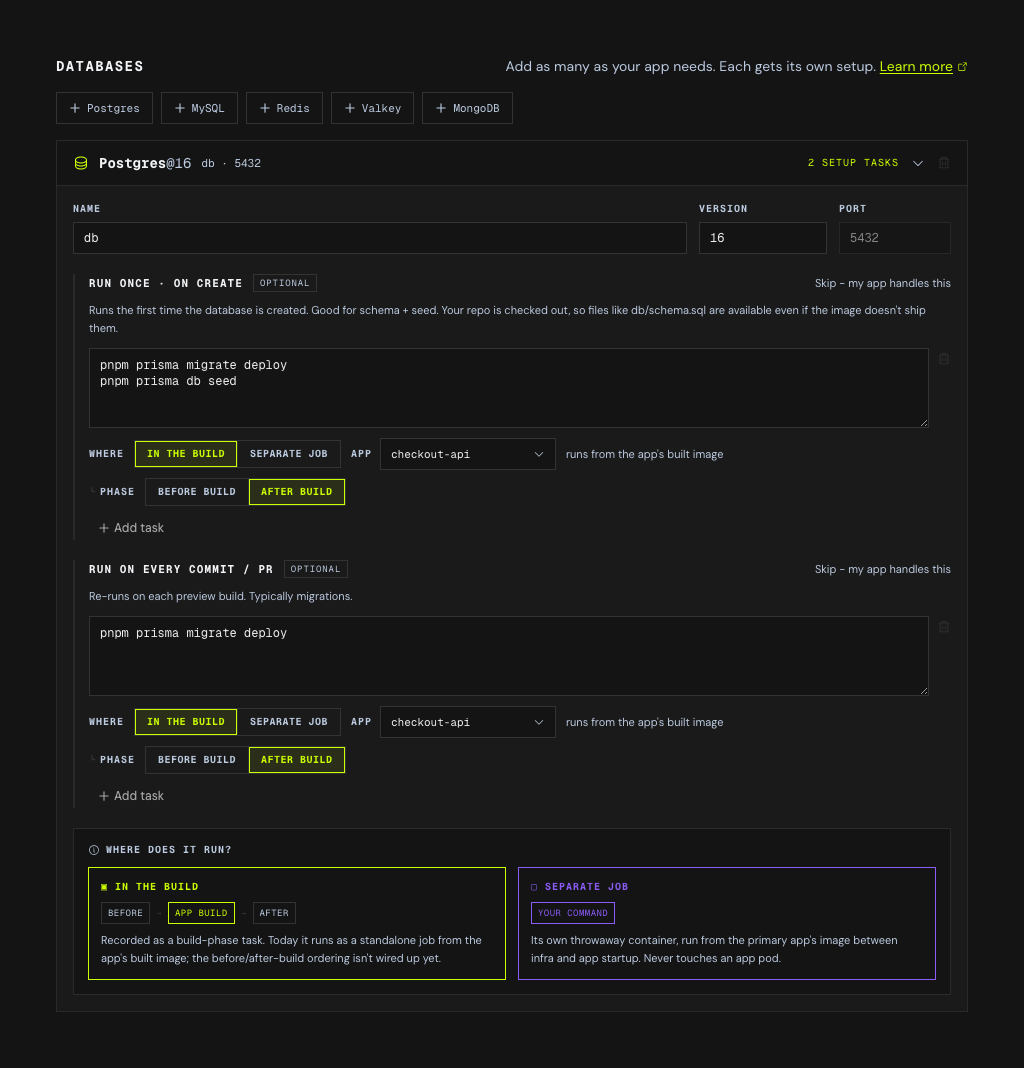
The **Where** control is per task, and the **Phase** row underneath only applies to *in the build* - a separate job has no build to sit before or after. The lime and violet in the explainer are the same colours the control uses, so you can read a configured task at a glance.
| | In the build | Separate job |
| ------------------------- | -------------------------------------------------------------------------- | ------------------------------------------- |
| **Image** | A chosen app’s built image | The primary app’s built image |
| **What the command sees** | That app’s image, including its build output | The primary app’s image |
| **Reach for it when** | The task needs a specific app’s build output or its installed dependencies | The task just needs the primary app’s image |
**In the build** runs the command from the app you pick, so the task sees that app’s image and everything its build produced - reach for it when a step depends on a particular app (a compiled asset, an installed CLI).
**Separate job** runs the same command against the primary app’s image, standing on its own - reach for it when a setup step just needs the repo and shouldn’t be tied to any one app.
## Which repository it runs against
An in-build task’s **App** picker chooses which app’s image the command borrows. It appears whenever the preview has more than one app - not more than one repository - so a single-repo project that deploys a frontend and an API will see it. With exactly one app the picker is hidden and that app is used. A separate **Repo** picker appears when the preview spans more than one [repository](/preview-environments/multirepo/).
The **before / after** position on an in-build task is recorded but not yet honored: every setup task runs as a standalone job between the databases coming up and the apps starting. An in-build task does use the app you picked; a separate job falls back to the primary app. So build-step ordering is captured for when that lands, but does not change anything today.
## Next steps
* [Apps and builds](/preview-environments/apps/) - how each app in your repo becomes a running container
* [Lifecycle hooks](/preview-environments/hooks/) - run commands at other points in a preview’s life
* [Multiple repositories](/preview-environments/multirepo/) - pull apps, and their databases, from more than one repository into a single preview
# Extra services
> Run non-database side containers - MinIO, a mock API server, a Mailpit inbox, an OTel collector - alongside your app in every preview. Optional, and only needed when your app depends on one.
Extra services are extra Docker images that aren't databases: things like MinIO for object storage, a mock API server, a Mailpit inbox, or an OpenTelemetry collector that run alongside your app in every preview. They're optional - most projects never need one.
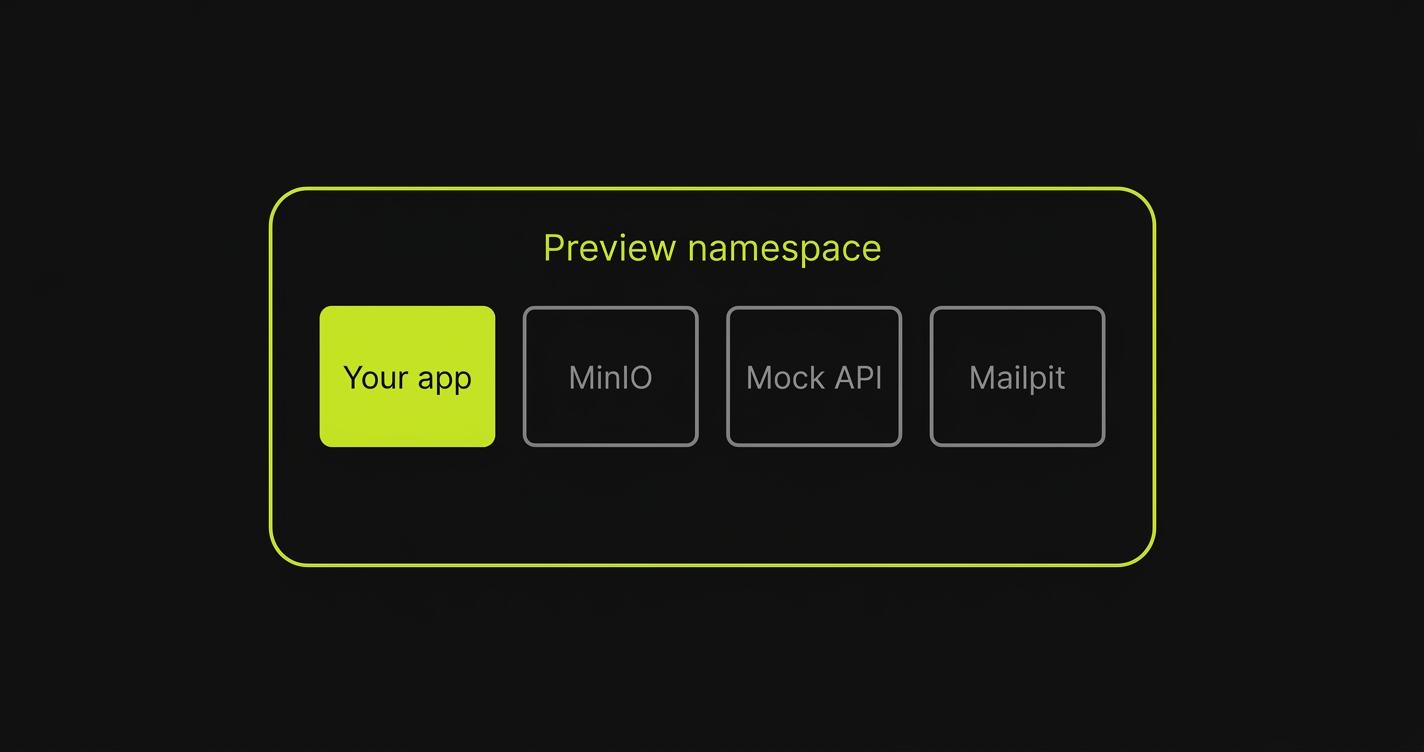
This step is optional. You don’t have to add anything here to complete onboarding. Only add an extra service if your app genuinely depends on a non-database side container running next to it.
## When to add an extra service
An extra service is any container your app needs that isn’t your app and isn’t a backing store. If your app talks to it over the network in a preview - and it’s not Postgres, Redis, or another database - it belongs here.
Common examples:
* **MinIO** - S3-compatible object storage, so uploads and file handling work in the preview.
* **Mock API server** (WireMock, Mockoon) - stubs a third-party API your app calls so previews don’t hit the real one.
* **Mailpit** - captures outbound email so tests can inspect it.
* **OpenTelemetry collector** - receives traces and metrics from your app.
* **nginx** - a reverse proxy or static file server in front of your app.
You can add **several**. If nothing on this list resembles your setup, skip the step.
## Configuring an extra service
Each extra service is one Docker image with a few fields:
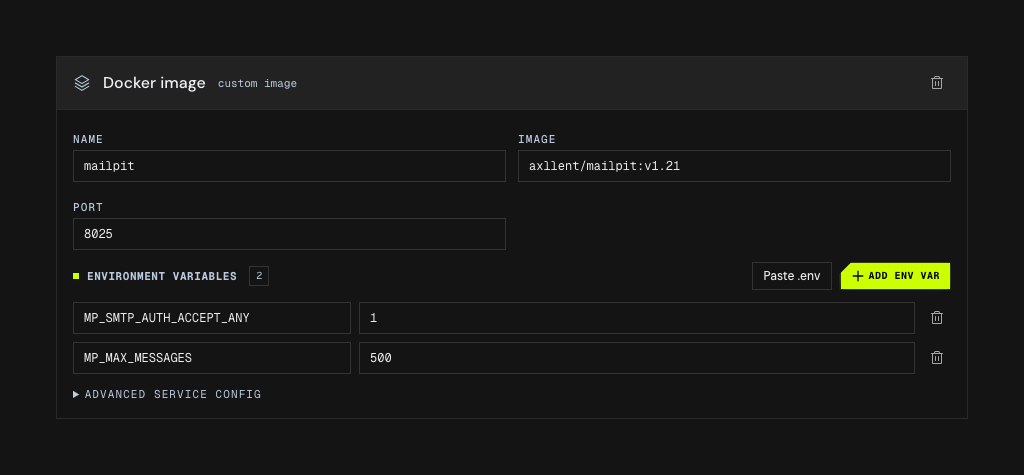
The env-var block takes a whole `.env` at once if you have one, and the rest of the fields stay out of the way behind the collapsed disclosure until you need them.
| Field | What it does |
| ------------------------- | ---------------------------------------------------------------------------------------------- |
| **Image** | The Docker image to run, e.g. `axllent/mailpit` or `otel/opentelemetry-collector`. |
| **Port** | The port or ports the service listens on, so your app and other services can reach it. |
| **Environment variables** | Config passed into the container. Use **Add env var** for each key/value pair the image needs. |
Set whatever the image expects through **Add env var** - a DSN, a collector config path, an SMTP hostname.
Add a service, fill in its image, ports, and any env vars, and repeat for each one your app depends on.
### Advanced service config
Most images need only an image, a port, and a few env vars. When one needs more, the **Advanced service config** section exposes the rest:
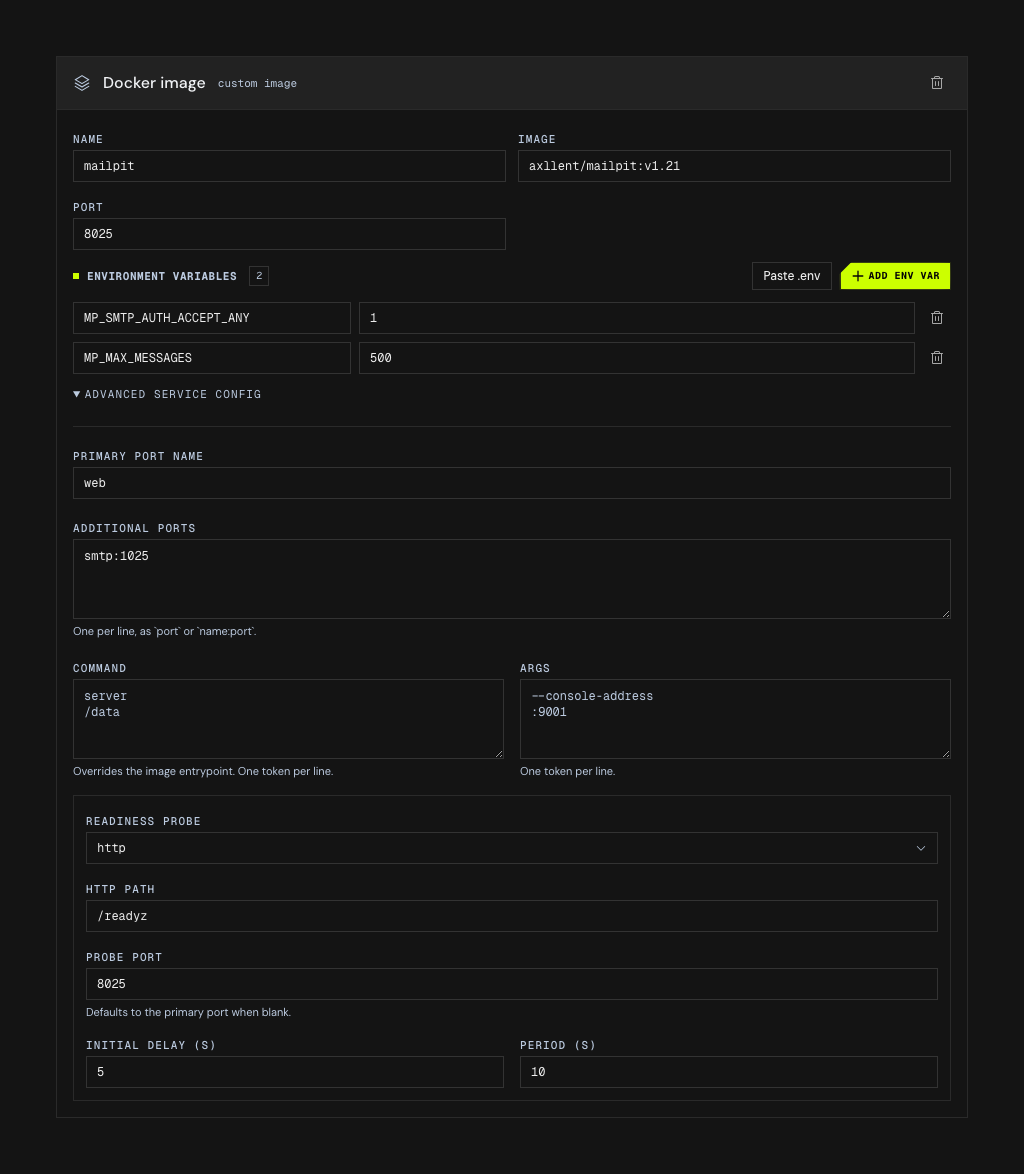
The readiness probe’s fields depend on the kind you pick - HTTP asks for a path, Exec asks for a command, TCP asks only for a port - so the section changes shape as you choose.
| Field | What it does |
| --------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Primary port name** | Names the main port (defaults to `primary`), for when a service references it by name. |
| **Additional ports** | Extra ports the container exposes, one `port` or `name:port` per line (e.g. `metrics:9090`). |
| **Command** | Overrides the image entrypoint, one argument per line. |
| **Args** | Arguments passed to the entrypoint, one per line. |
| **Readiness probe** | How the preview decides the service is up - **HTTP** (a path), **Exec** (a command, one argument per line), or **TCP** (a port). Set an optional initial delay and period in seconds; a blank probe port reuses the primary port. |
## Not for databases
Databases - Postgres, MySQL, MongoDB, Redis / Valkey - are not extra services. They live in their own required [Databases](/preview-environments/databases/) step, where Autonoma provisions and wires them for you, with guided setup for schema, seed data, and migrations. Reach for extra services only when you need a side container that a database step can’t provide.
# Connections
> Wire your apps to the databases, services, and other apps inside a preview with templated env vars that resolve at deploy time.
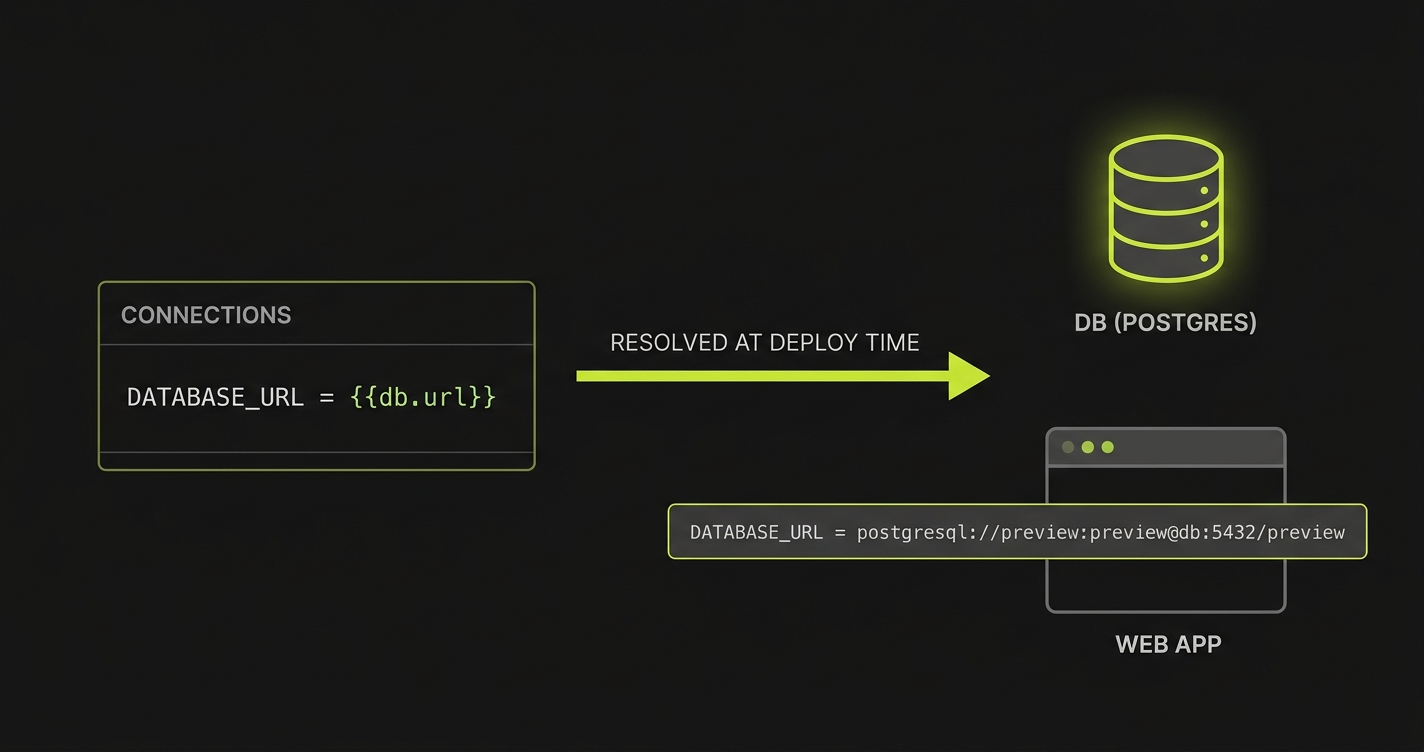
A connection is an env var whose value is a template resolved against the preview's own topology at deploy time - it's how an app learns the address of the database, cache, or sibling app that lives next to it in the preview.
Every preview is a fresh, isolated stack: your apps, databases, and services come up together in their own namespace, with addresses that don’t exist until deploy time. A production `DATABASE_URL` would point at the wrong database, and a hardcoded hostname can’t know the preview’s namespace. Connections close that gap: you write `{{db.url}}`, and every preview resolves it to that preview’s own database.
> **Databases are not auto-wired:**
>
> Declaring a Postgres service does **not** inject `DATABASE_URL` into your apps. A service is reachable only by the apps that declare a connection to it. If your app boots but the first query fails with `Environment variable not found: DATABASE_URL`, the database is up - your app just has no connection pointing at it.
## Wiring an app to a database
The one-token case covers most apps - `{{db.url}}` expands to the service’s full canonical connection string:
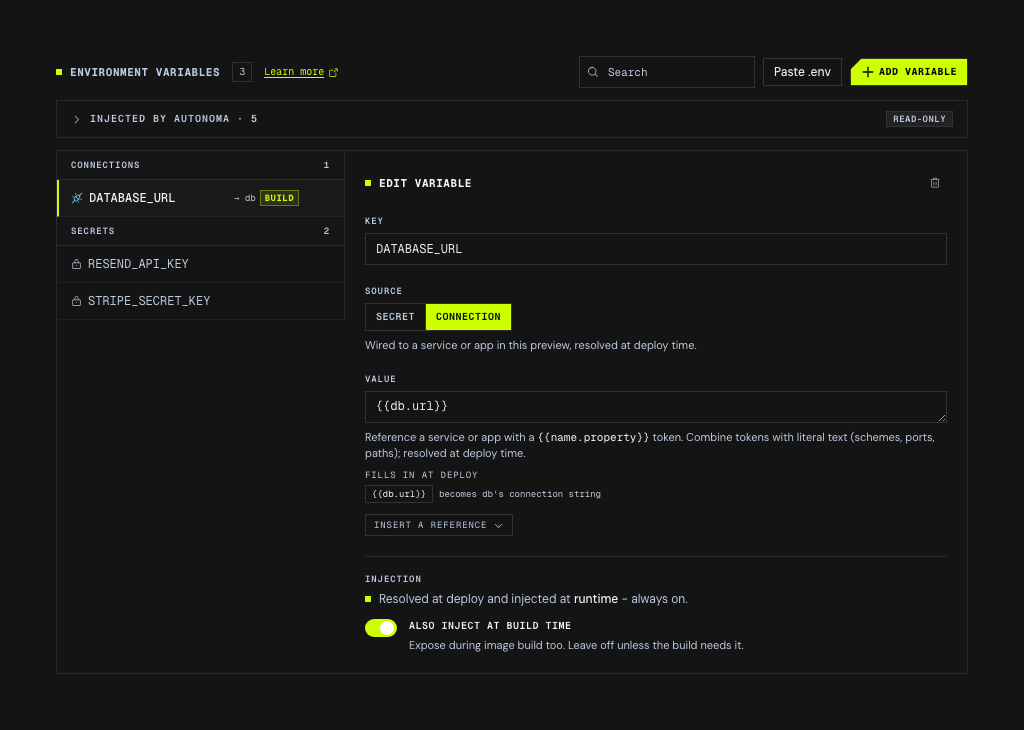
In the dashboard this is the **Connection** source, and the editor resolves each token as you type - so you can see what `{{db.url}}` will become before you deploy, and a name that isn’t declared is flagged there rather than at save time.
```yaml
# stack configuration
apps:
- name: web
port: 3000
connections:
- key: DATABASE_URL
value: "{{db.url}}"
services:
- name: db
recipe: postgres
version: "16"
```
For a `postgres` service named `db`, the value resolves to `postgresql://preview:preview@:/preview`. Need a different database name, user, or query params? Build the URL by hand from the smaller tokens:
```yaml
connections:
- key: MONGO_URI
value: "mongodb://{{db.host}}:{{db.port}}/preview?replicaSet=rs0"
```
## Template reference
A connection value mixes literal text with `{{name.property}}` tokens, where `name` is any app or service declared in the same configuration. A value with no token at all is fine too - use it to pin non-sensitive per-environment config like `NODE_ENV=production`.
| Token | Resolves to |
| --------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `{{service.url}}` | The service’s full in-cluster connection string: `postgres` -> `postgresql://preview:preview@:/preview`, `mysql` -> `mysql://:@:3306/`, `redis` / `valkey` -> `redis://:`, `mongodb` -> `mongodb://:/?directConnection=true` |
| `{{service.host}}` / `{{service.port}}` | The service’s in-cluster DNS name and port |
| `{{app.url}}` | The app’s public HTTPS preview URL |
| `{{app.hostname}}` | The app’s public hostname, without the scheme |
| `{{app.host}}` / `{{app.port}}` | The app’s in-cluster DNS name and port (app-to-app traffic that shouldn’t leave the namespace) |
| `{{pr}}` | The pull request number |
| `{{namespace}}` | The preview’s Kubernetes namespace |
| `{{owner}}` | The repository owner |
Services whose recipe has no single canonical scheme (e.g. `temporal`) expose only `host` / `port`.
Referencing a name that isn’t declared in the configuration is a validation error at save time, so typos never make it to a deploy.
## Connections vs. secrets
Connections and [secrets](/preview-environments/secrets/) answer different questions:
| | Connection | Secret |
| ---------------- | -------------------------------------------------- | ------------------------------------- |
| What it holds | A templated or literal, non-sensitive value | A sensitive value (API key, token) |
| Where it lives | In the stack configuration, in your repo’s history | Encrypted storage - never in the repo |
| When it resolves | At deploy time, per preview | Uploaded once, mounted as-is |
A connection **wins over** a stored secret with the same key. That makes it the override channel for preview wiring: your team can keep a production-shaped `DATABASE_URL` secret uploaded, and the preview’s `{{db.url}}` connection overrides it inside the preview only.
## Build-time connections
Some values must exist while the image builds, not just at runtime - a Vite or Next.js frontend bakes its API URL into the client bundle. Set `build_time: true` and the resolved value is also passed as a Docker build arg:
```yaml
connections:
- key: VITE_API_URL
value: "{{api.url}}"
build_time: true
```
This is the connection counterpart of a [build-time secret](/preview-environments/secrets/#build-time-secrets): use `build_time` on a connection for topology values, and the secret’s own build-time flag for sensitive ones.
# Lifecycle hooks
> Commands that run around each deploy of the whole preview - pre-deploy before your apps start, post-deploy once they're ready.
Lifecycle hooks are commands Autonoma runs around each deploy of the whole preview: before your apps start, and after they're ready. Most projects never need them.
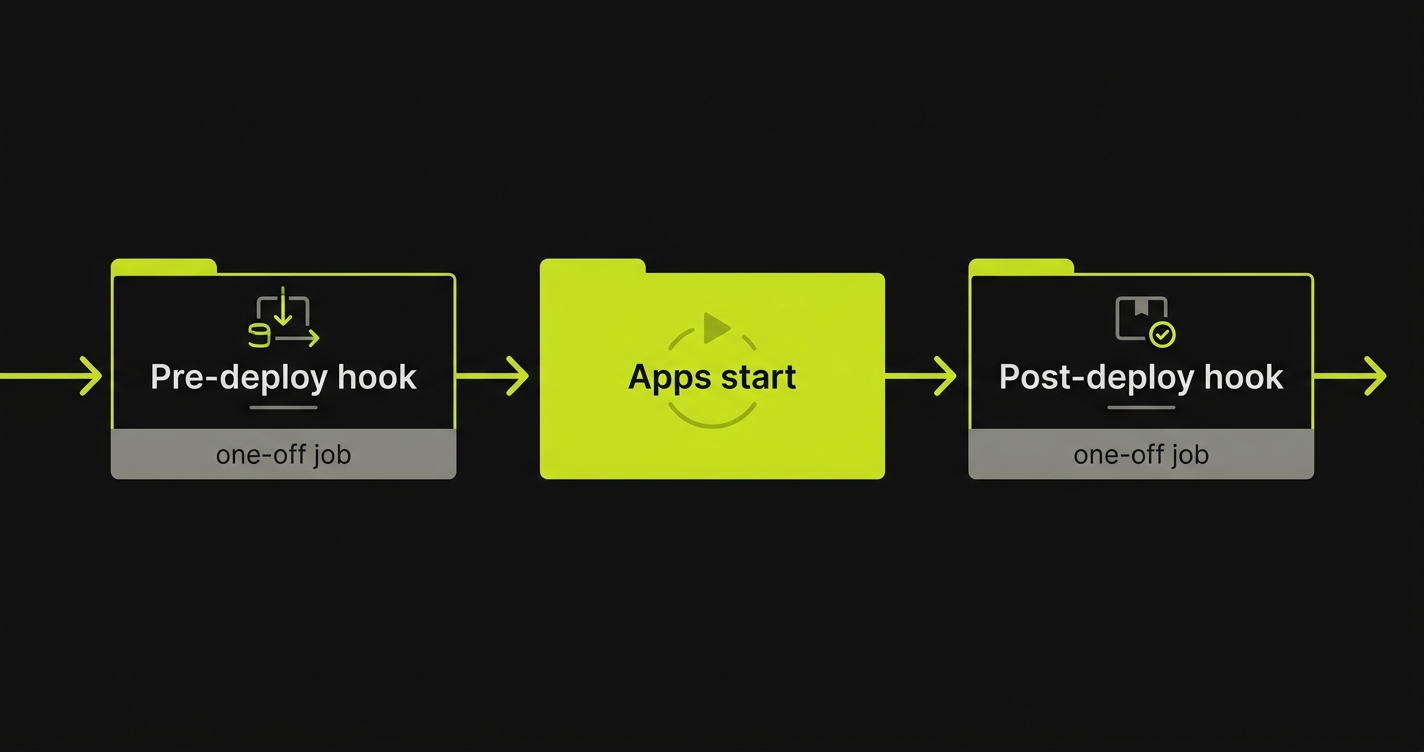
Think of a hook as a step that belongs to the preview itself, not to any single app or database. When a preview deploys, Autonoma runs your pre-deploy hooks, brings the apps up, then runs your post-deploy hooks. Both groups are optional, and you add as many commands to each as you like.
## Pre-deploy and post-deploy
Hooks live in two groups, chosen by when you need them to run:
| Group | When it runs | Good for |
| --------------- | -------------------------- | -------------------------------- |
| **Pre-deploy** | Before your apps start. | Cache warmup, feature-flag sync. |
| **Post-deploy** | After your apps are ready. | A smoke test, notifying Slack. |
**Every hook belongs to an app**, which is what decides the image its command runs in. A hook is a one-off Kubernetes Job launched from that app’s built image, so the command has that app’s code, dependencies and secrets available - and nothing else. Picking the app is required; the config will not save without it.
A pre-deploy hook runs before the apps start. A post-deploy hook runs once **its own** app is ready - not once every app is. Two things follow that are easy to get wrong:
* A post-deploy hook whose app never came up is **skipped silently** (the deploy itself then fails, since a preview only publishes when every app is ready).
* A failing post-deploy hook does **not** fail the deploy. It is reported as a warning on the PR comment and the preview is still published, so a smoke test here will not gate anything.
> **The built-in variables are not available in a hook:**
>
> `AUTONOMA_PREVIEWKIT`, `AUTONOMA_PREVIEWKIT_PR` and `AUTONOMA_PREVIEWKIT_URL` are injected into your running app containers only. A hook Job gets its app’s secrets and resolved connections, and none of those three - so a command like `curl "$AUTONOMA_PREVIEWKIT_URL/health"` sees an empty string.
## Migrations: prefer the database’s own setup
You *can* run a migration from a pre-deploy hook - it is a documented use, and the hook’s own help text in the dashboard suggests it. Prefer putting it on the database instead.
A database’s setup tasks are owned by that database, so Autonoma runs them at the right moment for it, and each database carries its own schema and seed data rather than one preview-wide step doing everything. Reach for a pre-deploy hook when the work genuinely spans the preview, or when it does not belong to any single database. See [databases](/preview-environments/databases/) for where setup commands go.
## Optional by design
Hooks sit off the main onboarding flow - you reach them through the optional tab, or the “finish here” fork on the Variables step. Skip them entirely if your preview doesn’t need work around its deploys, and come back to add one whenever you do.
# Multiple repositories
> Deploy your frontend and the apps it depends on from more than one repository into a single preview, and control which branch of each connected repository gets built.
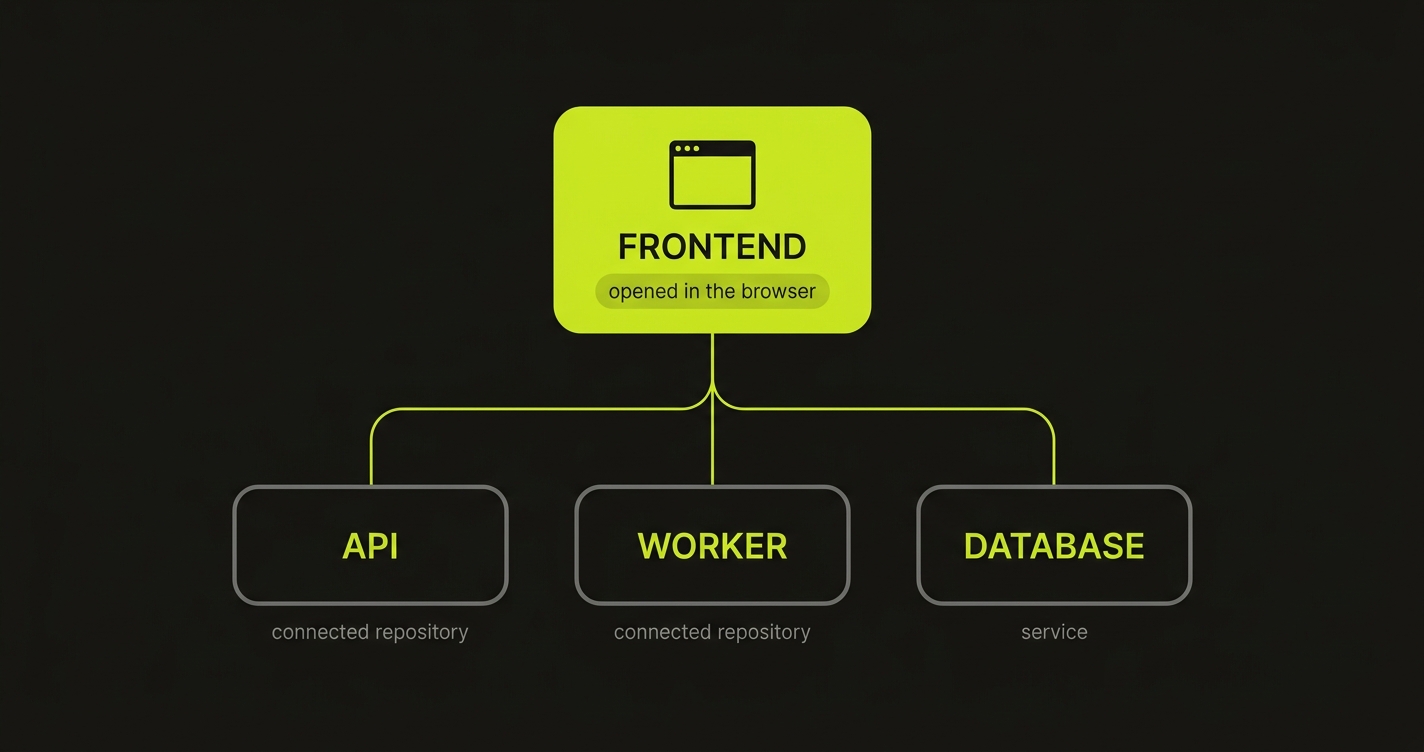
Autonoma tests a pull request by opening one app in a browser - the frontend. The apps and services behind it can live in a single repository or several; when they span repositories, Autonoma pulls them all into the same preview.
## The frontend
Every project has exactly one **frontend**: the app Autonoma opens in the browser to run its tests, and whose address becomes the preview’s URL. It lives in the repository you open pull requests against.
The frontend rarely stands alone - it calls an API, background workers, a database. Those can sit in the same repository, or in their own. Either way they deploy together, into the single preview environment for that pull request, and Autonoma wires them to each other. Think of the frontend as the root of a tree: everything else is there to support the one thing the browser opens.
## Connected repositories
When an app your frontend needs lives in a different repository, you add that repository as a **connected repository**. You do it while adding an app: pick which repository the app comes from, or connect a new one through the Autonoma GitHub App. Every app records the repository it builds from, so the set of repositories in a preview is simply the set its apps name.
Each connected repository carries one setting:
* **Fallback branch** - the branch to deploy when branch matching finds no match (see below). Defaults to `main`.
Every app from the same connected repository shares it.
## Which branch gets deployed
For the repository you open pull requests against, the answer is obvious: the pull request’s own branch. For a connected repository it isn’t - the pull request’s branch usually doesn’t exist there. **Branch matching** is the single rule that decides which branch of every connected repository Autonoma builds for a given pull request.
If the branch it picks doesn’t exist in the connected repository, Autonoma always falls back to that repository’s **fallback branch**, so a preview never fails just because a connected repository has no matching branch. If the fallback branch doesn’t exist either, the deploy fails: previews are all-or-nothing, and an app whose source can’t be resolved can never come up.
| Branch matching | For a PR on branch `feature/x`, a connected repository builds… |
| ---------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Same branch name** | `feature/x` if that branch exists there, otherwise the fallback branch. Use this when you develop a feature across repositories on branches with the same name. |
| **Fallback branch only** (default) | Always the fallback branch (e.g. `main`). Use this when the connected repository is a stable service you don’t branch per feature. |
| **Regex rewrite** | A branch name derived by rewriting `feature/x` with a regular expression (e.g. stripping a `feature/` prefix), falling back if the result doesn’t exist. Use this when your repositories follow different but predictable branch conventions. |
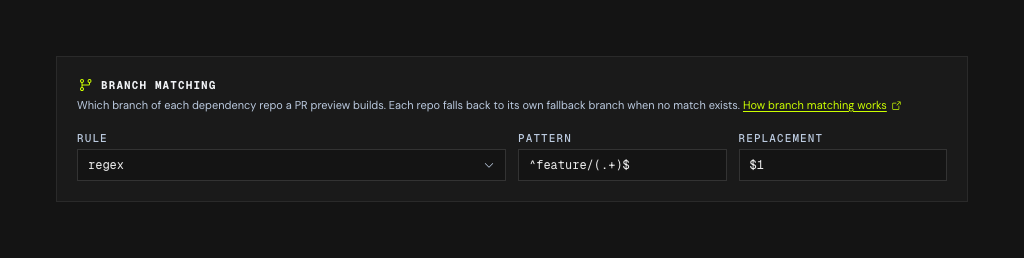
Picking **Regex rewrite** reveals the Pattern and Replacement fields; the other two rules need no extra input. The control only appears once at least one repository is connected.
Branch matching is set once and applies to every connected repository in the project; the fallback branch is per repository.
> **Note:**
>
> Branch matching only affects **connected** repositories. The repository you open pull requests against always builds the pull request’s own branch.
# Your team and organizations
> How people get into an Autonoma organization - automatic joining by email domain, or an invitation - plus how an account can belong to several organizations, how switching between them works, and when leaving one is refused.
An Autonoma account can belong to several organizations. Which one you are working in is a property of your browser session, not of your account.
## Two ways into an organization
**By email domain.** If you signed up with a company address - `you@acme.com` - your organization is keyed to `acme.com`. Anyone who signs in with an `@acme.com` address joins it automatically, with no invitation and nothing for you to configure. Colleagues just sign in.
**By invitation.** If you signed up with a personal address, or through the Vercel Marketplace, there is no shared domain to match on, so nobody can reach your organization on their own. That is what invitations are for.
**Settings → Members is available either way.** On a domain-matched organization, inviting somebody who would join automatically is refused with an explanation - but you can still invite a contractor or consultant whose address is on a different domain, and it is where you leave an organization you no longer want to be in.
## Sending an invitation
1. Open **Settings**, then **Members** under *Organization settings*.
2. Choose **Invite member** and enter their email address.
3. They get an email with a link to review the invitation. It expires after 7 days.
Inviting the same address twice does not create a second invitation - it refreshes the existing one and re-sends it, so any link you have already shared keeps working.
Every member can see and change every application in the organization, and any member can invite others. There are no per-application permissions or roles yet.
### If the email does not arrive
Each pending invitation has a **Copy link** button. The link is the whole invitation, so you can send it over Slack or anywhere else if mail is delayed or filtered. Revoking an invitation invalidates the link immediately.
## Accepting an invitation
The link asks the invitee to sign in, then to confirm.
**Joining is additive.** If they already use Autonoma they keep every organization they were already in - the new one is added alongside. Nothing they had access to before is affected.
An invitation can only be accepted by the address it was sent to. If they are signed in as somebody else, the page says which address to use rather than silently doing nothing.
## Belonging to more than one
Two places let you move between organizations:
* **The organization name in the account menu** becomes a menu once you belong to more than one. Open it from the button at the right-hand end of the top bar.
* **After signing in**, you are asked which organization to start in. With only one you go straight through and never see the question.
Switching applies to **that browser** - two browsers can sit in two different organizations at the same time. Your most recent choice is remembered, so signing in again starts you back where you left off rather than in whichever organization you joined first.
## Naming your organization
If you signed up with a personal address, your organization is initially named after you - because you were the first person through the door, not necessarily because it is yours. The first time you sign in you are asked to name it, with your own name prefilled so keeping it is one click.
You can change it later under **Settings → Members → Your organizations → Rename**. Organizations created from a company email domain are already named after the domain and are never asked.
## Leaving an organization
Under **Settings → Members**, the *Your organizations* panel lists everything your account belongs to, and each row has a **Leave**.
Leaving drops only your own membership. The other members keep theirs, and any of them can invite you back.
Two cases are refused, and the reason is shown on the disabled button:
| Refused when | Why |
| -------------------------------- | -------------------------------------------------------------------------------------------------------------------------------- |
| It is your **only** organization | An account with no organization cannot reach anything. Join another first. |
| You are its **last member** | Nobody would be left who could reach its applications, and no one could ever be granted access again. Invite someone else first. |
To hand an organization over, invite the new owner, wait for them to accept, then leave.
## Removing someone else
On the *Members* panel, choose the remove icon on their row. They lose access to every application in this organization but keep their Autonoma account and any other organizations they belong to, and can be invited back.
You cannot remove yourself - use **Leave** instead, which enforces the two guards above.
### Their API keys
An API key authenticates against the organization, not against the person who created it, so removing someone does **not** stop their keys working. That is deliberate: a key created by a teammate is often the credential in your CI, and revoking it the moment they leave would break a pipeline that has nothing to do with them.
The remove dialog therefore lists every API key that member created here, with when each was last used, and lets you choose which to delete. Nothing is selected by default; **Select all** takes the lot. A key last used minutes ago is almost certainly wired into something that is still running, so mint a replacement and swap it in before deleting.
Whatever you keep stays visible on *Settings -> API keys*, badged **Owner left**, and anyone in the organization can delete it there later. Treat that badge as a rotation reminder: the person who holds that key’s secret is no longer in your organization.
# Connect your coding agent (MCP)
> Install Autonoma's MCP server in your coding agent once, and use it for both jobs - setting an app up on Autonoma, and fixing what Autonoma flags on a pull request from inside your repo.
Autonoma runs one MCP server. Install it in your coding agent once and it covers both jobs: setting an app up on Autonoma, and fixing what Autonoma flags on a pull request - the analysis and its evidence, deploy status, build and runtime logs, a diagnosis, missing secrets, and your scenario test data.
Everything on this page is that one installation. What your agent does with it is decided by what you ask for, not by what you connected to:
* **Use it for onboarding** - set an app up: pick how it gets its previews, configure and deploy them (or wire your own pipeline), validate your SDK endpoint, and get your scenario recipes provisioning. **You do not install anything for this one.** Autonoma hands you a single command that registers this server for you and starts an agent on the job. → [Set up a preview with a coding agent](/mcp/configure-preview)
* **Use it for debugging** - once Autonoma is reviewing your pull requests: read what it flagged and why, pull logs and deploy status, fix the cause in your repo, and ask for a re-check. Your agent identifies the app from your git remote. → the rest of this page, which is where you install it by hand.
You do not install anything twice, and you do not pick a mode. The same tools are there for both.
> **Note:**
>
> Setting an app up? You can stop reading here. The [planner CLI](/test-planner/) does the installation below for you, in one command, and then keeps going through your test suite and test data. This page is for the debugging job, and for anyone who would rather wire the server up themselves.
## Connection details
Everything below is the same server, just configured per client. When a client asks for these values, use:
| Setting | Value |
| ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **URL** | `https://api.autonoma.app/v1/mcp` |
| **Transport** | Streamable HTTP |
| **Authentication** | OAuth - your client opens a browser to sign in to Autonoma and authorize; no API key or token to paste. Headless agents can send an [API key](#headless-agents-and-ci) instead. |
> **Note:**
>
> You need an Autonoma account with your app connected. For the debugging job you also need a pull request that has a preview environment. The MCP is scoped to your organization - it only ever sees your own deploys, logs, and secret status.
> **Note:**
>
> **Already using `/v1/mcp/debug` or `/v1/mcp/onboarding`?** Both still work and are not going away - they are addresses for this same server, carrying the same tools. There is nothing to change. `/v1/mcp` is the one to use for a new setup, and if you have both of the old addresses registered you can drop one: they are the same server twice.
## Headless agents and CI
The OAuth flow needs a browser. Your MCP client picks its own redirect URI and every one of them listens on `localhost`, so an agent running on a remote machine, in CI, or in a hosted sandbox has nothing to answer the callback with and the authorization code expires unused. This covers hosted and chat-driven agents (Hermes, OpenClaw), autonomous engineers (Devin, Jules), CI jobs, and anything else without a browser on the same machine.
**If you are one of those agents and you are setting an app up:** none of this applies to you - run the [planner CLI](/test-planner/#running-unattended) with `--non-interactive` instead. It authorizes itself with an API key, never opens a browser, and does the whole setup in one invocation.
**If you are one of those agents and you are debugging a pull request:** use the **Remote agent** tab on Autonoma’s connect dialog. It is the configuration built for you - one block carrying the endpoint, an API key, and the instruction to start on. And whatever tab a user copied from, the block already ends with the same fallback in a comment, so a browser sign-in you cannot complete is never a dead end: take the `Authorization: Bearer` header from the comment and carry on.
> **If you found this page through `llms.txt` or the `.well-known/ai-catalog.json` file**, you are already in the right place. Use the [connection details](#connection-details) with an API key bearer token - no browser needed.
For those, send an Autonoma API key as a plain bearer token and skip OAuth entirely:
```bash
curl https://api.autonoma.app/v1/mcp \
-H "Authorization: Bearer $AUTONOMA_API_KEY" \
-H "Content-Type: application/json" \
-H "Accept: application/json, text/event-stream" \
-d '{"jsonrpc":"2.0","id":1,"method":"tools/list"}'
```
Most clients let you set a static header. With `mcp-remote`:
```bash
npx -y mcp-remote https://api.autonoma.app/v1/mcp \
--header "Authorization: Bearer ${AUTONOMA_API_KEY}"
```
You do not have to create one by hand. Every “connect a coding agent” panel in Autonoma has a **Remote agent** tab, and copying its block creates a key and puts it in what you copied. The key is never displayed, so nothing leaks to a screenshot or a screen share; revoke it under **Settings → API keys** when the agent is done with it.
The other tabs carry the same key too, as a trailing comment you do not see on screen. That is deliberate: the tab you pick says which client you run, not which machine it runs on, so a Codex command copied to a machine you SSH into still authenticates rather than stalling on a sign-in nobody can complete.
The same key works for the onboarding tools on this server, the REST API, and the planner CLI.
> **Note:**
>
> An API key belongs to one organization, and over MCP it can only reach that organization - even if you belong to several. An OAuth token is scoped to you rather than to one org, so it resolves the organization per call from the repository a tool names. If a key seems unable to see a repo, check it was created in the organization that owns it.
## Connect your coding agent
Add the server and sign in, from a terminal - not from inside a running Claude Code session:
```bash
claude mcp add --transport http --scope user autonoma https://api.autonoma.app/v1/mcp
claude mcp login autonoma
```
`--scope user` registers the server for every project; the default (`--scope local`) binds it to the directory you ran the command in, which is the usual reason the Autonoma tools turn out to be missing in the repo you actually work in.
`claude mcp login` opens a browser to sign in. Approve it there - until you do, every Autonoma tool fails. Run `claude mcp list` to confirm it connected.
With no browser on the machine, drop the `login` line entirely and register an [API key](#headless-agents-and-ci) as a header - there is no sign-in left to complete:
```bash
claude mcp add --transport http --scope user autonoma https://api.autonoma.app/v1/mcp \
--header "Authorization: Bearer $AUTONOMA_API_KEY"
```
> **Caution:**
>
> **If you are a Claude Code session reading this:** do not run these commands. `claude mcp add` writes a config file you never reload, so you would report success and then find no Autonoma tools. Ask the user to run them in their own terminal, and tell them they will need to restart you afterwards.
>
> This is a limitation of installing into a running session, not of agents. If you add MCP servers through your own configuration, connect with the [connection details](#connection-details) and an [API key](#headless-agents-and-ci) - no terminal or browser needed.
Add the server to `~/.cursor/mcp.json` (global) or `.cursor/mcp.json` in your project:
.cursor/mcp.json
```json
{
"mcpServers": {
"autonoma": {
"url": "https://api.autonoma.app/v1/mcp"
}
}
}
```
Reload Cursor, then complete the browser sign-in when prompted from **Settings → MCP**. To skip that sign-in, add an [API key](#headless-agents-and-ci) as a header on the server:
```json
{
"mcpServers": {
"autonoma": {
"url": "https://api.autonoma.app/v1/mcp",
"headers": { "Authorization": "Bearer YOUR_API_KEY" }
}
}
}
```
For GitHub Copilot’s agent mode, add the server to `.vscode/mcp.json`:
.vscode/mcp.json
```json
{
"servers": {
"autonoma": {
"type": "http",
"url": "https://api.autonoma.app/v1/mcp"
}
}
}
```
Start the server from the `mcp.json` editor lens, then authorize in the browser when prompted.
Add the server to `~/.codeium/windsurf/mcp_config.json`:
\~/.codeium/windsurf/mcp\_config.json
```json
{
"mcpServers": {
"autonoma": {
"serverUrl": "https://api.autonoma.app/v1/mcp"
}
}
}
```
Refresh MCP servers from Cascade’s settings, then complete the browser sign-in. To skip that sign-in, add an [API key](#headless-agents-and-ci) as a header alongside `serverUrl`:
```json
{
"mcpServers": {
"autonoma": {
"serverUrl": "https://api.autonoma.app/v1/mcp",
"headers": { "Authorization": "Bearer YOUR_API_KEY" }
}
}
}
```
Codex speaks Streamable HTTP natively. Add the server and sign in, from a terminal:
```bash
codex mcp add autonoma --url https://api.autonoma.app/v1/mcp
codex mcp login autonoma
```
With no browser to complete that sign-in, drop the `login` line and authenticate with an [API key](#headless-agents-and-ci) from an environment variable instead:
```bash
codex mcp add autonoma --url https://api.autonoma.app/v1/mcp \
--bearer-token-env-var AUTONOMA_API_KEY
```
`--bearer-token-env-var` names the variable rather than taking the value, so the key stays out of `~/.codex/config.toml` and out of your shell history.
> **Note:**
>
> Older instructions bridged Codex to remote servers with `mcp-remote` and a hand-edited `[mcp_servers.autonoma]` block in `~/.codex/config.toml`. `codex mcp add --url` supersedes that - use it instead.
Any MCP client that speaks Streamable HTTP can connect with the [connection details](#connection-details) above. For a client that only supports STDIO servers, bridge to the remote server with [`mcp-remote`](https://github.com/geelen/mcp-remote):
```json
{
"mcpServers": {
"autonoma": {
"command": "npx",
"args": ["-y", "mcp-remote", "https://api.autonoma.app/v1/mcp"]
}
}
}
```
`mcp-remote` opens the browser for the OAuth sign-in and proxies the connection over STDIO.
> **Caution:**
>
> Client config formats change over time. If a snippet above no longer matches, keep the [connection details](#connection-details) and follow your client’s current “add an MCP server” instructions.
That is the whole installation, and it covers both jobs. **Setting an app up?** [Set up a preview with a coding agent](/mcp/configure-preview) picks up from here: how your agent chooses the preview path and what it does on each - though the one command Autonoma gives you does this installation for you, so most people never need this page for that job. The rest of this page is the debugging job.
## Point your agent at it
The server gives your agent the tools; a short line in your agent’s instructions tells it *when* to reach for them. The fastest way is to invoke the **`setup_autonoma`** prompt - your agent adds the section to `AGENTS.md` (or `CLAUDE.md`) for you. Or add it by hand:
```markdown
After you push a PR, Autonoma reviews its preview deploy. If it flagged a
problem, use the Autonoma MCP tools to find the cause (get_analysis for the
issues and evidence; get_deploy_status, diagnose_deploy, get_build_logs,
get_app_logs, get_secret_status when the preview itself fails), fix it
(set_secret for a missing value, edit_previewkit_config for build/wiring,
or dry_run_scenario when a test failed on its seed data), and confirm with
wait_for_deploy - before merging.
```
Because that file is read every session, your agent pauses to check the preview without you having to ask.
The server also ships two things any client can use without a setup file: a **`debug_broken_preview`** prompt (a guided fix flow for a given PR) and a readable **debugging guide** resource. And its connect-time instructions already tell your agent what Autonoma is and the recommended order to use the tools - so even an agent that has never heard of Autonoma knows where to start.
## What your agent can do
Every tool names your app either by repo (`owner/repo`) or by application id - one of the two, never both; the per-PR tools also take the PR number, where `0` means the base environment (the preview built from your deploy branch). Your organization is inferred from the app (whose organization you must belong to), so every call is automatically scoped to it. You don’t need to hand your agent either name: in a checkout it infers the repo from the git remote, an agent that set the app up already holds the application id from `pair`, and `list_apps` lets you pick. You do not need GitHub access; the repo name is just how Autonoma identifies your app.
### Read the evidence
| Tool | Input | Returns |
| ---------------------- | ---------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `list_apps` | none | The repos you can debug across your organizations - use when the repo isn’t obvious |
| `get_analysis` | repo/appId, PR | **Start here when Autonoma flagged something.** The run’s report (a summary, the write-up, and which tests it selected and why) plus every open issue - what should have happened, what did, a suspected cause with `file:line` code evidence, signed screenshot/clip URLs, and the tests it covers. Read live, so it can be more current than the PR comment |
| `get_deploy_status` | repo/appId, PR | Per-service deploy status, endpoints, and the latest build outcome |
| `diagnose_deploy` | repo/appId, PR | The raw evidence in one call - status, service states, latest build outcome, a rule-based failure classification, the config’s env-key surface, and error-shaped logs - plus deterministic findings categorized as a missing env var, setup problem, or platform error. It is not an AI summary; you reason over the signals |
| `get_build_logs` | repo/appId, PR | Build-log lines, from the `tail` (newest) or `head` (start of the build), optionally for one service |
| `get_app_logs` | repo/appId, PR | Runtime (stdout/stderr) log lines, from the `tail` (a crash) or `head` (startup) |
| `get_endpoints` | repo/appId, PR | The preview URL, a suggested SDK URL, and one entry per service (internal services like a database report `url: null` with a reason) |
| `get_secret_status` | repo/appId | The env-var surface per app: topology connections (with template values) and the secrets that ARE set, each flagged build-time or runtime, with masked length and a fingerprint only, never a value. It cannot report a variable as missing - an unset key has no row |
| `get_config` | repo/appId | The app’s full active preview config document (apps, services - no secret values), for read-edit-write of the whole shape via `apply_config`. Apps onboarded before the framework build presets were retired also get an `applyReady` document: the same config with those builds rewritten as the supported equivalent, so what you read can be sent back |
| `list_scenarios` | repo/appId | The app’s scenarios - the named test-data states its tests depend on - and whether each has a recipe |
| `get_recipe` | repo/appId, scenarioId | A scenario’s active recipe: the `create` graph your SDK builds those entities from |
| `get_app_instructions` | repo/appId | The two standing instruction fields from the app’s settings page - `customInstructions` (how to drive the app during a run) and `testScopeGuidelines` (what to test and how to judge it) - plus the `fingerprint` a write must quote back |
Every issue `get_analysis` returns carries a `kind`, and the kind decides where its fix lives - which is what keeps your agent from trying to patch code for a problem that was never in your code:
* **`bug`** - the app misbehaved. Fix it in your repo and push; Autonoma re-runs on the new commit.
* **`environment`** - the preview could not run properly (a missing secret, a service that never came up). Fix it with the deploy tools below. No repo change.
* **`scenario`** - the data a test needed was missing or wrong. Fix it with the recipe tools below, which take effect with no redeploy.
### Fix and confirm
| Tool | Input | Returns |
| ------------------------- | ----------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `set_secret` | repo/appId, PR, app, key, value?, buildTime? | Sets (or, without a value, removes) a secret env var’s value for the app and applies it - rebuilds if it is marked build-time, restarts otherwise. `buildTime` omitted leaves an existing key’s setting alone, and a new key build-time; pass `false` for a value the image must not carry. Stored per app, not per PR. Values are stored encrypted and never returned |
| `edit_previewkit_config` | repo/appId, PR, app, fields | Changes structural config for one service (path, Dockerfile, port, connections) and rebuilds it. Only the fields you pass change; never sets a secret value. Saved to the app’s one config, so it applies to every environment |
| `apply_config` | repo/appId, PR, document, apply? | Saves a FULL config document (call `get_config` first, edit it, send the whole thing back) and, unless `apply:false`, redeploys the environment. The path for reshaping the preview: adding or removing an app or a service (a database, cache, side-container) - things a single-service edit can’t express. The document is the app’s, shared by every environment; `PR` picks which one redeploys |
| `rename_app` | repo/appId, PR, from, to | Renames an app in the config, keeping its stored secrets and build history. Use this rather than renaming in `apply_config`: a document says only what the topology should look like afterwards, so a renamed app reads as a new one and the old app is deleted - along with the secrets Autonoma provisioned for it, which is how a renamed preview comes back unable to answer a scenario call. Re-read `get_config` afterwards; the document you were holding still names the old app |
| `wait_for_deploy` | repo/appId, PR, app? | Blocks (up to \~45s, then re-callable) until the deploy settles (ready or failed) and returns the outcome plus the last few log lines, so you can see progress and keep debugging after a `set_secret`, `edit_previewkit_config`, or `apply_config` rebuild. `outcome` is `deployed`, `in_progress` (call again), or `idle` - nothing was deploying, so stop |
| `dry_run_scenario` | repo/appId, scenarioId, recipe?, save?, target? | Runs a recipe against your deployed SDK (`up` then `down`). Pass a `recipe` to try an edit **without storing it**; pass `save: true` to promote it, which happens only if the run passes; pass a `target` to run against a specific preview instead of the app’s stored endpoint |
| `list_dry_run_targets` | repo/appId | The previews a dry run can be pointed at - the app’s open PR previews and its main deployment, with whether each is deployed yet. Use a returned `id` as `dry_run_scenario`’s `target` |
| `update_recipe` | repo/appId, scenarioId, recipe, baseFingerprint? | Saves a recipe as the active one. Validated on save and rejected with the exact problems. Pass the `fingerprint` from `get_recipe` so a write that races another editor is rejected with their version rather than overwriting it. Affects every future run of that scenario |
| `update_app_instructions` | repo/appId, customInstructions?, testScopeGuidelines?, baseFingerprint? | Edits the standing instructions on the app’s settings page, so something your agent worked out survives the session. A false positive worth suppressing goes in `testScopeGuidelines`; an app quirk the agent needs to get through a flow goes in `customInstructions`. Each field is a full replacement of a human’s text: call `get_app_instructions` first, merge your point into what is there, and pass its `fingerprint` so a write that races the user is rejected with their version instead of overwriting it. Affects every future run |
| `start_analysis` | repo/appId, PR | Asks Autonoma to analyze the PR’s current commit - the same run a reviewer starts by commenting `/start analysis`. Call it once you have finished fixing and want Autonoma to re-check the PR against its preview; you do not need to switch to GitHub. Autonoma flips the check to in-progress, runs its affected tests, and posts the verdict on the PR - read it with `get_analysis`. No-ops if the merge gate or activation is off for the org (a run there starts on its own), and if the commit was already analyzed or has no live preview it comments on the PR why no run started |
| `send_analysis_message` | repo/appId, PR, message | Hands Autonoma a natural-language instruction for its next analysis run of the PR - the same inbox a reviewer’s comment feeds. Use it to STEER the re-analysis: focus it on a flow you just fixed, a risk you are worried about, or a file you changed. If a run is in flight it picks the message up before it finishes; if the branch is idle, delivering it starts a run, and the run addresses your message in its report. Today it can only direct RE-ANALYSIS - an ask to write or change a test is answered as out of scope, not acted on. Refused (nothing enqueued) for a closed/merged PR or an app that has not finished onboarding |
The write tools split cleanly by what they change, so your agent never has to guess which to use:
* A **secret value** (an API key, token, or password) - `set_secret`. It stores the value and applies the minimal action itself: a rebuild if the key is marked build-time (baked into the image at build), a restart otherwise. A new key is build-time by default; pass `buildTime: false` for a value the image must not carry. Omitting it on an existing key leaves its setting alone.
* **How one service is built or wired** (build path, Dockerfile, port, topology connections) - `edit_previewkit_config`. It saves the change and rebuilds that one service.
* **The shape of the preview** (add or remove an app or a service like a database or cache) - `get_config` then `apply_config`. It saves the full document and redeploys the environment, since a topology change touches more than one service.
* **An app’s name** - `rename_app`, never `apply_config`. This is the one edit a document cannot express: it shows only the after-state, so an app under a new name is indistinguishable from a new app and the old one is deleted, taking its secrets and build history with it. `rename_app` renames the record, so nothing attached to it is lost.
Those four change how the preview runs. The fifth changes what Autonoma *knows*: when the answer to a flagged issue is “that is intended behavior” or “the agent got stuck because this screen does something unusual”, `update_app_instructions` writes it onto the app’s settings page, where every future run reads it. Without it that conclusion lives only in your agent’s session, and Autonoma reaches the same wrong one next week. It edits text a human also edits, so it is a read-merge-write: `get_app_instructions`, add your point to what is already there, and send it back with the `fingerprint` you read.
> **Config and secrets are per app, not per pull request:**
>
> Your app has **one** preview config and one set of secret values, and every environment deploys from them - the base environment and each open pull request alike. So a config edit or a `set_secret` made while debugging one PR also changes main and every other open PR. The `prNumber` these tools take chooses only which environment is rebuilt with the saved change; it does not scope the change, and nothing else does either. Per-environment configuration is a known limitation we may lift later. If you need a setting that applies to one pull request only, that is not something Autonoma can do today.
### Fixing test data
A test can fail because the app is broken - or because the data it needed was never there. Autonoma seeds that data before each run by asking your deployed SDK to build a named **scenario** (“logged-in admin with one open invoice”); the JSON describing those entities is the scenario’s **recipe**, and it lives on Autonoma rather than in your repo, so changing one takes effect with no redeploy.
That makes recipes the fastest thing to fix, and the tools are built for iterating rather than committing:
```plaintext
get_recipe(scenarioId) read what is stored
dry_run_scenario(scenarioId, recipe) try an edit - provisioned, then torn down, never stored
...read the SDK's error, edit, repeat...
dry_run_scenario(scenarioId, recipe, save) promote the one that passed
```
Passing a `recipe` runs *that* candidate instead of the stored one and persists nothing, so the recipe your test runs use keeps working while your agent experiments, and a wrong guess costs nothing. `save: true` promotes a candidate only after a clean `up`/`down`, so a recipe nobody has seen work cannot become the active one.
> **A saved recipe is shared state:**
>
> `update_recipe` - and `dry_run_scenario` with `save: true` - changes the recipe **every future run of that scenario** uses, not just yours. On a live app, treat it like a database migration: prove the candidate with an unstored dry run first, then promote it.
Two different things can be wrong, and they iterate at very different speeds. The **recipe** (wrong fields, a missing entity, a `_ref` pointing at nothing) is fixed here, in seconds. Your **SDK handler code** (a missing factory for a model, a broken insert) lives in your repo and only changes when the app is rebuilt and redeployed.
By default a dry run hits the SDK endpoint the app currently has configured, which is not necessarily the preview for the PR you are working on. When your handler change is already deployed to its own PR preview, `list_dry_run_targets` plus `dry_run_scenario`’s `target` runs against that preview directly - so you can test a handler change without waiting for it to become the app’s configured endpoint.
They all apply asynchronously, so the loop is: **fix** with `set_secret` / `edit_previewkit_config` / `apply_config`, **confirm** with `wait_for_deploy` (which streams a short log tail and returns `outcome: "in_progress"` while the rebuild is still running, so you call it again - or `outcome: "idle"` when nothing was deploying at all, so you stop), then re-read if it failed. Once the preview is healthy and your fix is on the PR, `start_analysis` asks Autonoma to re-run its tests against the new commit and post a fresh verdict - read it with `get_analysis`.
> **Secrets are never exposed:**
>
> The MCP never returns a secret’s value - not through `get_secret_status`, not through `set_secret`, not anywhere. To let your agent check whether a set value matches one it already holds, both return a non-reversible **fingerprint** (the first 12 hex chars of SHA-256 of the value) instead: your agent computes `sha256(value).hex.slice(0, 12)` on its candidate and compares. The value never leaves Autonoma; only whether it matches can be inferred.
## Troubleshooting
**The tools do not show up.** Confirm the client connected (e.g. `claude mcp list`) and that you completed the browser sign-in. A client that only supports STDIO needs the `mcp-remote` bridge shown under **Other clients**.
**A tool says no live preview environment was found.** Autonoma tears the preview down after testing, so the live-surface tools (`get_deploy_status`, `get_endpoints`, `wait_for_deploy`) return `unavailable` once it is gone. This does **not** mean there is nothing to inspect: `get_build_logs` and `get_app_logs` still work for a post-mortem (see below). Open the PR and let a new preview deploy if you need the live surface again.
**Logs from a torn-down or old preview.** Build and app logs are retained for about 30 days and stay readable **after** the preview is torn down - so you can debug why a past deploy failed without redeploying. If the logs come back empty, the preview may never have deployed, or its logs have aged out; re-run the preview to get fresh ones.
**A preview URL you hit directly 503s or times out on the first request.** This is only when *you* curl a preview URL (e.g. one from `get_endpoints`) - the debug tools themselves read platform state and are unaffected. Previews scale to zero when idle, so the first request wakes the pod and can 503 or time out in the meantime. That is a cold start, not a crash: wait a few seconds and retry. If it keeps failing after it has had time to wake, check `get_app_logs` - a real crash shows up there, a cold start does not.
**Which pull requests can I use?** Any PR in a repo you have connected to Autonoma, in an organization you belong to.
# Set up a preview with a coding agent (MCP)
> Autonoma gives you one command that registers this MCP with your coding agent and starts it on your whole setup - picking how your app gets its previews, configuring and deploying it or wiring your own pipeline, validating your SDK endpoint, and getting your scenario recipes provisioning - while you watch read-only in Autonoma. Hosted agents and CI run the same command with `--non-interactive`.
Setting an app up is one of the two jobs the [Autonoma MCP](/mcp/) does: connect your coding agent and it sets your previews up for you - works out how your app should get them, does the setup either way, asks you for any secrets it needs, and iterates until previews are landing - while you watch, read-only, in the Autonoma UI.
This is the default way to set Autonoma up, and the alternative to answering a questionnaire about your stack and then filling in a config form. Your agent already knows your repo - its build, its services, its env, how it deploys - so it can do the setup faster than you can describe it, and answer questions about your own schema that you would otherwise be guessing at. You stay in control: the UI shows every step live and hands control back the moment you take over.
## The agent picks the path too
An app gets its previews one of two ways, and they need completely different work:
* **[Autonoma-hosted](/preview-environments/)** - Autonoma builds and hosts a preview per pull request. The agent writes the build, services and env config, and deploys through these tools.
* **[Your own pipeline](/preview-environments/your-own-deploys/)** - your project already builds previews. Autonoma deploys nothing; the agent connects those previews so Autonoma knows when one is live.
On your own pipeline there are two ways Autonoma learns a preview is live, and the agent is told which applies rather than assuming. If your project is on **Vercel**, Autonoma’s Marketplace integration already reports every deployment, so the agent connects the project instead of writing anything - and connecting is also what makes a deployment-protected preview reachable at all. Every other host is a signed webhook the agent wires into your pipeline.
Being on Vercel does not commit you to reusing your own previews. Plenty of Vercel projects pick Autonoma-hosted previews deliberately, because an Autonoma-hosted preview gets its own database and a test run cannot leave rows in whatever your Vercel previews point at. If the agent picks Autonoma-hosted for a Vercel project, the Vercel tools stand down and it follows the hosted playbook.
**Autonoma-hosted is the default, and the agent picks it on its own.** Reusing your own previews is always your decision - the agent cannot choose it for you, and the server refuses it without your answer. What changes is whether the agent raises the option.
If your project is on Vercel, our integration makes it a genuine choice, so the agent will ask. It fits when your previews are entirely Vercel’s: the backend in the same deployable unit, and either data cleanly scoped to a tenant that can be deleted whole or a branchable database (Neon, Supabase, PlanetScale) giving each preview its own. A backend deployed elsewhere, or global tables a teardown would leak into, means Autonoma-hosted - which plenty of Vercel projects choose deliberately.
Anywhere else the agent will not bring it up, and will set up Autonoma-hosted previews. You can still ask for your own - it will explain both sides first. That is the same routing the [questionnaire](/preview-environments/your-own-deploys/#which-path-to-pick) applies when you set up by hand. A deploy workflow in your repo is not evidence either way: a YAML file does not say whether those previews work, which database they point at, or whether you want test data written into it.
The two mistakes are not symmetrical: a needless Autonoma-hosted preview costs an environment we build for you anyway, while wrongly reusing your own previews writes test data into a real shared database. The [trade-off is spelled out here](/preview-environments/your-own-deploys/#which-path-to-pick).
> **Note:**
>
> This is the same server you use afterwards, once Autonoma is reviewing your pull requests - see [debugging a flagged pull request](/mcp/#what-your-agent-can-do). One installation covers both. What is specific to onboarding is that the agent is pinned to one application by a pairing code, which the command mints for it; the debugging tools identify an app by its repo instead.
## Start from the Autonoma UI
You do not install or configure anything for this. Autonoma’s connect screen hands you **one command** - the [planner CLI](/test-planner/), carrying your app’s id - and that command does the wiring:
```bash
AUTONOMA_SHARED_SECRET= AUTONOMA_DISTINCT_ID= AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= AUTONOMA_APPLICATION_ID= npx @autonoma-ai/planner@latest
```
The values above are stand-ins - the command with yours filled in is on the connect screen at **[autonoma.app](https://autonoma.app)**, and the planner refuses to start on a placeholder token.
**Copy it, open a terminal in your project folder, and paste.** From there it registers this MCP server with your coding agent, authorizes it, mints a pairing code, and starts a **fresh** agent session on the job - then keeps going once the preview is up, through your test suite, the SDK integration and a scenario dry run. There is no second command and no pairing code for you to read off a screen.
Registering the server before starting the agent is the whole reason this is a command rather than something you paste into a session you already have open: an agent loads its MCP servers at startup, so it can never pick up one it registered itself. A CLI process is not an agent session, so it can do both in order.
> **Run it in a terminal, not inside a coding agent you already have open:**
>
> The command takes the terminal over and starts a coding agent of its own, so running it from inside one leaves two agents fighting over the same screen.
>
> **If you are a coding agent on the user’s machine** (Claude Code, Cursor, Windsurf, Codex): hand the command to the person you are working with rather than running it yourself. They have a terminal; you are in one they are already using.
>
> **If you are a hosted agent with no human beside you** (a CI job, an autonomous engineer): run it yourself and add `--non-interactive`. That is your path, and it is the whole of it - see [hosted and headless agents](#hosted-and-headless-agents).
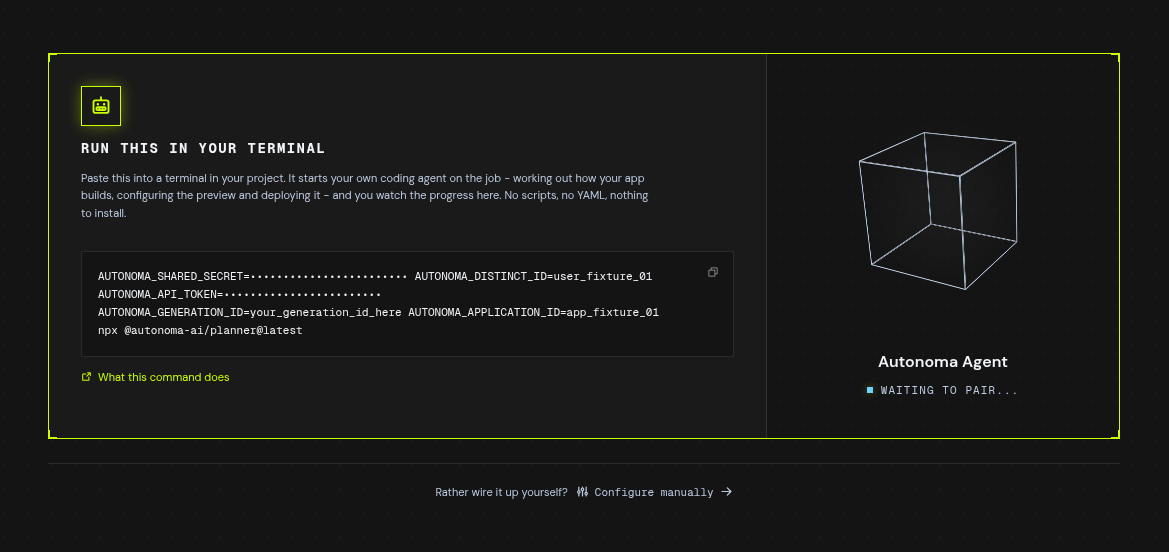
That one screen is the fork: the command is the default, and the questionnaire is the **Answer a few questions instead** link along the bottom.
The app id in the command is how the agent knows *which* app to set up. You never hand it a repo name, and it can only ever touch an app in an organization you belong to.
## Hosted and headless agents
The OAuth sign-in needs a browser on the same machine. If you are a hosted agent, an autonomous engineer, or a CI job, run the same command with `--non-interactive`:
```bash
AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= AUTONOMA_APPLICATION_ID= \
npx @autonoma-ai/planner@latest --non-interactive \
--coding-agent claude --frontend apps/web --backend apps/api
```
It never opens a browser - the coding agent it starts is authorized with the run’s API key as a bearer header instead - never blocks on a question, and reports each step as it starts and finishes so the process that launched it can follow along. Anything that would have been asked has to arrive as a flag; where guessing wrong would spend the run on the wrong thing it refuses with a clear error instead, and where the choice is cheap - which of two installed coding agents to use - it picks one and says which. See [running unattended](/test-planner/#running-unattended) for the full flag list.
This is the whole of the headless path. It replaces registering the MCP by hand and pairing yourself, and it does more than that ever did - the same one invocation carries on through the test suite, the SDK integration and the dry run.
### Wiring it up by hand instead
If you manage your own MCP servers and would rather drive the tools directly, that still works. Register the server with the [connection details](/mcp/#connection-details) and an [API key](/mcp/#headless-agents-and-ci), then ask the user for a pairing code from the Autonoma UI:
1. **Call `pair(code)`** - returns the `applicationId`, the linked repository, the preview path playbook, and the current config.
2. **Follow the loop** - `select_preview_path` → `get_config` / `apply_config` → `trigger_deploy` → `get_session_status` (poll until ready) → verify the app works → `go_live` → `validate_sdk` → fix recipes with `dry_run_scenario` / `update_recipe`.
3. **If `request_env` fires** - tell the user which env vars Autonoma needs and why. The user enters values in the Autonoma UI; you poll `get_session_status` until they land. You never see the values.
Pairing codes are single-use and expire after 15 minutes, so ask for the code that is on the user’s screen now rather than reusing one from earlier in the conversation.
> **Note:**
>
> **Where to find a pairing code.** The connect screen no longer shows one - the command mints its own. The **Configure with a coding agent** button on the Autonoma-hosted config step still opens the per-client install dialog with a code and a prompt (`configure my preview with the autonoma MCP`), and that is the one to use if you are driving the tools yourself.
The agent will also stop and wait for you again if the app needs secret values it does not have - `request_env` asks for key names only, you type the values into the Autonoma UI, and the agent polls `get_session_status` until they land. Secret values never pass through a tool call.
## How the agent sets Autonoma up
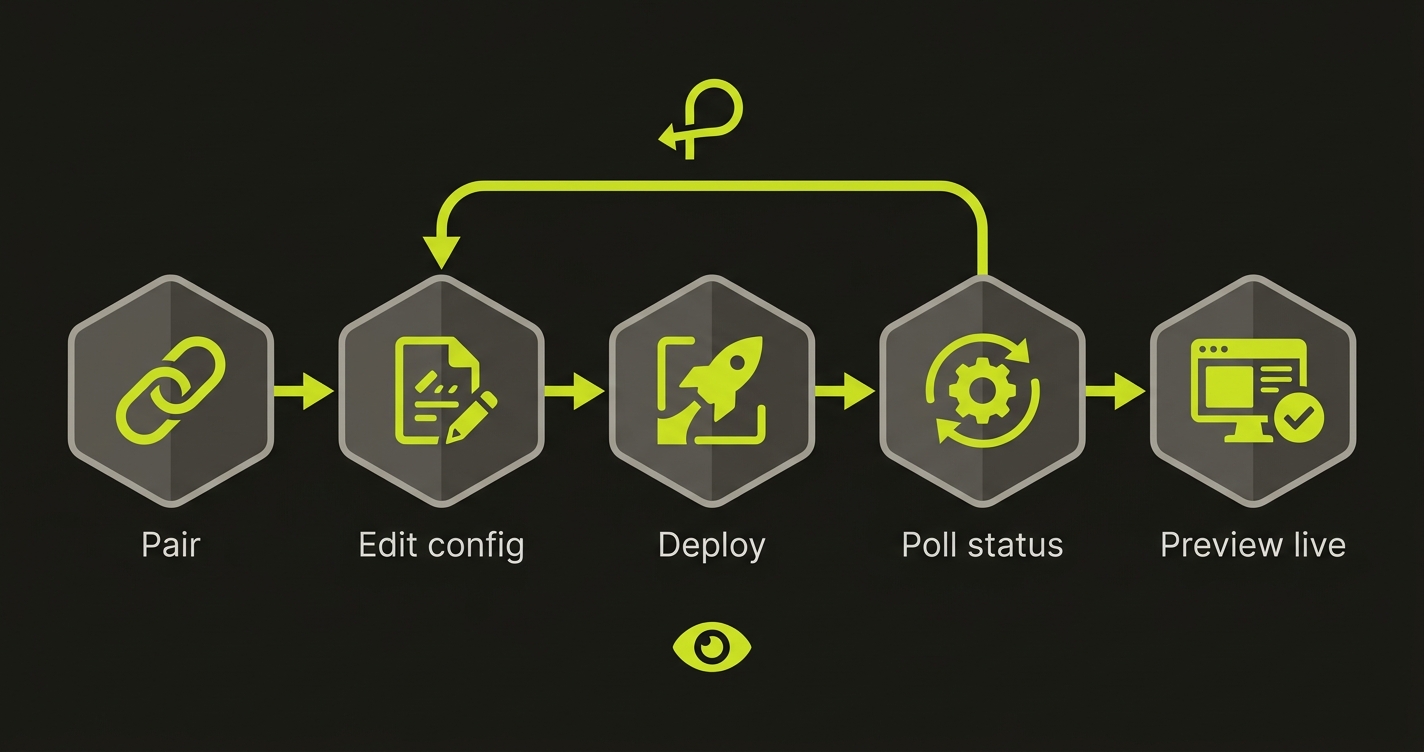
Once paired, the agent works a loop, and the Autonoma UI streams every step:
1. **Pair** - `pair(code)` claims your app for the agent and returns which repo it is linked to, how it gets its previews, and the playbook for that path. Your agent is told to pair **first**, before it analyzes your repo: pairing is low-risk (it makes no code changes and deploys nothing) and it is what flips the UI into “connected” and starts streaming activity, so you get immediate feedback instead of staring at an idle screen while the agent reads code.
2. **Check the repo, then pick the path** - `pair` returns the repository the app is linked to, and the agent is told to confirm its working directory matches before it reads a single file. An agent run from the wrong checkout would otherwise analyze an unrelated codebase and act on evidence that has nothing to do with your app. If the app has not chosen yet, the agent calls `select_preview_path` with `autonoma-hosted` - the default - and a one-line reason you can see. Reusing your own previews takes an explicit ask from you.
Everything after that depends on the path.
### If Autonoma hosts the preview
3. **Read and edit** - `get_config` / `apply_config` read and save the full preview environment config document. A save is validated; an invalid document returns the errors to fix. `apply_config` also takes an optional `branch` to set which branch the base preview deploys from (setting it here does not deploy).
The agent does this work on an **`autonoma-integration` branch** cut from your default branch, not on the default branch itself. Getting a preview to build usually takes real commits - a Dockerfile that was never built from a repo root, a missing build arg - and none of that belongs on your trunk unproven. It pushes that branch, points the base preview at it, and iterates there; the work reaches your default branch the way anything else does, as a pull request you review. Pointing the base preview at a branch does **not** change which branch Autonoma treats as your main one.
Your app has **one** preview config, and every environment deploys from it - the base environment and each open pull request alike. Saving one is a change to the whole app, not to the pull request you happen to be looking at. Per-environment configuration is a known limitation we may lift later; today there is no way to give one pull request a different config, and `prNumber` on the config tools chooses only which environment gets redeployed with the saved document. Secret values work the same way: `set_secret` stores them per app and service, not per pull request.
4. **Deploy** - `trigger_deploy` deploys the configured deploy branch as the preview.
Deploys do not queue: asking for a second one cancels the first. A first build takes minutes - impact analysis, then a build machine, then your images - and the honest reaction to that is to keep waiting, so `trigger_deploy` declines while a deploy is already running and hands back that deploy’s live status instead of restarting the clock. The agent can still supersede deliberately with `force`, which is the right call once it has pushed a fix the running build predates. Your own **Redeploy** button in the UI always supersedes: you are looking at the deploy in flight when you press it.
5. **Watch and iterate** - `wait_for_deploy` blocks until the deploy settles, and `get_session_status` returns the deploy status, the preview URL, diagnostics, and a `recentLogs` tail (build logs on failure, app logs when ready). The agent waits, reads the diagnostics and logs if the preview fails, fixes the config, and deploys again - until it comes up.
6. **Verify beyond readiness** - a ready preview can still be broken. Readiness is a TCP check on the app’s port, so it means the process is accepting connections, not that it serves anything correctly. (An app that declares no port - a worker, poller, or queue consumer that only makes outbound calls - is ready once its container is running, since there is no socket to check. Omit `port` on those: an app that declares a port it never binds can never pass the check, and previews are all-or-nothing, so it fails the whole environment.) The agent is instructed to exercise the main flow against the preview URL and then read the app’s runtime logs in `recentLogs` - not just declare done because the status says ready.
### If your own pipeline builds it, on Vercel
There is nothing to write here. Autonoma’s Vercel Marketplace integration reports every deployment already, so the work is connecting the project.
Being on Vercel is not itself a reason to take this path. It is still your own pipeline, so [where the test data lands](/preview-environments/your-own-deploys/#which-path-to-pick) is the question that decides it - and a Vercel preview points at your project’s own database by default, commonly the same one production uses, unless you have wired per-preview database branching. The agent is told to check that your schema is tenant-scoped before continuing here, and to go back and pick Autonoma-hosted if it is not.
3. **Read the connection state** - `get_vercel_setup` returns whether your organization has the Autonoma Vercel integration installed, which projects can be linked, which one is linked already, and that project’s ready deployments. It also returns a `nextStep` naming the exact call to make, so the agent does not have to infer the sequence.
4. **Link the project** - `link_vercel_project` connects the Vercel project to the app. The agent picks the candidate whose `matchesRepository` is true - the project building the same GitHub repo - and asks you if none matches, rather than guessing from a name. Linking is the step everything else depends on: it applies the deployment-protection bypass, without which Autonoma cannot reach a protected preview, and adopts the `AUTONOMA_SHARED_SECRET` Vercel injected into your project so your SDK handler’s signature matches.
5. **Get a deployment to point at** - the agent is told to *make* one rather than reuse an old one. The next thing it does is add your Autonoma SDK handler on its own branch, and Vercel builds a preview for every branch pushed, so it pushes that branch and uses its preview. That deployment is the only one that actually contains the handler, so onboarding never has to be re-pointed later, and a fresh build already carries the injected `AUTONOMA_SHARED_SECRET`, so nothing needs rebuilding.
To reuse an existing deployment instead, the agent **asks you which** - the same question this screen’s dropdown asks, over the same list - and then `create_vercel_deployment` rebuilds your choice so it picks up the shared secret. It will not take a production deployment on its own initiative.
6. **Wait, then commit it** - `get_vercel_deployment_status` polls until ready, telling a still-building deployment apart from a terminal `ERROR` or `CANCELED` so a failed build ends the wait instead of extending it. `select_vercel_deployment` then makes it the preview Autonoma tests against, which advances onboarding on its own - there is no signal to wait for and no confirm step.
> **Caution:**
>
> Whatever is selected here is where every scenario run creates and deletes its test data, through that deployment’s own database. That is why the agent will not point Autonoma at a production deployment on its own initiative - and why you should not either, unless test data in your production database is genuinely acceptable to you.
If your organization has not installed the integration at all, the agent cannot do it for you: it hands you the install link from `get_vercel_setup` and polls until you have.
### If your own pipeline builds it, anywhere else
There is no config to write, nothing to deploy and no build logs to read - `apply_config`, `trigger_deploy`, `request_env` and `get_target_logs` all refuse on this path rather than doing something surprising. The work is wiring one signed call:
3. **Read the contract** - `get_signal_setup` returns the endpoint, your `applicationId`, the shared secret, every body field, and a starter GitHub Actions workflow. The agent is told to treat that workflow as a template: it hangs off GitHub’s `deployment_status`, which many pipelines never emit, so the agent reads how your project actually deploys and makes the same call from whatever step knows a preview is live.
4. **Wire it in** - conventionally on a branch and a pull request, so you review it rather than the agent pushing to main. It puts the shared secret in your pipeline’s secret store rather than committing it.
5. **Prove it fired** - `get_signal_status` is the only confirmation the wiring works, so the agent triggers a real deploy and polls. It is told a hand-written `curl` proves nothing about your pipeline. It also watches `prReviewsConfirmed`: until a signal carries a `prNumber`, your app records preview URLs but no pull request is ever reviewed.
6. **Confirm** - `confirm_signal_setup` advances onboarding, once a signal has actually landed.
### Then, whichever path you took
7. **Take the app live** - `go_live` takes the app from a verified preview to reviewing, in one transition. Until it runs, Autonoma reviews no pull requests and holds back the comments it would have posted (they are re-run for your open pull requests when you finish, so nothing is lost). It does not wait on the SDK endpoint or the recipes below - those are separate work that continues afterwards. Called too early it refuses and names the step your app is actually on and the call that moves it forward, so you can see where it stalled rather than reading a state-machine error. On your own pipeline it goes live on trust: Autonoma cannot prove your signal carries a `prNumber` until a real pull request deploys, so open one afterwards and check `get_signal_status` reports `prReviewsConfirmed`.
8. **Validate your SDK endpoint** - once the preview is up, Autonoma needs the environment factory you implement. It is conventionally mounted at `/api/autonoma`, and any other route works as long as the agent records it: `sdk_path` on the app that serves the handler names the mount path, and an app that declares none is assumed to use the convention. The agent sets it with `apply_config` before validating, and `validate_sdk` writes back whatever path actually answered - so a handler on a different route is a one-line config change, not a reason to move your code. You will usually write it on its own pull request (conventionally titled `feat: autonoma-sdk`), and each pull request gets its own preview. `list_dry_run_targets` lists them - your main preview plus every open PR - and flags the one Autonoma detected as the SDK pull request. `validate_sdk` then points at that target, calls your handler’s `discover`, and stores the schema it returns - on an Autonoma-hosted preview and on a Vercel deployment alike. (The one target it cannot validate is a preview from your own non-Vercel pipeline: that needs the signing secret your pipeline signs with, and no tool here accepts a secret value, so the agent hands that step back to you in the UI.) If it fails, the error is your handler’s own, and `get_target_logs` reads that specific preview’s build or runtime logs for the stack trace behind it. (`get_session_status` only ever reports your main preview, so it will not show you a pull request’s preview.)
9. **Fix the test-data recipes** - a scenario is a named app state a test depends on (e.g. “logged-in admin with one open invoice”), and its recipe is the JSON your deployed Autonoma SDK follows to create those entities in the app’s own database. Before onboarding finishes a recipe often does not work yet. The agent lists scenarios with `list_scenarios`, reads one with `get_recipe`, and tests an edit end-to-end with `dry_run_scenario` (which calls your SDK `up` to create the entities, then `down` to remove them). Passing the edited `recipe` to `dry_run_scenario` runs it **without storing it**, so the agent can loop on the real SDK error without ever leaving a half-finished recipe in place; it promotes the one that passes with `save: true`, or saves directly with `update_recipe`.
There are two different things that can be wrong, and they iterate differently. A **recipe JSON** problem (a wrong field, an unresolved `{{variable}}`) is stored on Autonoma, so `update_recipe` -> `dry_run_scenario` takes effect immediately with no redeploy. A problem in your **SDK handler code** (the factory that turns the recipe into database rows) lives in your repo and only changes when the app is rebuilt: push the fix to the deploy branch (`get_config` / `pair` return which branch that is), redeploy - `trigger_deploy` for a PreviewKit preview, or wait for your own deployment to finish - and only then dry-run again, so you are not testing stale code. If that fix is already deployed to its own PR preview, `list_dry_run_targets` plus `dry_run_scenario`’s `target` points the run straight at it instead, with no redeploy of the app’s own preview. Fastest of all is to iterate the SDK handler against a local server and database first and confirm the rows land, then push a recipe you already know works.
Previews scale to zero when idle, so the first `dry_run_scenario` against a cold environment can return a 503 while it wakes. `dry_run_scenario` waits through that warm-up automatically (a bounded retry), so the first run may just take a little longer - a slow first attempt is the environment starting, not a broken recipe.
While the agent holds the config, the Autonoma UI is read-only and shows what it is doing in real time. You can press **Take over** at any point to reclaim the config and continue by hand; the agent stands down immediately. If the agent goes idle, control returns to you automatically.
The same split carries through the rest of setup. Once the preview is up the work moves into your terminal - the test suite, the SDK integration and the scenario dry run all happen there - so Autonoma stops offering you those steps and says so, with a live tally of what the platform has confirmed for itself: artifacts that landed, an SDK endpoint that answered, scenarios that provisioned. **Take over** there hands you the manual steps instead. Your run keeps going in the terminal either way, so stop it there too if you meant to take the work back.
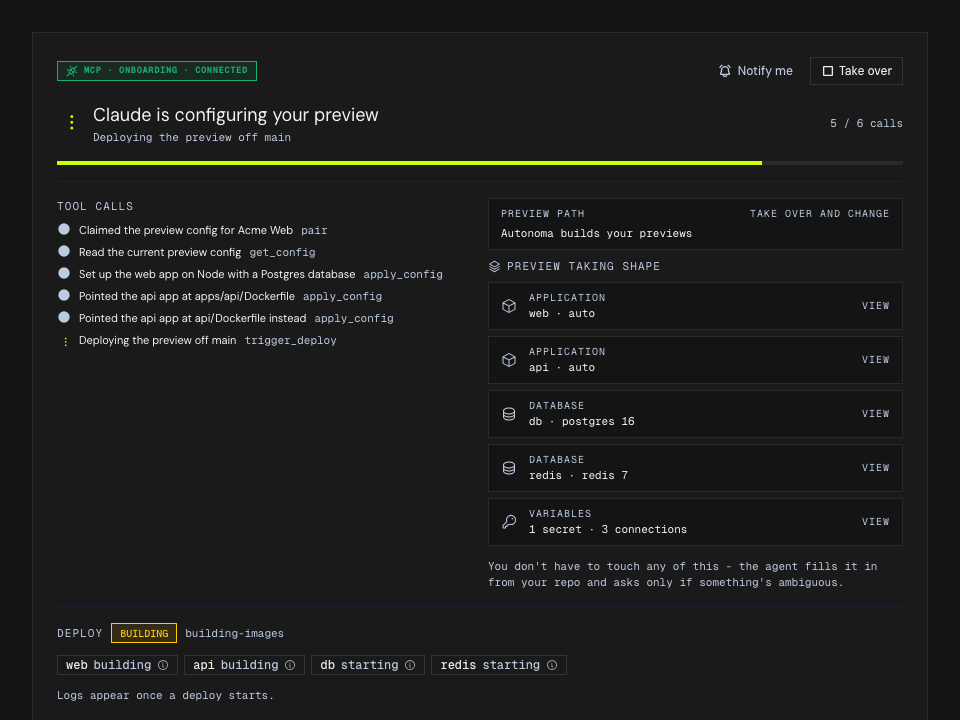
The tool-call list is an audit log: every tool in the [table below](#what-your-agent-can-do) shows up here as the agent uses it, so you can see exactly what it changed.
The server’s connect-time instructions already tell your agent what Autonoma is and the order to use these tools, so even an agent that has never seen Autonoma knows where to start. Any client can also reach that guidance without a setup file: invoke the **`configure_preview`** prompt (a guided flow that pairs with your code and runs the loop), or the **`connect_my_deploys`** prompt (the same flow scoped to the your-own-pipeline path - wiring the signed signal and proving it lands), or read the **onboarding guide** resource (`autonoma://onboarding-guide`) on demand - useful when a long session has pushed the connect-time instructions out of the agent’s context. Each path also has its own readable playbook resource - `autonoma://autonoma-hosted-playbook`, `autonoma://own-pipeline-playbook`, and `autonoma://vercel-playbook` - so an agent that paired into one path can re-read just that one without hunting through chat history.
## Secrets stay yours
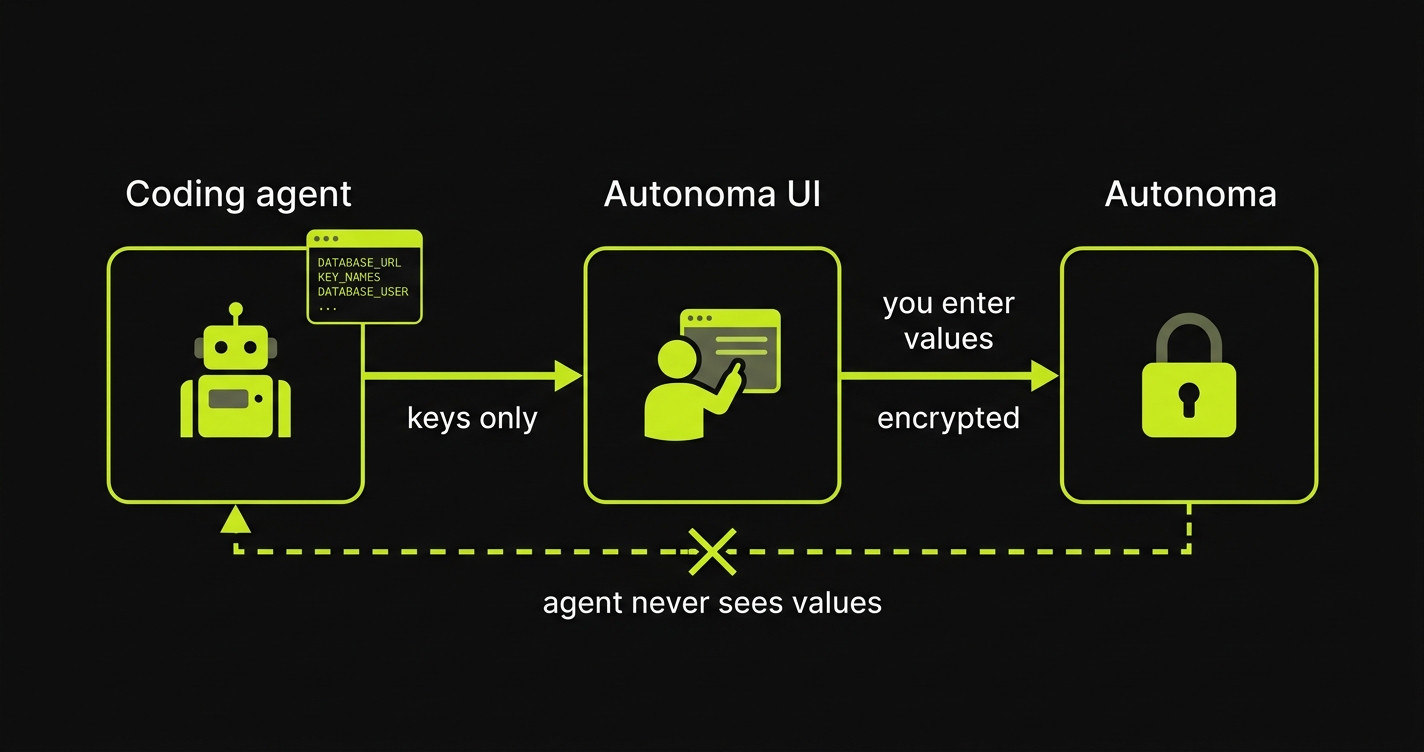
When your app needs a secret value the agent does not have - an API key, a database URL, a token - it calls `request_env` with only the **key names**. That surfaces a prompt in the Autonoma UI where **you** enter the values. The values go straight from your browser to Autonoma, encrypted; the agent never sees them and there is no tool that accepts a secret value.
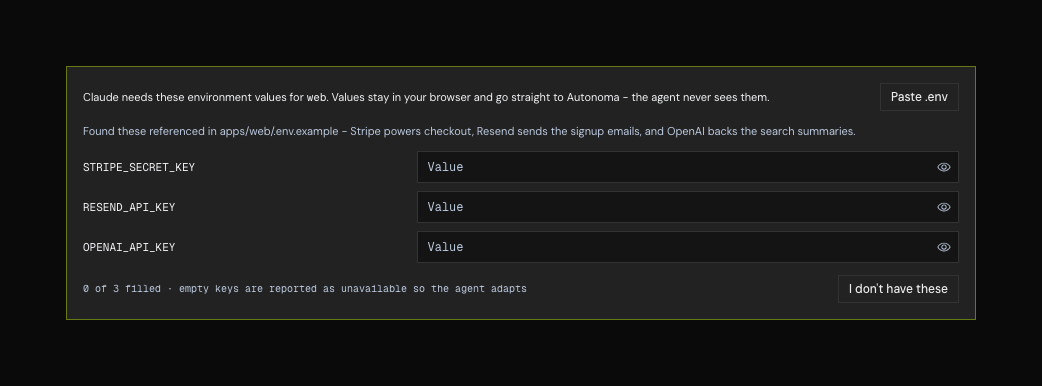
The agent tells you *why* it needs each key, and you can skip any of them - an empty key is reported back as unavailable so the agent adapts rather than stalling.
The agent should always ask you first whether to set env from your `.env` (you paste it into the UI) or to configure it yourself - so you decide, every time, what Autonoma stores.
Take as long as you need. While a request is pending the agent keeps polling `get_session_status`, so it picks the values up on its own once you submit them - you do not have to go back to the agent and tell it you are done (though you can, and it will check).
## What your agent can do
Some tools apply to only one path; called on the other they return an error naming the tool to use instead, rather than failing quietly.
| Tool | Input | Does |
| ------------------------------ | --------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `pair` | code | Claims the app using the pairing code from the UI; returns its `applicationId`, the `repository` it is linked to, how it gets its previews, the playbook for that path, and (Autonoma-hosted) the current config and `deployBranch` |
| `get_github_connection` | applicationId | Which repository this app is connected to, and which others are linkable. Safe at any point - if your pairing code came from the UI the repository is already connected, and this confirms which one. If the GitHub App is not installed it returns a link to hand to a human and the tool to poll, since GitHub has no API to install an app |
| `link_repository` | applicationId, repoFullName | Connects an app that has no repository yet, and completes the GitHub step. For apps being set up entirely through this MCP; if the app already has a repository it refuses rather than repointing it, which is a UI action |
| `select_preview_path` | applicationId, path, reason, `userRequest?` | Commits how the app gets its previews, when pairing reported none chosen yet. `autonoma-hosted` is the default; `their-pipeline` is refused until `userRequest` carries your own words choosing it. `reason` is one line, shown to you live |
| `get_config` | applicationId | Reads the current preview environment config document and the current `deployBranch` |
| `apply_config` | applicationId **or** repoFullName, document, `branch?`, `prNumber?`, `apply?`, `description?` | Saves the app’s full config document (validated; errors returned to fix). Never carries secret values. Optional `branch` sets the base preview’s deploy branch - during onboarding the pushed `autonoma-integration` branch, not your default; does not deploy. There is one config per app, shared by every environment - `prNumber` only picks which environment is redeployed with it, unless `apply` is false |
| `rename_app` | applicationId **or** repoFullName, from, to | Renames an app, keeping its stored secrets and build history. Use instead of renaming in `apply_config`: a document shows only the after-state, so a renamed app reads as a new one and the old app is deleted along with everything attached to it. Re-read `get_config` afterwards - the document you were holding still names the old app |
| `request_env` | applicationId, keys, appName | Asks you to enter secret values in the UI (keys only - the agent never sees the values) |
| `trigger_deploy` | applicationId, `force?` | Deploys the configured deploy branch (your default branch unless pointed at an integration branch) as the preview. Declines while a deploy is already running - a second one would cancel it, not queue behind it - and returns that deploy’s status instead; `force` supersedes it deliberately |
| `get_session_status` | applicationId | The single polling tool: control state, any pending request, deploy status, preview URL, diagnostics, and a `recentLogs` tail - build logs while building, the app’s runtime logs once ready, both on failure |
| `get_vercel_setup` | applicationId | Vercel: the state of the connection - whether your organization has the integration installed, which projects can be linked (with `matchesRepository` flagging the one building this repo), which is linked, its ready deployments, and a `nextStep` naming the call to make |
| `link_vercel_project` | applicationId, vercelProjectId | Vercel: links the project to this app. Applies the deployment-protection bypass and adopts the `AUTONOMA_SHARED_SECRET` Vercel injected into your project. Reversible - you can unlink in the UI |
| `create_vercel_deployment` | applicationId, vercelDeploymentId | Vercel: **deploys your project**, rebuilding an existing deployment so it picks up the injected shared secret - a real build on your Vercel account. Only needed when reusing an old deployment; a freshly pushed branch already carries the secret. Returns a **new** deployment id to poll and select, not the one passed in. The agent asks you which deployment to reuse, and never takes production unprompted |
| `get_vercel_deployment_status` | applicationId, vercelDeploymentId | Vercel: build state of one deployment, for waiting out that build. Distinguishes still-building from a terminal `ERROR` / `CANCELED`, so a failed build ends the poll loop |
| `select_vercel_deployment` | applicationId, vercelDeploymentId | Vercel: commits a ready deployment as the preview Autonoma tests against, advancing onboarding. A still-building deployment is rejected |
| `get_signal_setup` | applicationId | Your own pipeline, off Vercel: the deployment-signal contract - endpoint, `applicationId`, shared secret, every body field, and a starter workflow to adapt. Refuses when a Vercel project is linked, since the integration already reports deployments |
| `get_signal_status` | applicationId | Your own pipeline: whether a signed signal has landed, the URL it carried, and whether one has ever carried a `prNumber` (`prReviewsConfirmed`) - which is what per-PR reviews need |
| `confirm_signal_setup` | applicationId | Your own pipeline: marks the wiring done so onboarding advances, once a signal has actually landed |
| `go_live` | applicationId, description? | Takes a verified preview all the way to live, in one call - the last two onboarding steps, and what turns pull-request reviews on. Too early it refuses and names the step your app is on plus the call that moves it forward; already live it says so and changes nothing |
| `list_scenarios` | applicationId | Lists the app’s scenarios (named test-data states) and whether each already has a recipe |
| `get_recipe` | applicationId, scenarioId | Reads a scenario’s current recipe - the JSON `create` graph and `variables` your SDK uses to build its entities |
| `update_recipe` | applicationId, scenarioId, recipe, baseFingerprint? | Saves a corrected recipe as the scenario’s active version (the recipe name must stay the scenario’s name). Pass the `fingerprint` from `get_recipe` so a write that races another editor is rejected instead of overwriting it |
| `dry_run_scenario` | applicationId, scenarioId, recipe?, save?, target? | Runs a recipe against the deployed app (SDK `up` then `down`); on failure returns which phase failed and the SDK error. Pass a `recipe` to try an edit **without storing it** and `save: true` to promote one that passes; pass a `target` to run against a specific preview |
| `list_dry_run_targets` | applicationId | The previews a dry run can be pointed at - open PR previews and main, with which one Autonoma detected as the SDK implementation PR, and whether each is deployed yet |
| `validate_sdk` | applicationId, target, allowSelfHeal? | Provisions the target preview’s Autonoma secrets and calls your SDK handler’s `discover`, storing the schema on success. A `redeploy_started` result means the preview is rebuilding to pick up those secrets - poll `list_dry_run_targets` until it is ready, then call again (with `allowSelfHeal: false` after a signature rejection, so one that survives the redeploy is reported rather than redeployed through again) |
| `get_target_logs` | applicationId, target, source, app?, limit?, filter?, from? | Build or runtime logs for one preview named by a `list_dry_run_targets` id - the way to see a pull request’s preview, which `get_session_status` never reports |
## Troubleshooting
**The tools do not show up.** Confirm the client connected (e.g. `claude mcp list`) and that you completed the browser sign-in.
**The pairing code does not work.** Codes are single-use and short-lived. Reopen **Configure with coding agent** in the UI to mint a fresh one.
**The UI went read-only and I want to edit by hand.** Press **Take over** - the agent stands down and the form becomes editable again.
# Suite health
> The five-state signal on your application's pull request list - what each level means, exactly how the score is calculated from your analysis runs, and why every new app starts at Calibrating rather than at zero or at green.
Suite health answers one question: how much should you trust a failure this suite reports? It is a five-step ladder, and every new app starts in the middle.
Autonoma writes your test suite by reading your code. It has never operated your app. Some of what it wrote is wrong - an assertion about a screen that renders differently, a flow that needs a login step nobody documented - and it only finds out by running against real pull requests.
Suite health says that out loud, and shows it improving.
## The five levels
| Level | What it means |
| ------------------- | --------------------------------------------------------------------------------------------- |
| **Proven** 5/5 | Every failure here is worth reading. False alarms are rare. |
| **Steady** 4/5 | Tests are holding across pull requests and the agent is healing drift on its own. |
| **Calibrating** 3/5 | New suite. Written from your app, not yet proven against it. Expect some noise. |
| **At risk** 2/5 | More tests are flaking than passing. A few decisions from you will fix it. |
| **Degraded** 1/5 | Failures are piling up unresolved. The agent can no longer tell a real bug from a stale test. |
Every new app starts at **Calibrating**. Not at zero, and not at green - both would be lies. A suite that has never run is not broken, and it is not proven either.
## What is measured
The score is the **trust rate**: of the tests Autonoma investigated, how many produced a verdict you can act on.
```plaintext
trust = (passed + confirmed bug) / every finding in the window
```
Every analysis run resolves each test it investigated to one verdict. Only two of them tell you something true about your application:
| Verdict | Counts toward trust? | Why |
| ------------------- | -------------------- | --------------------------------------------------- |
| Passed | Yes | The app did what the test expected. |
| Bug | **Yes** | The app misbehaved, and the suite caught it. |
| Environment failure | No | The preview was unavailable, so nothing was tested. |
| Test data issue | No | The scenario was mis-seeded, so nothing was tested. |
| Engine artifact | No | Our test harness flaked or crashed. |
| Plan mismatch | No | The app was fine; the test does not match it yet. |
> **Note:**
>
> **A confirmed bug raises your suite health, it does not lower it.** A suite that finds a real bug is a suite doing its job. What lowers health is a run that reaches no verdict at all - because then a failure tells you nothing.
### The window
The score is computed over your **last 20 analysis runs**, no older than 30 days.
* Both pull-request runs and main-branch runs count.
* A run that selected no tests is excluded entirely. It is neither good nor bad.
* The rate is computed over every finding in the window, not per run, so a pull request that produced a hundred findings weighs a hundred times as much as one that produced a single finding. The evidence gates below are the part that counts each run once.
Runs rather than calendar days, because a busy repository produces a hundred runs in a week and a quiet one produces three in a month. A fixed time window makes the first number twitchy and the second meaningless.
## What moves it
| Raises it | Lowers it |
| --------------------------------------------------- | --------------------------------------------------- |
| Tests that pass when Autonoma checks a pull request | Failures left unresolved for days |
| Autonoma self-healing a test inside a pull request | Tests that flake more often than they pass |
| A flagged bug fixed before the pull request merges | Preview environments or test data that keep failing |
Four bounded adjustments sit on top of the trust rate. None can dominate:
| Adjustment | Effect |
| --------------------- | --------------------------------------------------------------------------------------------------------------------------------- |
| **Self-heal rate** | Up to +8, scaled by how often a re-planned test then passes. Needs at least 5 attempts, so one lucky heal is not a perfect score. |
| **Triage** | +5 when you resolve an issue in the window, +10 for three or more. |
| **Pipeline failures** | Up to -15 when analysis runs die outright. A run that never finishes produces no findings, so it would otherwise be invisible. |
| **Stale failures** | -5 per open issue older than a week on a live branch, capped at -20. |
> **Note:**
>
> Self-heal is scored as a **rate**, not a count. A healed test already lands in the trust rate as a pass, so paying per heal would count it twice - and would reward a suite for needing a lot of repair rather than for repairing well.
## Why you cannot jump straight to Proven
The score alone does not set the level. Evidence gates clamp it, in both directions.
| You cannot reach | Until |
| ---------------- | ------------------------------------------------------------------------------------------------------------- |
| **Steady** | 8 runs, 3 distinct branches, and a week of history |
| **Proven** | 20 runs, 8 distinct branches, a month of history, no stale open failures, and at least one issue you resolved |
And symmetrically - **you cannot fall without evidence either**:
| You cannot drop to | Until |
| ------------------ | ------- |
| **At risk** | 5 runs |
| **Degraded** | 12 runs |
This is what keeps a brand-new app off both ends of the scale. Three unlucky runs in your first week is not a degraded suite, and three lucky ones is not a proven one.
Most suites reach Steady in about two weeks of normal pull-request traffic. Proven takes roughly a month, on purpose.
## Going quiet
If nothing runs for three weeks **and** you have unresolved failures sitting open, the level decays a step, and another for every two weeks after that. That is the “nobody is using it and it has rotted” case, and it is the one situation where the evidence floors do not protect you - a week-old untriaged failure is its own evidence, whatever your run count says.
Silence on its own is not a failure. With a clean backlog, the level simply stops moving.
## Two suites at the same level can need opposite things
The level tells you how much to trust a failure. It does not tell you what to do, because the same score arrives by very different routes.
Hover the meter and the tooltip names the dominant cause:
| If most failures are | Then |
| -------------------- | ------------------------------------------------------------------------------------------------ |
| Test data | Your recipe is the fastest thing to fix. Nothing to do in your code. |
| Environment | Your preview could not run. A missing secret or a broken service. |
| Plan mismatch | Your environment is solid; the tests do not match the app yet. More pull requests converge them. |
| Engine artifact | Our test harness, not your app. That one is on us. |
Two real examples from the same level: one customer’s environment and test data were among the healthiest we run and only their test plans lagged - they needed to keep shipping pull requests. Another had self-healing working hard but a flaky preview underneath it - more pull requests would not have helped at all.
When the level is At risk or Degraded, the tooltip grows a **Fix it** button that hands the whole backlog to your coding agent in one prompt. See [Fixing a degraded suite](/suite-health/fixing).
# Fixing a degraded suite
> Hand every unresolved Autonoma failure to your coding agent in one prompt - how the Fix it button works, where each kind of fix actually lives, and why fixing one shared cause usually clears most of the backlog.
When suite health drops to At risk or Degraded, the meter offers to hand the whole backlog to your coding agent in a single prompt. Most of the time one fix clears most of it.
A degraded suite looks like a lot of work. It usually is not. The same failure tends to land on every open pull request at once, so a backlog of two hundred findings is often one broken thing counted two hundred times.
## Fix it
Hover the suite-health card on your application’s pull request list, beside the page heading. At **At risk** and below, the panel it opens carries a **Fix it** button.
It opens a dialog with three steps:
1. **Install the Autonoma MCP** - per-client snippets for Claude Code, Cursor, Windsurf and others.
2. **Authorize Autonoma** - the first tool call opens a browser to sign in. Skip this and every tool fails.
3. **Copy the prompt** - one button. Paste it into your agent.
The prompt is written from your actual findings. It names the real pull requests, the real counts, and the specific tools that fix each kind - so your agent does not have to go rediscover any of it, which is the step that usually fails.
> **Name the server:**
>
> The prompt asks for `autonoma` by name - the [Autonoma MCP](/mcp) - rather than “the Autonoma MCP”. An agent with several MCPs connected cannot resolve a generic name and will pick one, so keep the name in whatever you paste.
## Where each fix actually lives
This is the part worth internalising, because **two of the three are not code changes**. Every finding carries a kind, and the kind tells your agent where to go:
| Kind | What happened | Where the fix lives | Redeploy? |
| --------------- | -------------------------------------------------------------- | ----------------------------------------------------------------------------------------- | --------------------- |
| **Bug** | Your app misbehaved | Your repository - push to the pull request’s branch | Yes, normally |
| **Environment** | The preview could not run - a missing secret, a broken service | Autonoma config: `get_secret_status`, `set_secret`, `edit_previewkit_config` | No repo change at all |
| **Test data** | The scenario was missing or mis-seeded | Your scenario recipe: `list_scenarios`, `get_recipe`, `update_recipe`, `dry_run_scenario` | No redeploy |
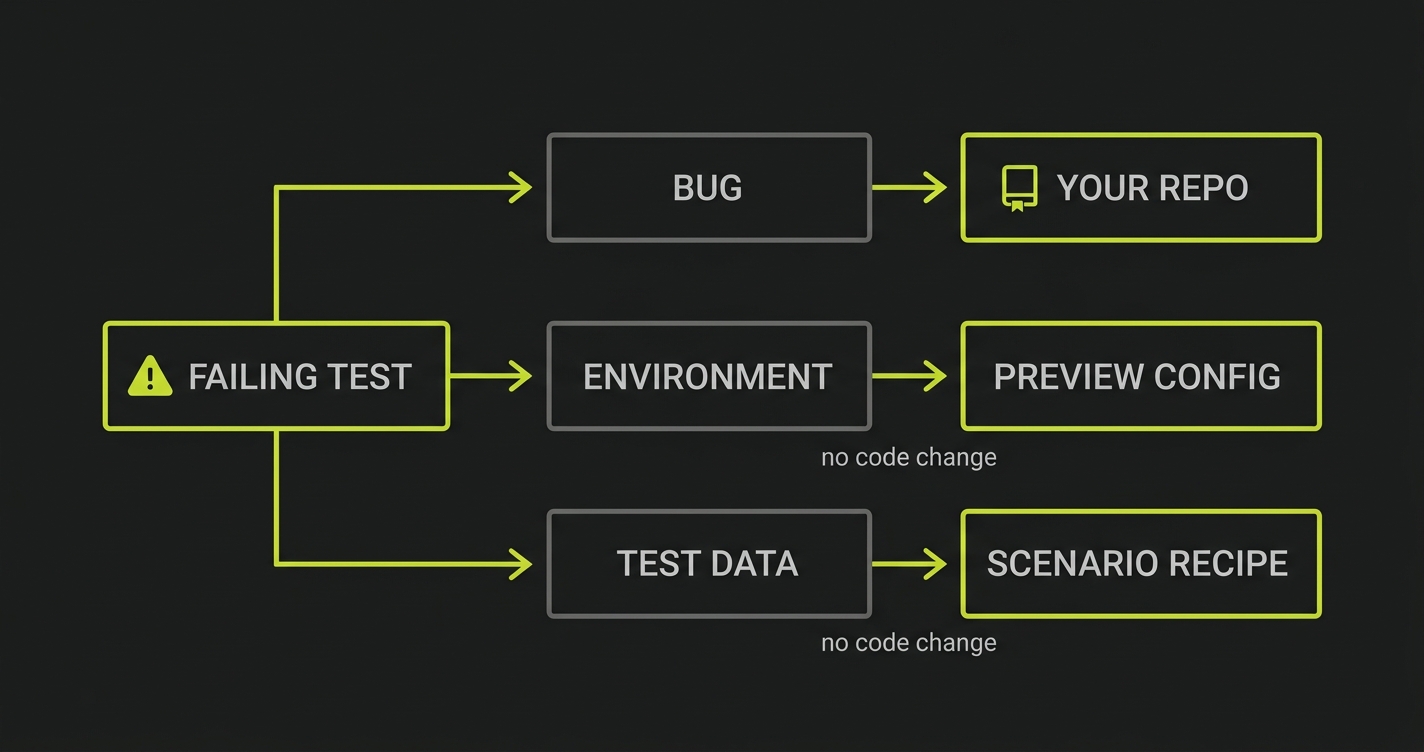
An agent that does not know this treats every failure as a code problem and goes hunting through your source for a bug that is not there. Told where to look, it fixes a missing secret in one call.
## Start with the open pull requests
The prompt leads with what is blocked right now, ordered by how much each is carrying.
Merged and closed pull requests are listed too, but explicitly as **reference only** - do not go fix them. Nobody is waiting on a closed branch. They are there because their runs often show the same failure with more evidence attached, which helps diagnose something still live elsewhere.
## One cause, many pull requests
This is where the leverage is.
When Autonoma sees the same failure on more than one branch, the prompt says so, with the numbers:
```text
Most of this is probably ONE problem. These findings repeat across pull requests:
· 10 pull requests, 2 still open - 185 findings - "Scenario setup failed
before the app was exercised: SDK returned HTTP 500"
Diagnose the shared cause FIRST and fix it once, then re-run and see how many
clear before you move on.
```
That is a real example. One misbehaving endpoint accounted for 185 of that app’s 200 findings. Worked one finding at a time, an agent would have repaired the same thing ten times over. Fixed once, roughly 85% of the backlog cleared.
The prompt only says this when it is true. Repeats are matched on the exact finding, never a fuzzy guess - so when your failures are genuinely distinct, the section is simply absent rather than sending your agent hunting for a pattern that is not there.
> **Tip:**
>
> After the first fix, re-run the affected pull requests before working down the rest of the list. The list is usually much shorter than it was.
## What it will not do
The prompt tells your agent, in as many words, **not to disable, skip or delete a test to make a run go green**. If a test is genuinely wrong about your app, it is asked to say so and explain why rather than removing it quietly.
This matters more than it sounds. A suite that gets back to Calibrating by deleting its failures is worth less than the suite that was failing - you would have traded a signal you could act on for a green light that means nothing.
## Findings that are not yours to fix
Two kinds never appear in the prompt:
* **Engine artifacts** - our test harness flaked or crashed. Ours to fix, and there is nothing useful for your agent to do.
* **Plan mismatches** - the app rendered correctly but the test does not match it. Autonoma’s own self-healing loop owns these and retries them on later runs.
They still count against your trust rate, because a run that flakes tells you nothing either way. They are just not work we would send you after.
## After the fix
Suite health recomputes on your next analysis run. Clearing a backlog moves two things at once: the stale-failure penalty comes off, and the runs that follow start reaching real verdicts again.
Resolving issues also feeds the triage adjustment, which is one of the requirements for reaching [Proven](/suite-health).
# Test Planner
> The planner CLI is how you set Autonoma up. One command sets up your preview environment, generates your end-to-end test suite, wires the SDK and proves your test data - interactively, or unattended with `--non-interactive` for a hosted agent or a CI job.
The planner is the command Autonoma hands you, and it does the whole setup: a preview environment, a complete end-to-end test suite read from your codebase, the SDK integration that creates your test data, and a dry run proving it works. One invocation, start to finish, on managed Autonoma credits - no LLM API key required.
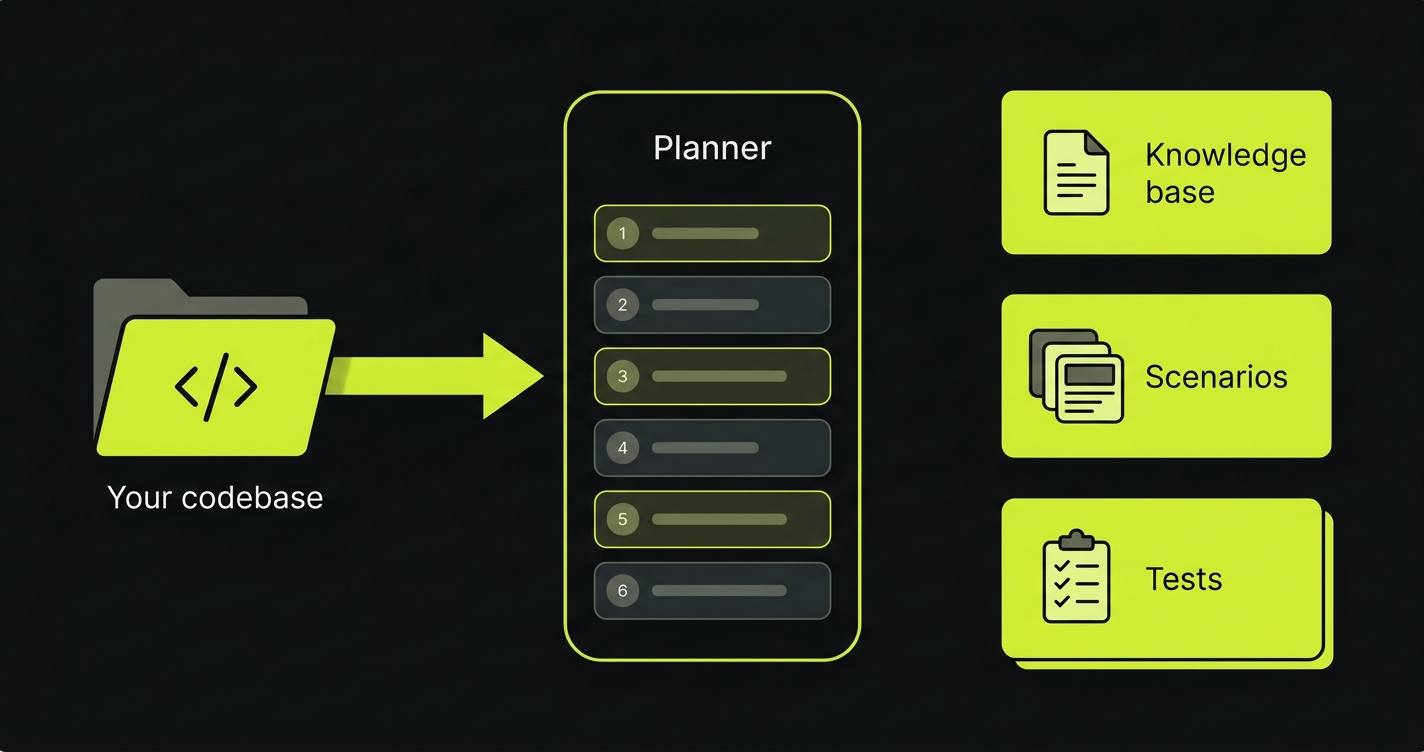
## Run it
Autonoma shows you this command when you connect your app, with your token and ids already baked in. It has this shape:
```bash
AUTONOMA_SHARED_SECRET= AUTONOMA_DISTINCT_ID= AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= AUTONOMA_APPLICATION_ID= npx @autonoma-ai/planner@latest
```
> **Get yours, don’t copy this one:**
>
> The values above are stand-ins. **[Open Autonoma](https://autonoma.app)** and copy the command off your app’s connect screen - it arrives with the token and ids filled in. The planner rejects a placeholder token on sight rather than starting a run that cannot authenticate.
Copy it, open a terminal in your project, and paste. That is the whole of setup. There is no second command, no step list to work through, and nothing to install - `npx` fetches the planner and runs it.
> **Run it in a terminal, not inside a coding agent you already have open:**
>
> The command takes the terminal over and starts a coding agent of its own. Pasting it into a session that is already running leaves two agents fighting over one screen.
>
> **If you are a coding agent on the user’s machine** (Claude Code, Codex, Cursor): hand this command to the person you are working with rather than running it. **If you are a hosted agent with no human beside you** (a CI job, an autonomous engineer): run it yourself and add `--non-interactive` - see [running unattended](#running-unattended).
### What it needs from Autonoma
The command carries its own configuration as environment variables, so the only one you ever set by hand is a token for a standalone run.
| Variable | Required | What it does |
| ------------------------- | ---------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `AUTONOMA_API_TOKEN` | yes | The run’s credential. Create one under **Settings → API keys** |
| `AUTONOMA_APPLICATION_ID` | no | The app this run belongs to. With it, the run also sets up the preview environment and validates the result; without it the planner runs standalone against any repository |
| `AUTONOMA_GENERATION_ID` | for upload | The setup its generated artifacts are uploaded against |
| `AUTONOMA_SHARED_SECRET` | no | Signs the SDK and webhook requests the run makes on your behalf |
| `AUTONOMA_API_URL` | no | Point at a non-production Autonoma. Defaults to production |
| `AUTONOMA_DEBUG` | no | Set to `1` or `true` for diagnostics on stderr, plus a full JSONL transcript of the run at `~/.autonoma/debug/.jsonl` |
| `AUTONOMA_DEBUG_FILE` | no | Write that transcript to this path instead, without the stderr noise. Independent of `DONT_TRACK` - it never leaves your machine |
| `DONT_TRACK` | no | Set to `1` or `true` to turn off analytics, logs and session replay together |
### Where a run starts
The planner reads your app’s setup status when it launches and begins at the first thing still outstanding, so re-running it never redoes finished work:
* **No preview environment yet** - it starts there, then continues into the pipeline.
* **A preview you already set up** (by hand, or on a previous run) - straight to the pipeline.
* **Everything but the scenario dry run** - straight to the dry run.
* **No `AUTONOMA_APPLICATION_ID`** - the planner runs standalone against the repository and uploads nothing.
If it is interrupted, `--resume` picks up from the step that did not finish.
### While it runs
The run holds your app’s setup for as long as it is going, so Autonoma stops offering you the steps it is doing and points you back at your terminal. **Take over** in the web app hands those steps back to you - your run keeps going either way, so stop it in the terminal too if you meant to take the work back.
The same command also appears on the **Upload test artifacts** step of onboarding, for an app whose preview you set up by hand. It is the same command and the same run; it simply has less left to do.
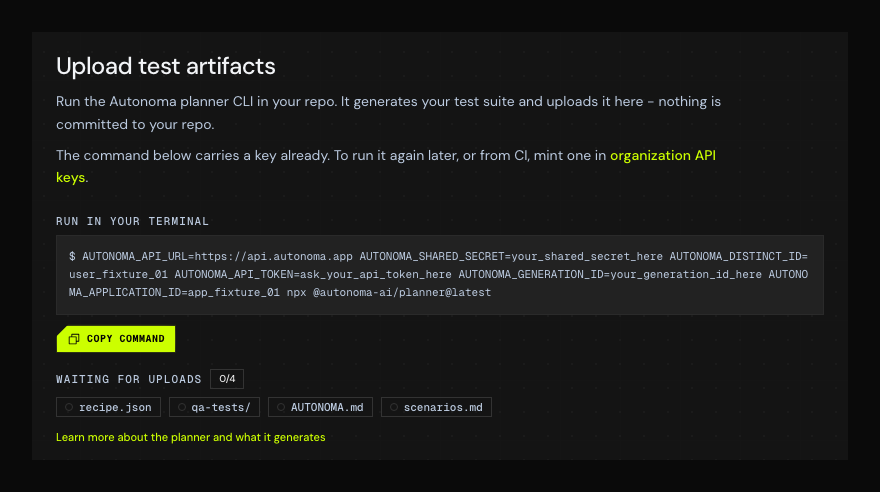
The four chips are how you watch the upload land: the count climbs and each one fills in as the planner sends it. Hover a chip to see what that file is.
That `npx` line downloads and runs the planner, published on npm as `@autonoma-ai/planner`. `npx` runs it without installing it, so there is no `autonoma-planner` command on your `PATH` afterwards - keep using the full `npx` form for every command below. Run it from the root of the repo you want to test. It works against your **frontend** (to map pages and flows) and your **backend** (to map data models and wire up test data). If those live in separate repos, run it where it can reach both.
Everything it produces is readable live in the dashboard as it’s written.
## Watch it work
A full run can take an hour or more, so the pipeline phase runs inside a live dashboard right in your terminal.
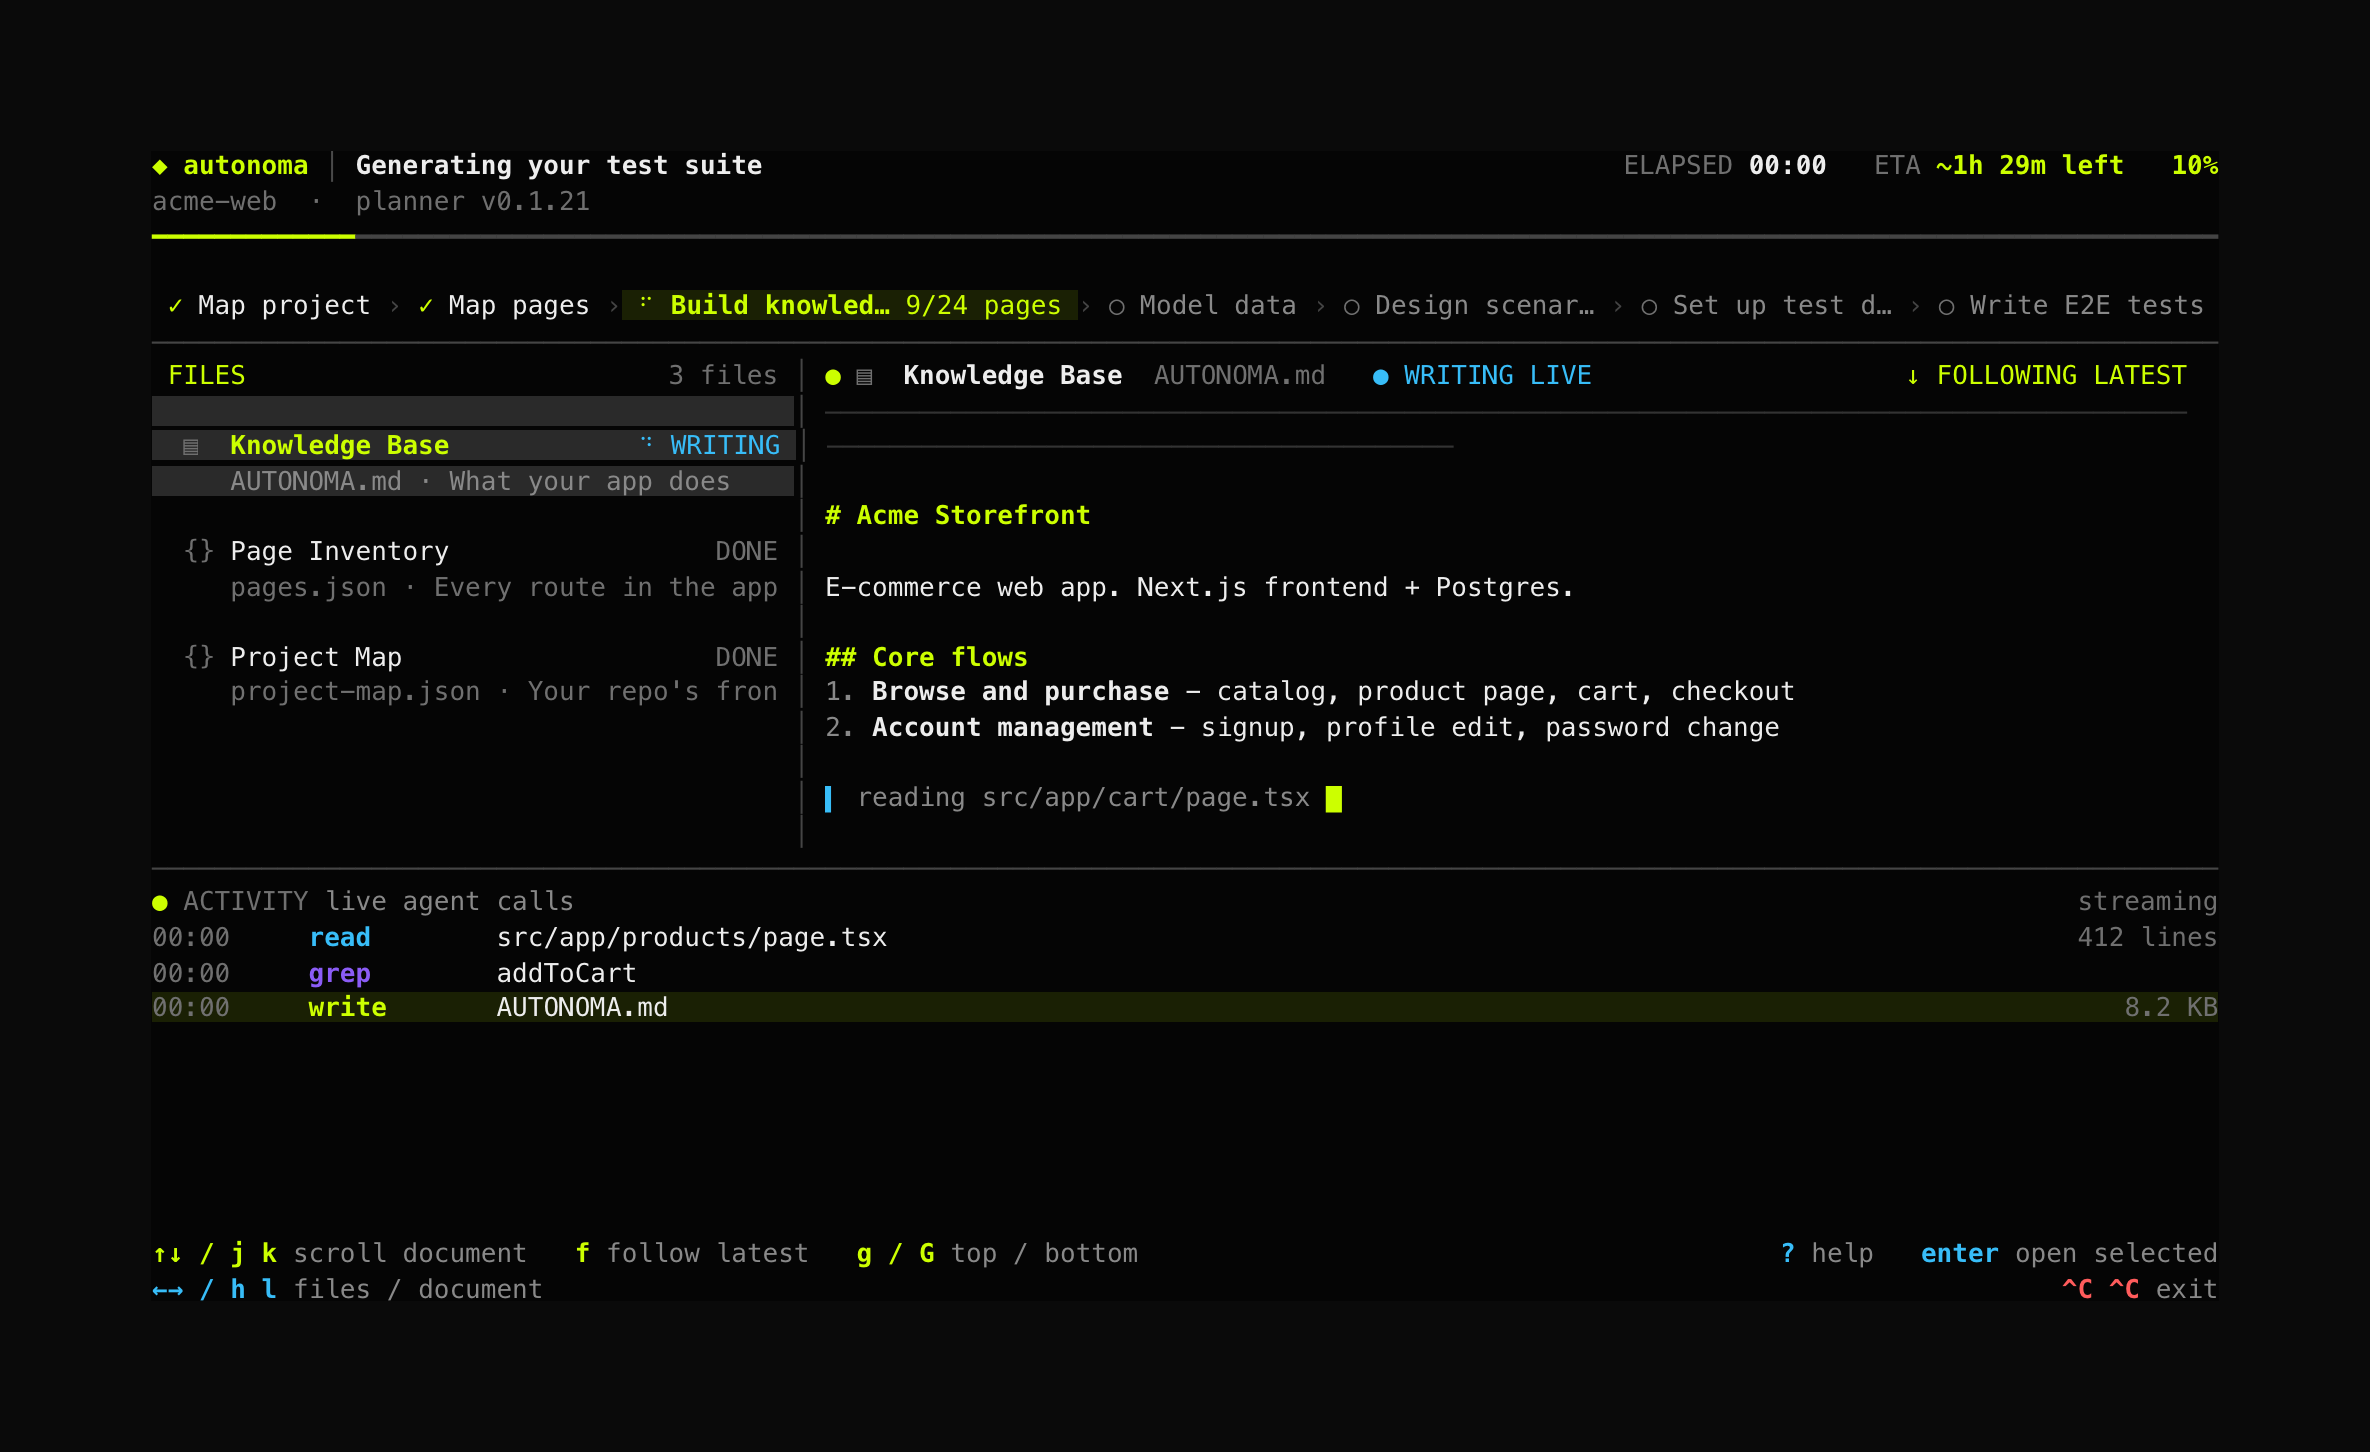
The pipeline runs as a strip across the top, so you can see every step and which one is live. Underneath, the files it has produced sit on the left and the document being written right now fills the pane on the right - streaming live from disk, so you can read the knowledge base, scenarios and tests as they are produced. The activity feed shows exactly what the agent is doing at any moment, and the top bar tracks elapsed time and a single estimated time remaining.
Navigate with the arrow keys (or `h/j/k/l`): move between panels, open any produced file, and scroll it while the run continues. Press `f` to jump back to following the newest file. Progress is saved continuously - Ctrl+C twice exits, and `--resume` picks up where you left off.
The dashboard needs a terminal window of at least 80x24. In anything smaller it shows a short resize notice rather than a layout it cannot fit, and returns by itself the moment the window is big enough. The run continues regardless - only the display waits.
## What it does
| # | Step | What it does | Output |
| - | ------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------ |
| 1 | **Preview environment** | Hands your own coding agent the job of setting up a real per-pull-request deployment for Autonoma to test against. Skipped when you already have one. | a live preview |
| 2 | **Map your project structure** | Finds your frontend(s) and backend(s) so later steps scan only what matters. | `project-map.json` |
| 3 | **Find your pages** | Maps every page and route in your app. | `pages.json` |
| 4 | **Build a knowledge base** | Learns your features, flows, and UI patterns. | `AUTONOMA.md` |
| 5 | **Map your data models** | Finds what your app stores and how each record is created. | `entity-audit.md` |
| 6 | **Design test scenarios** | Decides the realistic data each test runs against. | `scenarios.md` |
| 7 | **Set up test data** | Hands the [Environment Factory](/environment-factory/) integration to your own coding agent, which implements it, validates it live, and produces the recipe. | `recipe.json` |
| 8 | **Generate the tests** | Writes the E2E tests as natural-language markdown, covering every page and feature, then uploads the suite. | `qa-tests/` |
### Step 1: your coding agent sets up the preview environment
Autonoma tests against a **preview environment** - a real deployment of your app, built per pull request. Working out how your app should get one means reading your build, your services and your environment, which your coding agent can do far faster than you can describe it.
So the planner hands that job over. It registers Autonoma’s [MCP server](/mcp/) with your agent and then starts a **fresh session** on the task. Registering first is the whole trick: an agent loads its MCP servers at startup, so it can never pick up one it registered itself - which is why this has to come from a command rather than from inside a session you already have open.
What the agent does next depends on which path your app takes - Autonoma-hosted previews, Vercel, or your own pipeline. All three are covered in [set up a preview with a coding agent](/mcp/configure-preview), along with the tools it uses and what you see in the Autonoma UI while it works.
The planner reads whether the preview is up from Autonoma rather than from the agent’s exit code - an interactive session does not exit when its work is done, and its exit status says nothing about whether a deployment landed. That is also what makes this identical across all three paths. If the preview never comes up, the run carries on generating your test suite and tells you: only the scenario dry run needs a live preview.
### Step 7: your coding agent wires the test data
Setting up test data means wiring the [Environment Factory](/environment-factory/) into your backend - real code in your repo. Instead of handing you instructions to paste somewhere, the planner launches your **locally installed coding agent** (Claude Code or Codex CLI) in one session, the same way `git commit` opens your editor: the dashboard steps aside, your agent takes the terminal, and control returns when it’s done.
The agent installs the SDK, builds the endpoint, registers factories that call your app’s real creation code, generates the test-data recipe, and validates every entity against your locally running app - creating records, checking your database, tearing them down, and checking they’re gone. It works on its own branch, cut from your repo’s default branch, and pushes the finished integration as a pull request for you to review - so nothing lands on your default branch unreviewed. When it reports the integration complete, the planner uploads the recipe and moves on to test generation.
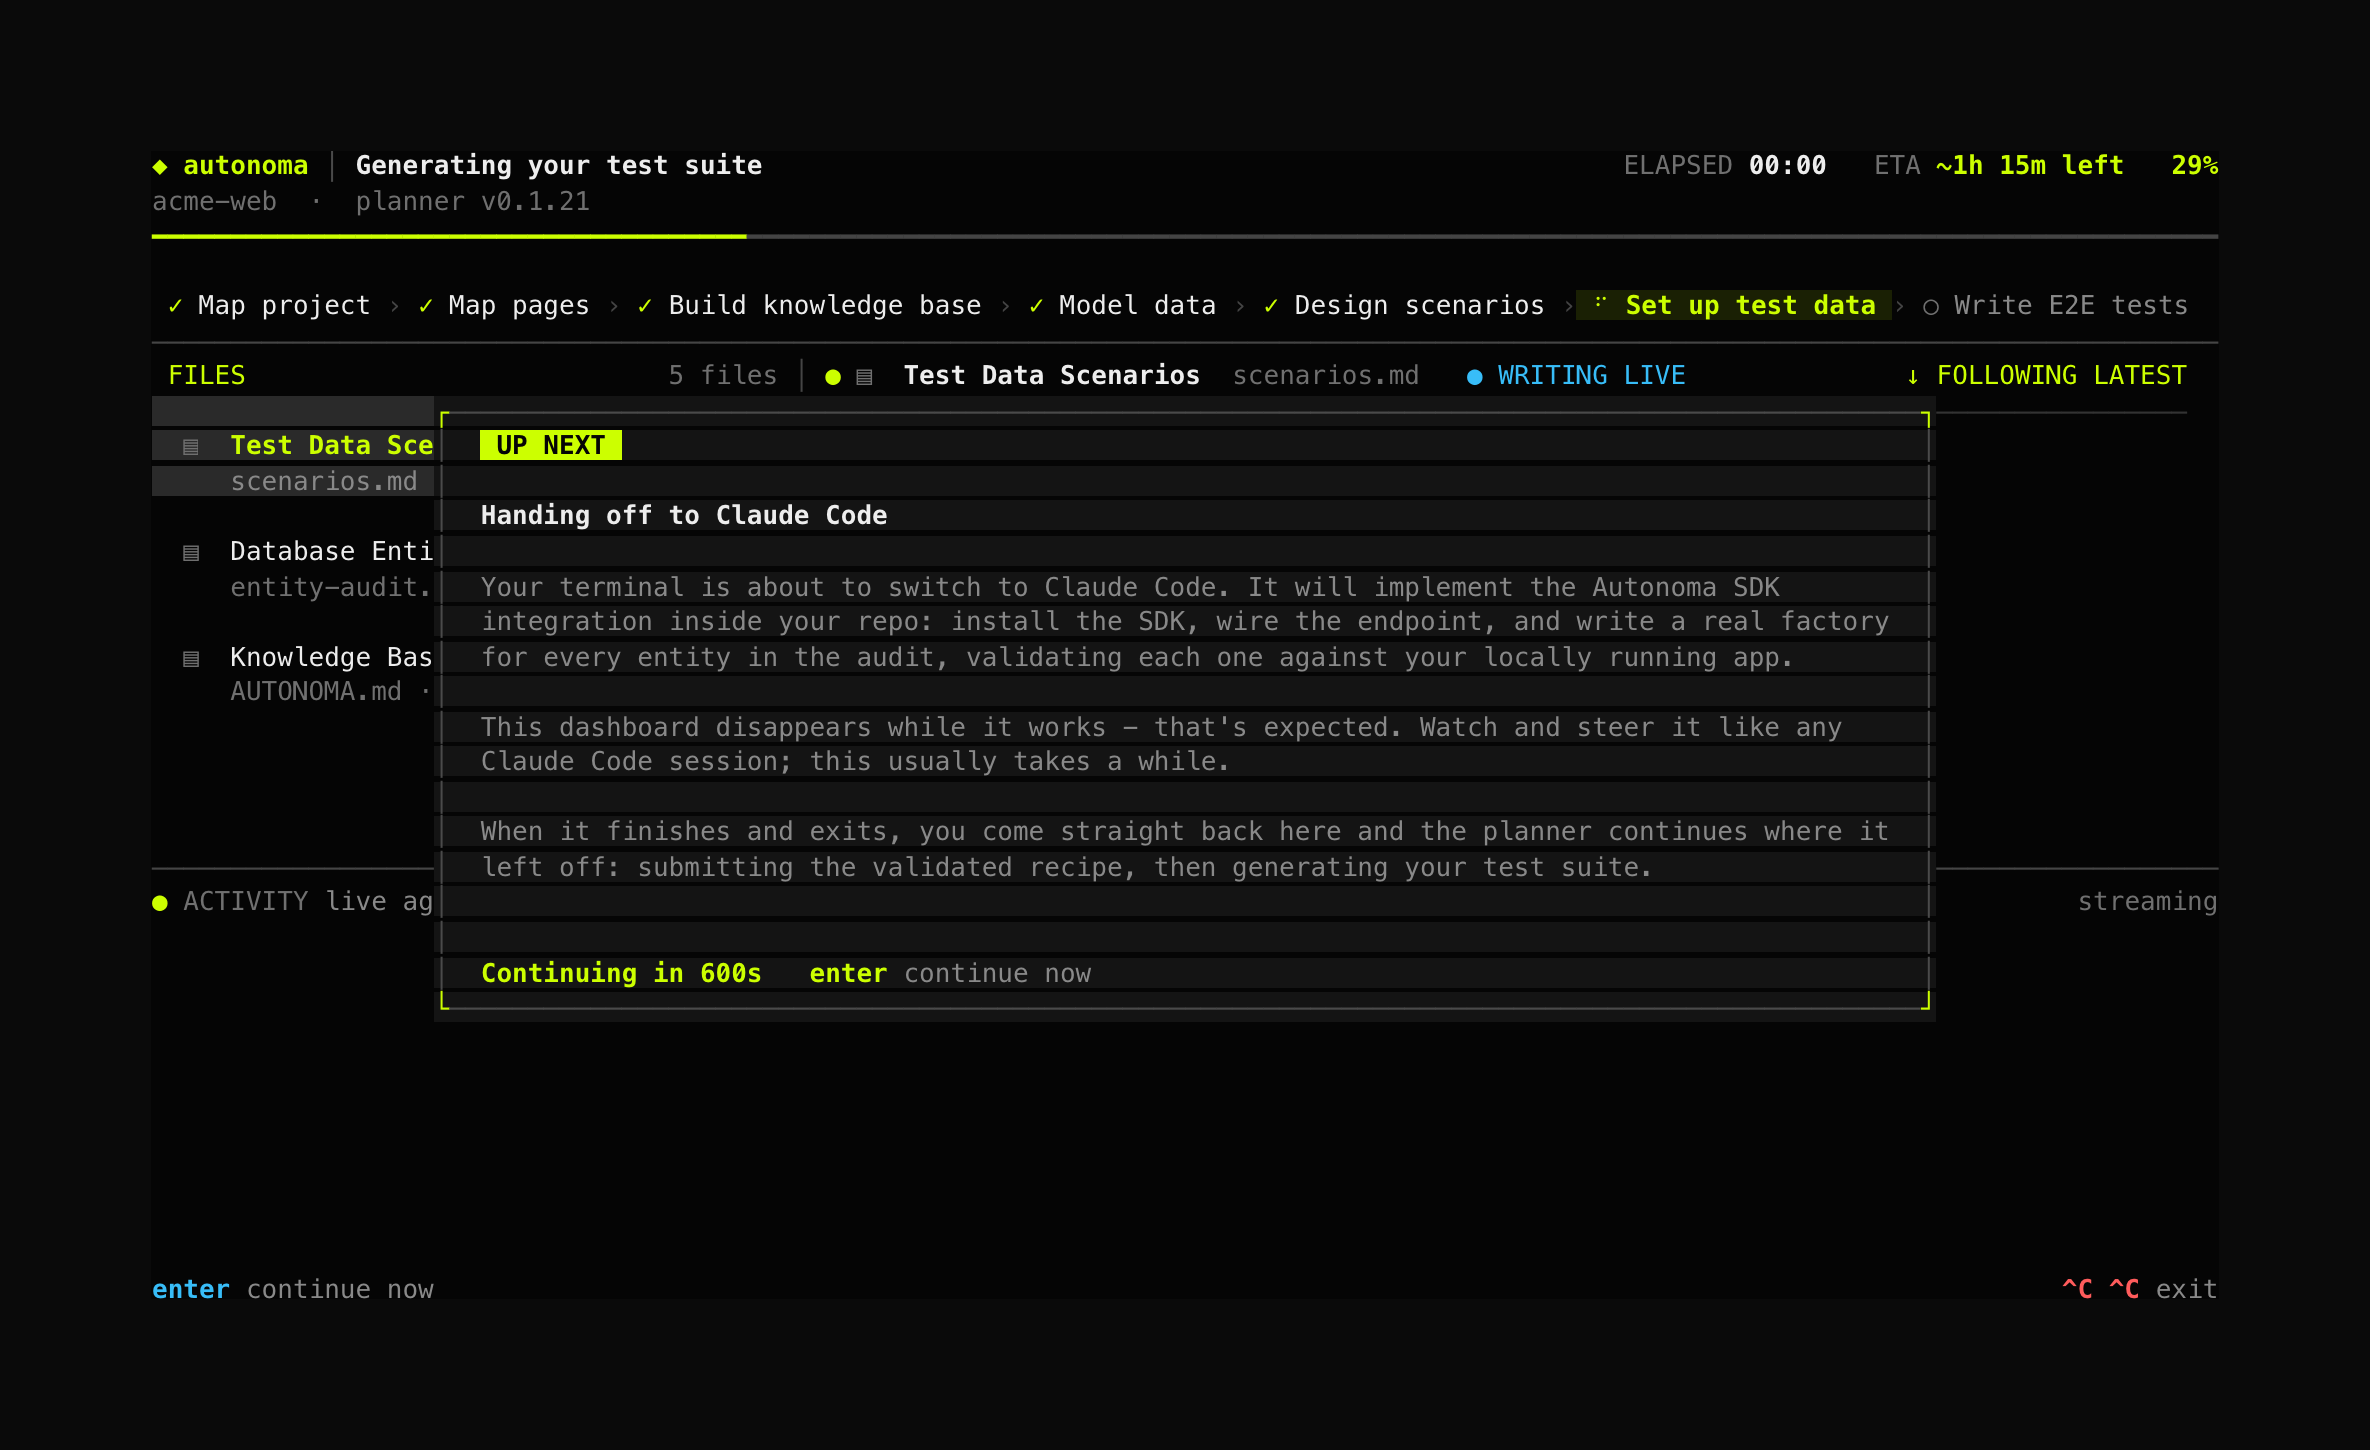
The dashboard warns you before it steps aside, and you can skip the countdown with `enter`.
By default the session is fully autonomous; pass `--permission-mode` to make it ask before edits or commands instead. If no supported agent is installed (or you decline), the planner writes the full instructions to `~/.autonoma//integration-prompt.md` so you can implement them with any assistant, then continue with `--resume`.
## Reviewing the output
Everything the planner produces streams into the dashboard’s file list the moment it’s written - open any file and read it while the run continues. If a step fails, the planner stops and asks whether to retry, retry with a steering note, or stop; progress is saved either way.
## Commands and flags
You run the planner through `npx`, which does **not** install anything on your `PATH`. Every command below therefore keeps the full `npx @autonoma-ai/planner@latest` prefix - a bare `autonoma-planner` will give you `command not found` unless you installed it globally yourself.
The subcommand comes first, before any flags.
```bash
# Run the pipeline. This is the command the dashboard gives you, with your tokens filled in.
AUTONOMA_SHARED_SECRET= AUTONOMA_DISTINCT_ID= AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= \
npx @autonoma-ai/planner@latest
# Show how far the last run got. Local only - reads the saved progress file, no network.
npx @autonoma-ai/planner@latest status
# Re-send everything already generated on disk. Idempotent, and the fix when a run
# finished but an artifact did not arrive. Needs the same env vars as the run.
AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= \
npx @autonoma-ai/planner@latest upload
```
> **--resume:**
>
> `--resume` continues from the first step that is not finished. If every step finished and only the upload failed, there is nothing left to resume - it prints `All steps complete.` and exits without uploading anything.
>
> Use `upload` to recover from that. It reads what is already on disk and re-sends it.
Flags go after the subcommand. `--help` prints all of this, plus what each step does:
```bash
--project # target a repo other than the current directory
--frontend # in a monorepo, the frontend directory to plan tests for
--backend # a backend/data layer it talks to. Repeatable, or comma-separated
--non-interactive # run unattended - see below
--coding-agent # which agent handles the preview and SDK steps: claude | codex
--permission-mode # its autonomy: bypassPermissions (default) | acceptEdits | default
--resume # continue from where a previous run stopped
--fresh # discard a previous run's output and start over
--step # run a single step and stop - for debugging one step, not for sequencing a run
--model # pick a different Autonoma-hosted model (still no key needed)
--slug # override the output folder name under ~/.autonoma/
--help # every action this can take
```
`--agent` and `--backends` are accepted as aliases of `--coding-agent` and `--backend`.
## Running unattended
Hand the same command to a hosted agent, an autonomous engineer, or a CI job and add `--non-interactive`. It runs the entire pipeline in **one invocation** - there is no step list to sequence, and nothing to call back into:
```bash
AUTONOMA_API_TOKEN= AUTONOMA_GENERATION_ID= AUTONOMA_APPLICATION_ID= \
npx @autonoma-ai/planner@latest --non-interactive \
--coding-agent claude --frontend apps/web --backend apps/api
```
With nobody to answer a question, everything that would have been asked has to arrive as a flag. What the run does about that:
* **It never opens a browser.** The coding agent’s Autonoma connection is authorized with the `AUTONOMA_API_TOKEN` the run already holds, sent as a bearer header. There is no sign-in step to complete.
* **It never blocks on a question.** Where it has to assume an answer it says so on stdout, naming what was asked and what it took.
* **It reports each step as it starts and finishes**, with how long it took, so the process that launched it can follow along.
* **It refuses rather than guesses** when a wrong guess would spend the run on the wrong thing - several frontends and no `--frontend` plans a test suite for an app you did not mean, so it fails with a clear error instead.
* **It chooses, and says so, where the choice is cheap.** Two coding agents installed and no `--coding-agent` picks the first and names it in a warning. Refusing there would skip the preview environment entirely and leave every later step planning against an app with nowhere to deploy - far worse than running the other agent. Pass `--coding-agent` to decide it yourself.
The coding agent it starts runs headless too (`claude -p`, `codex exec`), fully autonomous by default. Claude Code is started on Opus, for its own session and for any subagent it spawns - these steps install the SDK and validate it against a live app, and a weaker model there fails in ways that read as your app being broken.
> **Note:**
>
> The run sets an environment variable when it spawns a coding agent, and refuses to spawn another while that variable is set. Without it, an agent that runs the planner would have the planner spawn an agent, which would run the planner - so a nested invocation stops rather than recursing.
## Output
Artifacts are written to `~/.autonoma//` as they’re produced. When you run the planner from the onboarding flow’s upload step, the knowledge base, scenarios, recipe, and generated tests are uploaded to Autonoma automatically at the end - ready to run against your preview environments.
> **Note:**
>
> The planner and the [Environment Factory](/environment-factory/) work together: the planner **designs** the scenarios and generates the tests; the Environment Factory **provisions** the real, isolated data those tests run against, on every run.
# Environment Factory
> The Environment Factory is one endpoint in your backend that creates isolated test data before each test run and deletes it after - by reusing the real functions your app already uses to create that data.
# Setup Guide
> Install the Autonoma SDK, create the Environment Factory endpoint, register factories, and wire up authentication - from an empty backend to a validated, production-ready endpoint.
This guide takes you from nothing to a working Environment Factory endpoint at `/api/autonoma`. Plan for anywhere from 30 minutes to a couple of hours, depending on how many models your app has.
> **You may not need to do this by hand:**
>
> The [test planner](/test-planner/)’s “Set up test data” step hands this whole integration to your locally installed coding agent: it installs the SDK, writes the endpoint, registers factories that call your real creation code, validates the full up/down cycle against your running app, and opens a pull request for you to review.
>
> Doing it yourself is fully supported, and this guide is also how you understand what the agent built. But if you have not run the planner yet, start there.
You’ll do eight things:
1. [Install the SDK](#1-install-the-sdk) in your existing backend
2. [Pick your scope field](#2-pick-your-scope-field)
3. [Generate two secrets](#3-generate-two-secrets)
4. [Create the endpoint](#4-create-the-endpoint)
5. [Register factories](#5-register-factories)
6. [Implement the auth callback](#6-implement-the-auth-callback)
7. [Validate](#7-validate)
8. [Go live](#8-go-live)
## 1. Install the SDK
The endpoint lives **inside your existing backend**, next to your other routes. It is not a separate server, sidecar, or standalone process.
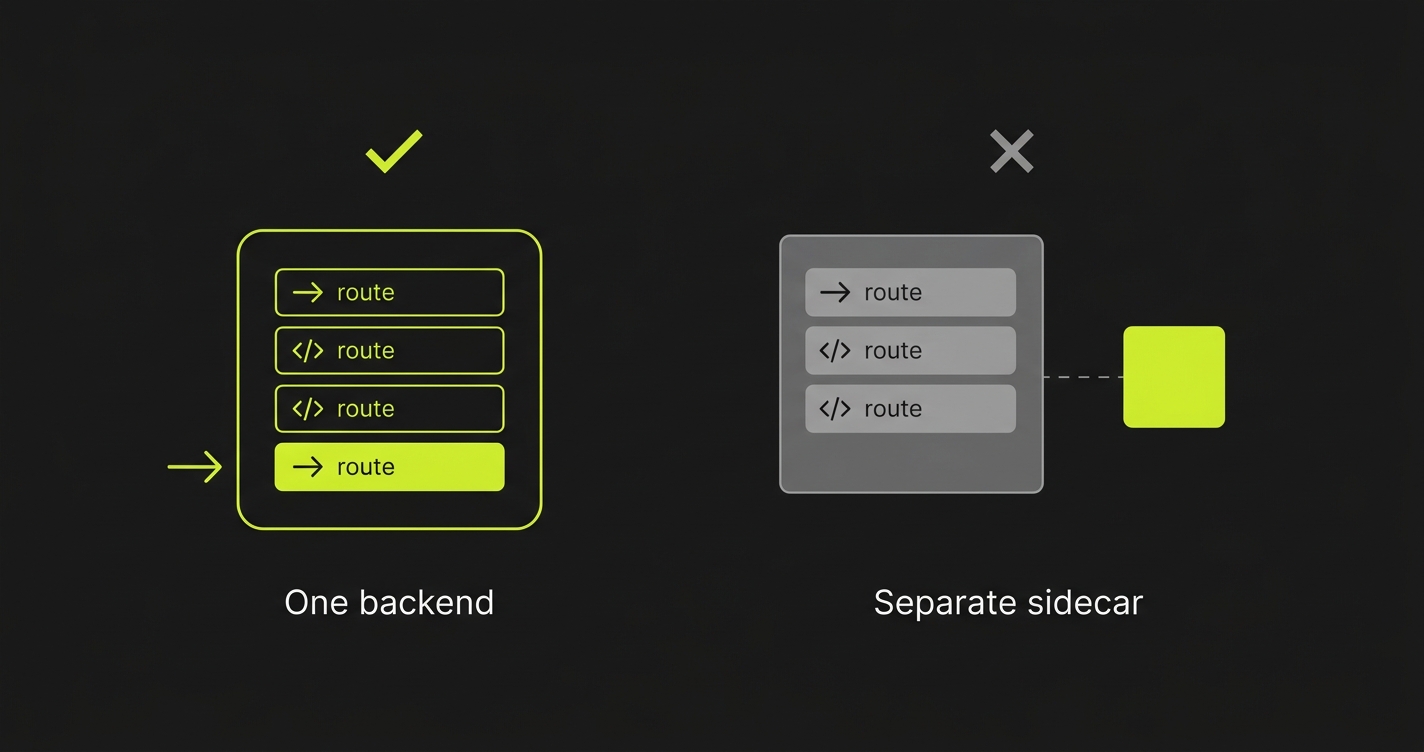
Pick the SDK in the **same language as your backend** - running a Python sidecar next to a Node app means your test data skips the real auth, hashing, and hooks that ship in production.
Add the core SDK plus the adapter for your framework:
```bash
# Next.js App Router, Bun, Deno (Web-standard Request/Response)
pnpm add @autonoma-ai/sdk @autonoma-ai/server-web zod
# Express / Fastify
pnpm add @autonoma-ai/sdk @autonoma-ai/server-express zod
# Hono
pnpm add @autonoma-ai/sdk @autonoma-ai/server-hono zod
# Node.js http
pnpm add @autonoma-ai/sdk @autonoma-ai/server-node zod
```
| Framework | Adapter package | Handler export |
| ------------------ | ----------------------------- | ---------------------- |
| Next.js, Bun, Deno | `@autonoma-ai/server-web` | `createHandler` |
| Express, Fastify | `@autonoma-ai/server-express` | `createExpressHandler` |
| Hono | `@autonoma-ai/server-hono` | `createHonoHandler` |
| Node.js `http` | `@autonoma-ai/server-node` | `createNodeHandler` |
One distribution covers the core SDK and every adapter (`autonoma_fastapi`, `autonoma_flask`, `autonoma_django`). Install it with the extra for your framework so its dependency is pulled in:
```bash
pip install "autonoma-ai[fastapi]" # or [flask], [django]
```
| Framework | Handler export |
| --------- | ------------------------ |
| FastAPI | `create_fastapi_handler` |
| Flask | `create_flask_handler` |
| Django | `create_django_handler` |
| Your backend | SDK package |
| ------------ | ------------------------------- |
| Go | `github.com/autonoma-ai/sdk-go` |
| Rust | `autonoma-sdk` crate |
| Java | `ai.autonoma:autonoma-sdk` |
| Ruby | `autonoma-ai` gem |
| PHP | `autonoma-ai/sdk` |
| Elixir | `autonoma` hex package |
See [Examples](/environment-factory/examples/) for a complete, runnable endpoint in each of these.
> **Note:**
>
> No SDK for your language? Open an issue - don’t spin up a polyglot sidecar to reach one that exists.
## 2. Pick your scope field
Choose the field most of your models use to reference the root tenant - usually `organizationId`, `orgId`, `tenantId`, or `workspaceId`.
The SDK doesn’t introspect foreign keys to find this. It just declares the field in the `discover` response so the dashboard knows how to scope test data. Your factories still own every write, including the tenant column.
## 3. Generate two secrets
You need two **different** secrets. The SDK throws an error at startup if they match.
```bash
openssl rand -hex 32 # AUTONOMA_SHARED_SECRET - shared with Autonoma
openssl rand -hex 32 # AUTONOMA_SIGNING_SECRET - kept private, never shared
```
```bash
AUTONOMA_SHARED_SECRET=abc123...
AUTONOMA_SIGNING_SECRET=def456...
```
The **shared secret** signs every request between Autonoma and your endpoint. The **signing secret** signs the teardown token and never leaves your server. See [Security](/environment-factory/security/) for what each one protects.
## 4. Create the endpoint
Mount the handler at the conventional path `/api/autonoma`.
app/api/autonoma/route.ts
```typescript
import { createHandler } from '@autonoma-ai/server-web'
export const POST = createHandler({
scopeField: 'organizationId',
sharedSecret: process.env.AUTONOMA_SHARED_SECRET!,
signingSecret: process.env.AUTONOMA_SIGNING_SECRET!,
factories: { /* step 5 */ },
auth: async (user) => { /* step 6 */ },
})
```
routes/autonoma.ts
```typescript
import { createExpressHandler } from '@autonoma-ai/server-express'
app.post('/api/autonoma', createExpressHandler({
scopeField: 'organizationId',
sharedSecret: process.env.AUTONOMA_SHARED_SECRET!,
signingSecret: process.env.AUTONOMA_SIGNING_SECRET!,
factories: { /* step 5 */ },
auth: async (user) => { /* step 6 */ },
}))
```
src/routes/autonoma.ts
```typescript
import { createHonoHandler } from '@autonoma-ai/server-hono'
app.post('/api/autonoma', createHonoHandler({
scopeField: 'organizationId',
sharedSecret: process.env.AUTONOMA_SHARED_SECRET!,
signingSecret: process.env.AUTONOMA_SIGNING_SECRET!,
factories: { /* step 5 */ },
auth: async (user) => { /* step 6 */ },
}))
```
autonoma\_handler.py
```python
import os
from autonoma.types import HandlerConfig
from autonoma_fastapi import create_fastapi_handler
config = HandlerConfig(
scope_field='organization_id',
shared_secret=os.environ['AUTONOMA_SHARED_SECRET'],
signing_secret=os.environ['AUTONOMA_SIGNING_SECRET'],
factories={ ... }, # step 5
auth=lambda user, ctx: { ... }, # step 6
)
router = create_fastapi_handler(config)
app.include_router(router, prefix='/api/autonoma')
```
Using another framework? Find a complete, runnable endpoint for your stack in [Examples](/environment-factory/examples/).
## 5. Register factories
Register one **factory** per model the dashboard can create. Each factory’s input schema (Zod in TypeScript, Pydantic in Python) drives both the `discover` schema and the validation of incoming data.
```typescript
import { z } from 'zod'
import { defineFactory } from '@autonoma-ai/sdk'
factories: {
Organization: defineFactory({
inputSchema: z.object({ name: z.string(), slug: z.string() }),
refSchema: z.object({ id: z.string(), name: z.string(), slug: z.string() }),
// `data` is typed from inputSchema - no z.infer needed
create: async (data) => organizationService.create(data),
// `record` is typed from refSchema
teardown: async (record) => organizationService.delete(record.id),
}),
User: defineFactory({
inputSchema: z.object({ email: z.string(), name: z.string() }),
create: async (data) =>
userService.create({ ...data, password: 'test-password-123' }),
// no teardown: this model is left alone on `down`
}),
}
```
Always call your real service or repository from `create` - the same function production uses. That’s what keeps test data honest.
This is the heart of the Environment Factory. Once your first two factories work, read [Factories & the create payload](/environment-factory/factories/) to learn how records link together with `_alias` / `_ref` and how to tear down dependent rows.
## 6. Implement the auth callback
The `auth` callback receives the first `User` created during `up` and must return **real, working credentials** the test runner can log in with.
```typescript
auth: async (user) => {
// user can be null - not every scenario creates a User
const session = await createSession(user!.id)
return {
cookies: [{ name: 'session', value: session.token, httpOnly: true, sameSite: 'lax', path: '/' }],
}
}
```
> **Caution:**
>
> If the auth callback returns a fake or expired token, **every test fails at the login step**. This is the single most common setup mistake.
There are three patterns - session cookies, bearer tokens, and login credentials. See [Authentication](/environment-factory/authentication/) for all three.
## 7. Validate
Before you write a single test, prove that `up` creates the right data and `down` removes all of it.
**Smoke-test `discover` with curl:**
```bash
SECRET="your-shared-secret"
BODY='{"action":"discover"}'
SIG=$(echo -n "$BODY" | openssl dgst -sha256 -hmac "$SECRET" | sed 's/.*= //')
curl -s -X POST http://localhost:3000/api/autonoma \
-H "Content-Type: application/json" \
-H "x-signature: $SIG" \
-d "$BODY" | jq .
```
You should get back your schema - every registered model and its fields, plus `scopeField`.
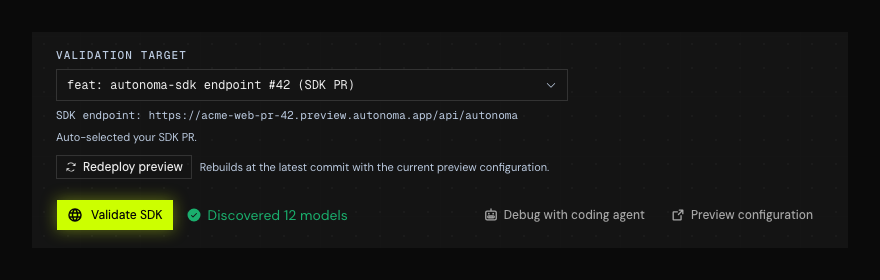
In the dashboard the same check reports back as a model count. That count is the whole confirmation - there is no screen that lists the discovered models or their fields, so use the `curl` above when you want to read the schema itself.
**Run the full lifecycle with `checkScenario`:**
```typescript
import { checkScenario } from '@autonoma-ai/sdk'
const result = await checkScenario(
factories,
{
create: {
Organization: [{ _alias: 'org', name: 'Test Org', slug: 'test-org' }],
User: [{ name: 'Admin', email: 'admin@test.com', organizationId: { _ref: 'org' } }],
},
},
{ scopeField: 'organizationId' },
)
// result.valid - true if up + down both succeeded
// result.phase - 'ok' | 'up' | 'down' (where it failed)
// result.errors - [{ phase, message, fix? }]
```
Then confirm three things by hand:
1. **After `up`** - the expected records exist with the right values.
2. **After `down`** - every created record is gone, no orphans.
3. **Auth works** - the returned cookies or headers authenticate a real request.
## 8. Go live
**Nothing to switch on.** The endpoint is always enabled - HMAC signing is the gate, so it serves nothing without the shared secret. On Autonoma preview environments (`AUTONOMA_PREVIEWKIT` is set in every preview) that’s the whole story: previews are isolated and never production. If you deploy the factory in your own environments, add the production guard yourself - mount the route only outside production:
```typescript
if (process.env.NODE_ENV !== 'production') {
app.post('/api/autonoma', createHandler({ ... }))
}
```
See [Security & Troubleshooting](/environment-factory/security/) for the full three-layer model.
**Connect to Autonoma.** Deploy your endpoint and set the same `AUTONOMA_SHARED_SECRET` in your deployment secrets. Autonoma then calls `discover` to learn your schema, generates scenario data, and sends `up` / `down` around every test run.
> **Tip:**
>
> Prefer to iterate on a branch? Open a `feat: autonoma-sdk` pull request - Autonoma auto-detects it and lets you validate against that PR’s preview environment from the SDK step, so you never push straight to `main`.
# Factories & the Create Payload
> How to register factories, link records with _alias and _ref, and tear down dependent rows. The factory is the only way the SDK writes data - there is no raw-SQL fallback.
A **factory** is a small function that knows how to create - and optionally delete - one model. The SDK writes data *only* through the factories you register. There is no SQL introspection and no raw-SQL fallback.
## Anatomy of a factory
```typescript
import { z } from 'zod'
import { defineFactory } from '@autonoma-ai/sdk'
Organization: defineFactory({
// 1. Drives the discover schema and validates incoming data
inputSchema: z.object({ name: z.string(), slug: z.string() }),
// 2. Optional: validates the record on teardown and types `record`
refSchema: z.object({ id: z.string(), name: z.string(), slug: z.string() }),
// 3. Called during `up`. `data` is typed from inputSchema.
create: async (data) => organizationService.create(data),
// 4. Called during `down`. `record` is typed from refSchema.
teardown: async (record) => organizationService.delete(record.id),
})
```
The generics are inferred from the schemas, so you never write `z.infer<...>`:
* `data` in `create` is the parsed `inputSchema`.
* `record` in `teardown` is the parsed `refSchema` (or `Record & { id }` if you omit `refSchema`).
* `create` must return an object with an **`id` field** (e.g. `{ id: "..." }`). This is what `down` uses to delete the record and what other factories reference. If your service returns a differently-named key, map it in the factory: `create: async (data) => { const u = await userService.create(data); return { id: u.userId } }`. Everything else you return is stored in refs and passed to later factories. A factory that returns no `id` fails with `FACTORY_MISSING_PK`.
## Always call your real code
Register a factory for **every** model the dashboard can create. Point `create` at the function your app already uses:
| What your code has | What `create` should do |
| ---------------------------------------------------------------------- | --------------------------------------------------------- |
| A `create` / `insert` / `register` function in a service or repository | Call that function |
| That function also hashes passwords, generates slugs, syncs to Stripe… | Call it anyway - your factory inherits the logic for free |
| Only inline ORM calls scattered across route handlers | Make the same ORM call directly in `create` |
| A seed-only lookup table that’s never created at runtime | Omit it, or write a factory that re-creates the seed row |
Even if `ProjectService.create()` today just wraps `prisma.project.create()`, wire it up. The day it gains a side effect, your tests keep working with zero rewiring.
## Linking records with `_alias` and `_ref`
The `create` field in an `up` request is a **flat map keyed by model name**. Each value is the array of records to create. Records point at each other with two reserved keys:
* `_alias` - a unique name you give a record so others can reference it.
* `_ref` - `{ "_ref": "alias" }` resolves to the real `id` of the aliased record once it exists.
```json
{
"create": {
"Organization": [{ "_alias": "acme", "name": "Acme Corp", "slug": "acme-corp" }],
"Application": [{
"_alias": "webApp",
"name": "Marketing Website",
"organizationId": { "_ref": "acme" }
}],
"Test": [{
"name": "Homepage Test",
"applicationId": { "_ref": "webApp" }
}]
}
}
```
Set **every foreign key explicitly** on the record that owns it, using `_ref`. This includes the scope/tenant field - the SDK never injects it for you.
### How the SDK resolves the graph
From that `_alias` / `_ref` graph, the SDK builds a dependency tree and sorts it so a referenced record is always created before the records that point at it:
1. Walk every record, collecting each `_alias` and every `_ref`.
2. Topologically sort so parents come before children - regardless of key order.
3. Validate each record through its `inputSchema`, then call `create`.
4. Replace every `{ "_ref": "alias" }` with the real id before the factory runs - your factory never sees a placeholder.
On `down`, factories with a `teardown` run in **reverse** order.
Rules worth remembering:
* `_alias` must be unique across the whole payload.
* Every alias a `_ref` points at must be declared **in the same payload** - the SDK never looks it up in the database.
* A `_ref` can appear anywhere in a record: a top-level FK, a nested JSON blob, an array element. The SDK finds it.
* Models are created **only** when they appear as a top-level key. A record array nested inside another record’s field is passed to the factory as opaque data, not created separately.
### What to include and omit
**Include:** required fields without defaults, every foreign key (via `_ref`), the scope field, and unique fields made unique per run (put the [`{{testRunId}}` or `{{testRunShortId}}` token](/reference/scenario-recipe-schema/#built-in-tokens) in emails and slugs).
**Omit:** `id`, fields with database defaults, auto-updated timestamps, and any row your factory mints transitively (see below).
## Dependents, cascades, and teardown
A single `create` often mints more than one row - a `WorkspaceService.create` might insert a workspace plus a default channel and an onboarding record in one transaction. The SDK doesn’t know about those extra rows, so you have to tell it how to clean them up. Four options, best first:
1. **Schema cascade.** If the foreign keys from every dependent back to the root are `onDelete: Cascade`, deleting the root is enough. Nothing to configure. This is usually the intent when one transaction mints everything.
2. **Call your app’s delete function.** If you already have a `WorkspaceService.delete` that removes the whole subtree, call it from `teardown`:
```typescript
Workspace: defineFactory({
inputSchema: WorkspaceInput,
create: async (data) => workspaceService.create(data),
teardown: async (record) => workspaceService.delete(record.id),
})
```
3. **Forward the dependent IDs `create` already returns.** If the production `create` returns the child IDs, surface them into refs and delete them in reverse FK order:
```typescript
Workspace: defineFactory({
inputSchema: WorkspaceInput,
create: async (data) => {
const { workspace, channel } = await workspaceService.create(data)
return { id: workspace.id, channelId: channel.id }
},
teardown: async (record) => {
await db.channel.delete({ where: { id: record.channelId } })
await db.workspace.delete({ where: { id: record.id } })
},
})
```
4. **None of the above - stop.** Don’t modify a production `create` just to return more IDs for the test harness. Instead, add a cascade to the schema, add a delete function to the service, or accept orphans between runs (fine when the test database is reset periodically).
> **Note:**
>
> Pure dependent models still get a factory (a thin repository call) **unless** they’re minted transitively by a parent. If they are, leave them out of the payload and let the parent’s `teardown` clean them up.
## Factory context
Both `create` and `teardown` receive a context object. There is no SDK-managed database client - import the same client your app’s services already use.
```typescript
interface FactoryContext {
refs: Record[]> // everything created so far
scenarioName: string // kept for compatibility - holds the testRunId
testRunId: string
}
```
`scenarioName` does **not** carry the scenario’s name. The scenario name never crosses the wire - the `up` request is `{ action, create, testRunId }` - so the SDK fills the field with `testRunId` and keeps it only for backwards compatibility. Use `testRunId`, and do not branch on `scenarioName` expecting a value like `adminWithTwoProjects`.
> **Note:**
>
> This is the *factory* context. The [auth callback](/environment-factory/authentication/) receives a **different** context object (`scopeValue`, `refs`) - don’t reach for `testRunId` in `auth`, or `scopeValue` in a factory.
# Authentication
> The auth callback turns a created User into real, working credentials the test runner uses to log in. Covers session cookies, bearer tokens, and email/password credentials for mobile.
The `auth` callback is what lets the test runner log in as the user your `up` request created. It receives that user and returns credentials the runner authenticates with.
> **Caution:**
>
> This is the single most common place setups break. If `auth` returns a fake or expired token, **every test fails at the login step** - no matter how good your factories are.
## What the callback receives
```typescript
auth: async (user, context) => {
// user: the first User record from refs, or null if the scenario has no User.
// Always handle null. Shape: { id, name, email, ... }
// context:
// scopeValue - the detected scope value (e.g. organization id), or the testRunId fallback
// refs - all created records, keyed by model, for looking up related data
}
```
Not every scenario creates a `User`, so `user` can be `null`. Guard for it.
## What the callback returns
```typescript
interface AuthResult {
cookies?: Array<{
name: string
value: string
httpOnly?: boolean
sameSite?: 'strict' | 'lax' | 'none'
path?: string
domain?: string
secure?: boolean
maxAge?: number
}>
headers?: Record // custom headers, e.g. Authorization: Bearer ...
credentials?: Record // key/value pairs for a manual login flow
}
```
There is no top-level `token` field. Return a bearer token on `headers`; return login credentials on `credentials`.
## Pattern 1 - Session cookies
The default for most server-rendered web apps. Create a real session and return its cookie.
```typescript
auth: async (user) => {
const session = await lucia.createSession(user!.id, {})
const cookie = lucia.createSessionCookie(session.id)
return {
cookies: [{
name: cookie.name,
value: cookie.value,
httpOnly: true,
sameSite: 'lax',
path: '/',
}],
}
}
```
## Pattern 2 - Bearer token
For APIs and SPAs that authenticate with an `Authorization` header.
```typescript
auth: async (user) => {
const token = jwt.sign(
{ sub: user!.id, email: user!.email },
process.env.JWT_SECRET!,
{ expiresIn: '1h' },
)
return { headers: { Authorization: `Bearer ${token}` } }
}
```
## Pattern 3 - Email/password credentials
When the agent needs to log in through your app’s actual login screen instead of receiving a cookie or token, return credentials.
```typescript
auth: async (user) => ({
credentials: {
email: user!.email,
password: 'test-password-123',
},
})
```
For this to work, the `User` must be created with a **known password**. Hash it in the User factory during `create`:
```typescript
User: defineFactory({
inputSchema: z.object({ email: z.string(), name: z.string() }),
create: async (data) =>
userService.create({ ...data, password: 'test-password-123' }),
})
```
## Common mistakes
| Mistake | What happens | Fix |
| ------------------------------------ | ---------------------------------- | --------------------------------------------- |
| Returning a hardcoded `"test-token"` | Every test fails at login | Use your real session / JWT creation |
| No password set on the User | Email/password login fails | Hash a known password in the User factory |
| Token expires too quickly | Tests fail midway through | Set expiry to at least 1 hour |
| Wrong cookie name | The browser never sends the cookie | Check your app’s real cookie name in DevTools |
> **Note:**
>
> The one-hour expiry above is for the **login token you return here** (the session cookie or JWT). It has nothing to do with the Environment Factory’s internal teardown token, which the SDK signs and verifies itself - see [Security](/environment-factory/security/).
# Security & Troubleshooting
> The Environment Factory's two secrets, three security layers, and hard safety guarantees - plus a full reference of error codes and common fixes.
The endpoint creates and deletes data, so it’s protected by three independent layers and two separate secrets. This page also collects every error code and the fixes for the problems you’re most likely to hit.
## The two secrets
Two secrets with different jobs. They **must be different values**. The SDK does not check this at startup - it returns `SAME_SECRETS` (HTTP 500) on the first request that arrives, so a handler with matching secrets boots cleanly and fails on first use.
| Secret | Env variable | Who knows it | Purpose |
| ------------------ | ------------------------- | ---------------------------------------------- | ---------------------------------------------------------------- |
| **Shared secret** | `AUTONOMA_SHARED_SECRET` | You + Autonoma | HMAC-signs every request. Autonoma signs; your SDK verifies. |
| **Signing secret** | `AUTONOMA_SIGNING_SECRET` | You, and Autonoma when it manages your preview | Signs the teardown token during `up`, verifies it during `down`. |
```bash
openssl rand -hex 32 # AUTONOMA_SHARED_SECRET
openssl rand -hex 32 # AUTONOMA_SIGNING_SECRET (must differ)
```
> **Who generates these depends on where your app runs:**
>
> On an Autonoma-managed preview environment you do not generate either one. Autonoma mints both and injects them into your app, and they are rotatable under **Settings -> Secrets**. Both keys are reserved there - the dashboard rejects an attempt to set them yourself.
>
> Generate them by hand only when you host the endpoint somewhere Autonoma does not manage.
## The three layers
**Layer 1 - Production guard (yours).** Running on Autonoma preview environments (`AUTONOMA_PREVIEWKIT` is set in every preview)? Skip this layer entirely - previews are isolated, disposable, and never production. Deploying the factory in your own environments? Only mount the route outside production, with a condition you own:
```typescript
if (process.env.NODE_ENV !== 'production') {
app.post('/api/autonoma', createHandler({ ... }))
}
```
The SDK itself has no switch here - the guard is plain code in your app, so you can see exactly when the endpoint exists at all.
**Layer 2 - Request signing (HMAC-SHA256).** Every request carries an `x-signature` header: the HMAC-SHA256 of the raw body, keyed with the shared secret. The SDK verifies it automatically and rejects unsigned or tampered requests with `401`. Even someone who finds the URL gets nothing without the shared secret.
**Layer 3 - Signed refs token.** When `up` creates data, the SDK signs the created record IDs into a `refsToken` using the signing secret. On `down`, it verifies that token before deleting anything - so `down` can only ever delete what `up` actually created. Autonoma just stores the opaque string and passes it back; it cannot forge or modify it.
> **Upgrading from an older SDK?:**
>
> Older SDK versions had an `allowProduction` option that blocked the endpoint with `404 PRODUCTION_BLOCKED` unless set. The option is deprecated and ignored - current SDKs always serve signed requests, and the production guard is the conditional mount above. If your deployed version still returns `PRODUCTION_BLOCKED` (Autonoma previews build with `NODE_ENV=production`, which tripped older setups), upgrade the SDK or set `allowProduction: true` until you can.
| Attack | Why it fails |
| ------------------------------ | ---------------------------------------------------------------------------------------- |
| Fake refs with made-up IDs | No valid token → rejected |
| A real token with altered refs | Refs don’t match the token → rejected |
| A replayed token | Confined to the exact record IDs `up` signed into it - it can never delete anything else |
## What the SDK can and cannot do
* **`up` can only create.** It invokes the factories you registered, which call your own services. It cannot update, delete, drop, truncate, or run raw SQL outside your factory bodies.
* **`down` can only delete what `up` created**, verified by the signed token. It calls each factory’s `teardown` in reverse order.
* **The SDK never runs SQL itself.** It calls your factories; they use whatever client your app already has.
## Error codes
Every code the endpoint can return, with its fix:
| Code | HTTP | Meaning | Fix |
| --------------------- | ---- | ------------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `CONFIGURATION_ERROR` | 503 | The handler is running without `AUTONOMA_SHARED_SECRET` and `AUTONOMA_SIGNING_SECRET`. Not emitted by every SDK - the TypeScript one fails differently | Set both in the environment where your backend actually runs - setting them locally but not in the deployed service is the usual cause |
| `INVALID_SIGNATURE` | 401 | HMAC signature missing or doesn’t match | Make `AUTONOMA_SHARED_SECRET` match the value Autonoma uses for your app |
| `UNRESOLVED_TOKEN` | 400 | A `{{token}}` in the recipe’s `create` has no matching entry under `variables` | Declare the variable, or fix the typo. Only [`{{testRunId}}` and `{{testRunShortId}}`](/reference/scenario-recipe-schema/#built-in-tokens) are built in |
| `INVALID_BODY` | 400 | Body isn’t valid JSON, a required field is missing, or a `_ref` names an alias nothing declares | Match each record to its own top-level model key, supply every required field, and declare each alias with `_alias` in the same payload |
| `UNKNOWN_ACTION` | 400 | `action` isn’t `discover`, `up`, or `down` | Check the request is one of the three actions |
| `UNKNOWN_ENVIRONMENT` | 400 | The requested environment name does not exist | Use a scenario name your recipe actually declares |
| `INVALID_REFS_TOKEN` | 403 | Refs token missing, malformed, or failed verification | Use the same `AUTONOMA_SIGNING_SECRET` between `up` and `down` |
| `PRODUCTION_BLOCKED` | 404 | Older SDK versions only: the deprecated `allowProduction` option was not set | Upgrade the SDK (the endpoint is always enabled now), or set `allowProduction: true` until you can |
| `SAME_SECRETS` | 500 | `sharedSecret` and `signingSecret` are identical | Use two different `openssl rand -hex 32` values |
| `FACTORY_MISSING_PK` | 500 | A factory’s `create` didn’t return an id | Return at least `{ id: "..." }` from every `create` |
| `INTERNAL_ERROR` | 500 | Unexpected server error - **and** the code for a record that fails a factory’s `inputSchema`, surfacing as `Invalid input for ""` | Check the failing model’s schema against the values the recipe sends, then your factory bodies and server logs |
## Other common problems
These surface as database or validation failures rather than as a distinct code - a dry run reports them with the message your own handler produced.
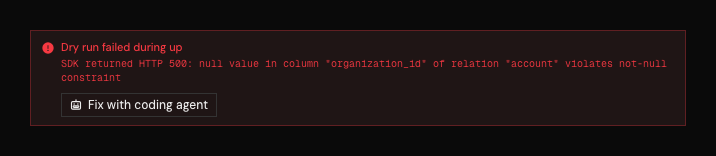
The message is passed straight through from your endpoint, so what you debug is your own stack trace, not a translation of it.
| Problem | Cause | Fix |
| ------------------------------------- | ---------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------- |
| FK violation on `up` | A required foreign key is missing | Set every FK (including the scope field) explicitly as a `{ "_ref": "alias" }` |
| `cycle detected in _alias/_ref graph` | Two records reference each other through `_alias` / `_ref` | Break the cycle - the SDK rejects it rather than resolving it. Create one record first and attach the second reference from inside a factory |
| Parallel tests collide | Same email/slug across runs | Put a [`{{testRunId}}` / `{{testRunShortId}}` token](/reference/scenario-recipe-schema/#built-in-tokens) in every unique field |
# Examples
> Working Environment Factory endpoints across 8 languages and 12 framework combinations - copy one for your stack.
Every example follows the same shape: install the SDK, configure the handler, register a factory for each model, and expose a single POST endpoint. Each factory carries an input schema (Pydantic in Python, Zod in TypeScript, and so on) so the SDK can describe the model to the dashboard and validate the create payload before invoking your code. There is no SQL introspection and no SQL fallback.
> **New here?:**
>
> Read the [Environment Factory overview](/environment-factory/) for the concepts and the [Setup guide](/environment-factory/setup/) for the step-by-step. These examples are the finished code.
## Available examples
All examples live in the [SDK repository](https://github.com/Autonoma-AI/sdk/tree/main/examples). Each one ships with a README covering prerequisites, quick start, project structure, and how it works.
| Language | Framework | Schema lib | Source |
| ------------------------------------------------------- | -------------------- | ----------------------- | ------------------------------------------------------------------------------------- |
| [TypeScript](/environment-factory/examples/typescript/) | Express | Zod | [express](https://github.com/Autonoma-AI/sdk/tree/main/examples/typescript/express) |
| [TypeScript](/environment-factory/examples/typescript/) | Next.js (App Router) | Zod | [nextjs](https://github.com/Autonoma-AI/sdk/tree/main/examples/typescript/nextjs) |
| [TypeScript](/environment-factory/examples/typescript/) | Hono | Zod | [hono](https://github.com/Autonoma-AI/sdk/tree/main/examples/typescript/hono) |
| [Python](/environment-factory/examples/python/) | FastAPI | Pydantic | [fastapi](https://github.com/Autonoma-AI/sdk/tree/main/examples/python/fastapi) |
| [Python](/environment-factory/examples/python/) | Flask | Pydantic | [flask](https://github.com/Autonoma-AI/sdk/tree/main/examples/python/flask) |
| [Python](/environment-factory/examples/python/) | Django | Pydantic | [django](https://github.com/Autonoma-AI/sdk/tree/main/examples/python/django) |
| [Elixir](/environment-factory/examples/elixir/) | Phoenix | Ecto schemas | [phoenix](https://github.com/Autonoma-AI/sdk/tree/main/examples/elixir/phoenix) |
| [Java](/environment-factory/examples/java/) | Spring Boot | Bean Validation | [spring-boot](https://github.com/Autonoma-AI/sdk/tree/main/examples/java/spring-boot) |
| [Ruby](/environment-factory/examples/ruby/) | Rails | dry-validation | [rails](https://github.com/Autonoma-AI/sdk/tree/main/examples/ruby/rails) |
| [Rust](/environment-factory/examples/rust/) | Axum | serde + validator | [axum](https://github.com/Autonoma-AI/sdk/tree/main/examples/rust/axum) |
| [Go](/environment-factory/examples/go/) | Gin | go-playground/validator | [gin](https://github.com/Autonoma-AI/sdk/tree/main/examples/go/gin) |
| [PHP](/environment-factory/examples/php/) | Laravel | Symfony Validator | [laravel](https://github.com/Autonoma-AI/sdk/tree/main/examples/php/laravel) |
## Configuration reference
Every example configures the same handler fields:
| Field | Description |
| --------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `scopeField` | The column that scopes all models to a tenant (e.g. `organizationId`). Declared in `discover` so the dashboard knows how to isolate test data. |
| `sharedSecret` | Shared between your server and Autonoma. Verifies incoming requests via HMAC-SHA256. Generate with `openssl rand -hex 32`. |
| `signingSecret` | Private to your server. Signs the refs token so teardown can only delete what was created. Generate with `openssl rand -hex 32`, and make it different from `sharedSecret`. |
| `factories` | One factory per model. Each declares an `inputSchema` / `input_model` plus a `create` that calls your real service, and an optional `teardown`. |
| `auth` | Called during `up` with the created user. Returns credentials (cookies, headers, or credentials) so Autonoma can act as the test user. |
For what each field does in depth, see [Factories & the create payload](/environment-factory/factories/), [Authentication](/environment-factory/authentication/), and [Security](/environment-factory/security/).
# TypeScript
> Autonoma Environment Factory examples with Express, Hono, and Next.js.
The TypeScript SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s Zod `inputSchema`. There is no database introspection, no ORM executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
`zod` is a peer dependency: `npm install zod` (any v3.23+ or v4 release works).
## Express
Uses `createExpressHandler` from `@autonoma-ai/server-express`. The factories use whatever Prisma / Drizzle / pg client your app already has - the SDK does not need a connection.
src/index.ts
```typescript
import express from 'express'
import { z } from 'zod'
import { defineFactory } from '@autonoma-ai/sdk'
import { createExpressHandler } from '@autonoma-ai/server-express'
import { PrismaClient } from '@prisma/client'
import { OrganizationRepository } from './repositories/organization'
import { UserRepository } from './repositories/user'
const prisma = new PrismaClient()
const organizationRepo = new OrganizationRepository(prisma)
const userRepo = new UserRepository(prisma)
const OrganizationInput = z.object({ name: z.string() })
const UserInput = z.object({
email: z.string(),
name: z.string(),
organizationId: z.string(),
})
const app = express()
app.use(express.json())
app.post(
'/api/autonoma',
createExpressHandler({
// The column that scopes all models to a tenant
scopeField: 'organizationId',
// Shared with Autonoma - verifies incoming requests via HMAC-SHA256
sharedSecret: process.env.AUTONOMA_SHARED_SECRET!,
// Private to your server - signs the refs token so teardown only deletes what was created
signingSecret: process.env.AUTONOMA_SIGNING_SECRET!,
// Every model the dashboard can create needs a factory.
// `defineFactory` infers `data`'s type from `inputSchema` - no z.infer<...> needed.
factories: {
Organization: defineFactory({
inputSchema: OrganizationInput,
create: async (data) => organizationRepo.create({ name: data.name }),
teardown: async (record) =>
organizationRepo.delete(record.id as string),
}),
User: defineFactory({
inputSchema: UserInput,
create: async (data) =>
userRepo.create({
email: data.email,
name: data.name,
organizationId: data.organizationId,
}),
}),
},
// Called after `up` - returns credentials so Autonoma can make authenticated requests
auth: async (user) => ({ headers: { Authorization: 'Bearer REPLACE_WITH_A_REAL_TOKEN' } }),
}),
)
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/typescript/express)
***
## Next.js (App Router)
`createHandler` from `@autonoma-ai/server-web` works with any Web-standard runtime: Next.js App Router, Hono, Bun, Deno.
src/app/api/autonoma/route.ts
```typescript
import { z } from 'zod'
import { defineFactory } from '@autonoma-ai/sdk'
import { createHandler } from '@autonoma-ai/server-web'
import { db } from '@/db'
import { OrganizationRepository } from '@/repositories/organization'
import { UserRepository } from '@/repositories/user'
const organizationRepo = new OrganizationRepository(db)
const userRepo = new UserRepository(db)
const OrganizationInput = z.object({ name: z.string() })
const UserInput = z.object({
email: z.string(),
name: z.string(),
organizationId: z.string(),
})
export const POST = createHandler({
scopeField: 'organizationId',
sharedSecret: process.env.AUTONOMA_SHARED_SECRET!,
signingSecret: process.env.AUTONOMA_SIGNING_SECRET!,
factories: {
Organization: defineFactory({
inputSchema: OrganizationInput,
create: async (data) => organizationRepo.create({ name: data.name }),
teardown: async (record) =>
organizationRepo.delete(record.id as string),
}),
User: defineFactory({
inputSchema: UserInput,
create: async (data) =>
userRepo.create({
email: data.email,
name: data.name,
organizationId: data.organizationId,
}),
}),
},
auth: async () => ({ headers: { Authorization: 'Bearer REPLACE_WITH_A_REAL_TOKEN' } }),
})
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/typescript/nextjs)
***
## Hono
Same factories, the `createHonoHandler` adapter unwraps a Hono `Context` into the Web-standard request the SDK expects.
```typescript
import { Hono } from 'hono'
import { createHonoHandler } from '@autonoma-ai/server-hono'
const app = new Hono()
app.post('/api/autonoma', createHonoHandler({ /* same config as above */ }))
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/typescript/hono)
***
## What `inputSchema` does
The Zod schema you pass as `inputSchema`:
1. **Drives discover** - the SDK walks the schema’s shape to describe the model to the dashboard (field names, types, required/optional, defaults). No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK calls `inputSchema.safeParse(payload)` and passes the parsed value in. Validation failures bubble up as a 500 with the field path the dashboard can show inline.
3. **Drives types** - `defineFactory` is generic over the schemas you pass. `data` inside `create` is automatically typed as `z.infer` and `record` inside `teardown` is automatically typed as `z.infer` when you set one. No `z.infer<...>` annotations at the call site.
4. **Lets you accept extras** - recipes can carry display-only metadata (e.g. `_alias`) without failing validation; Zod ignores keys that aren’t part of your schema by default.
### Validated teardown with `refSchema`
Adding a `refSchema` lets `teardown` work against a typed record (validated through Zod first). When `refSchema` is set, `create`’s return type is constrained to its input shape - the same record flows from `create` → `down` token → `teardown` with no manual casts.
```typescript
const ProjectInput = z.object({ name: z.string(), organizationId: z.string() })
const ProjectRef = z.object({ id: z.string(), name: z.string() })
defineFactory({
inputSchema: ProjectInput,
refSchema: ProjectRef,
// `data` typed as { name: string; organizationId: string }
create: async (data) => projectService.create(data),
// `record` typed as { id: string; name: string }
teardown: async (record) => projectService.delete(record.id),
})
```
Without `refSchema`, `create`’s return type widens to `Record & { id: string | number }` and `record` in `teardown` matches that shape - the existing factories above keep compiling.
# Python
> Autonoma Environment Factory examples with FastAPI, Flask, and Django.
The Python SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s Pydantic `input_model`. There is no database introspection, no ORM executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## FastAPI + SQLAlchemy
Uses `create_fastapi_handler` from `autonoma_fastapi`. The factories use whatever SQLAlchemy session your app already has - the SDK does not need a connection.
app.py
```python
import os
from pydantic import BaseModel, ConfigDict
from autonoma.types import HandlerConfig
from autonoma.factory import define_factory
from autonoma_fastapi import create_fastapi_handler
from database import session
from repositories.organization import OrganizationRepository
from repositories.user import UserRepository
organization_repo = OrganizationRepository(session)
user_repo = UserRepository(session)
class OrganizationInput(BaseModel):
model_config = ConfigDict(extra="ignore")
name: str
class UserInput(BaseModel):
model_config = ConfigDict(extra="ignore")
email: str
name: str
organization_id: str
config = HandlerConfig(
# The column that scopes all models to a tenant - used to isolate test data
scope_field="organization_id",
# Shared with Autonoma - verifies incoming requests via HMAC-SHA256
shared_secret=os.environ["AUTONOMA_SHARED_SECRET"],
# Private to your server - signs the refs token so teardown only deletes what was created
signing_secret=os.environ["AUTONOMA_SIGNING_SECRET"],
# Every model the dashboard can create needs a factory.
# The factory's input_model drives both validation and discover.
factories={
"Organization": define_factory(
create=lambda data, ctx: organization_repo.create({"name": data.name}),
teardown=lambda record, ctx: organization_repo.delete(record["id"]),
input_model=OrganizationInput,
),
"User": define_factory(
create=lambda data, ctx: user_repo.create({
"email": data.email,
"name": data.name,
"organization_id": data.organization_id,
}),
input_model=UserInput,
),
},
# Called after `up` - returns credentials so Autonoma can make authenticated requests
auth=lambda user, context: {"headers": {"Authorization": "Bearer REPLACE_WITH_A_REAL_TOKEN"}},
)
router = create_fastapi_handler(config)
app.include_router(router, prefix="/api/autonoma")
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/python/fastapi-sqlalchemy)
***
## Flask + SQLAlchemy
Same `HandlerConfig`, different server adapter. `create_flask_handler` returns a Flask Blueprint.
app.py
```python
from autonoma_flask import create_flask_handler
# Same HandlerConfig as FastAPI - scope_field, secrets, factories, auth.
# The only difference is the server adapter.
bp = create_flask_handler(config)
app.register_blueprint(bp, url_prefix="/api/autonoma")
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/python/flask-sqlalchemy)
***
## Django
`create_django_handler` returns a Django view function (already decorated with `@csrf_exempt` + `@require_POST`).
core/autonoma\_config.py
```python
import os
from pydantic import BaseModel, ConfigDict
from autonoma.types import HandlerConfig
from autonoma.factory import define_factory
from autonoma_django import create_django_handler
from core.repositories.organization import OrganizationRepository
from core.repositories.user import UserRepository
organization_repo = OrganizationRepository()
user_repo = UserRepository()
class OrganizationInput(BaseModel):
model_config = ConfigDict(extra="ignore")
name: str
class UserInput(BaseModel):
model_config = ConfigDict(extra="ignore")
email: str
name: str
organization_id: str
config = HandlerConfig(
scope_field="organization_id",
shared_secret=os.environ["AUTONOMA_SHARED_SECRET"],
signing_secret=os.environ["AUTONOMA_SIGNING_SECRET"],
factories={
"Organization": define_factory(
create=lambda data, ctx: organization_repo.create({"name": data.name}),
teardown=lambda record, ctx: organization_repo.delete(record["id"]),
input_model=OrganizationInput,
),
"User": define_factory(
create=lambda data, ctx: user_repo.create({
"email": data.email,
"name": data.name,
"organization_id": data.organization_id,
}),
input_model=UserInput,
),
},
auth=lambda user, context: {"headers": {"Authorization": "Bearer REPLACE_WITH_A_REAL_TOKEN"}},
)
handler = create_django_handler(config)
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/python/django)
***
## What `input_model` does
The Pydantic class you pass as `input_model`:
1. **Drives discover** - the SDK introspects `model_fields` to describe the model to the dashboard (field names, types, required/optional, defaults). No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK calls `input_model.model_validate(payload)` and passes the typed instance in. Your factory body works on a real Python object, not a `dict`.
3. **Lets you accept extras with `extra="ignore"`** - recipes can carry display-only metadata (e.g. `_alias`) without failing validation.
If you also want validated teardown, declare a `ref_model` (a Pydantic class describing the record returned by `create`) and the SDK will call `ref_model.model_validate(record)` before each `teardown` call.
# Elixir
> Autonoma Environment Factory example with Phoenix.
The Elixir SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s `input_fields`. There is no database introspection, no Ecto executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## Phoenix
Uses `Autonoma.Plug.Handler` as a Plug mounted via Phoenix’s `forward` macro. The factories use whatever Ecto Repo or service module your app already has - the SDK does not need a database connection.
lib/autonoma\_example/router.ex
```elixir
defmodule AutonomaExample.Router do
use Phoenix.Router
alias AutonomaExample.Repositories
@autonoma_config %{
# The column that scopes all models to a tenant - used to isolate test data
scope_field: "organization_id",
# Shared with Autonoma - verifies incoming requests via HMAC-SHA256
shared_secret: System.get_env("AUTONOMA_SHARED_SECRET") || "",
# Private to your server - signs the refs token so teardown only deletes what was created
signing_secret: System.get_env("AUTONOMA_SIGNING_SECRET") || "",
# Every model the dashboard can create needs a factory.
# The factory's input_fields drives both validation and discover.
factories: %{
"Organization" => Autonoma.Factory.define_factory(%{
input_fields: [
%{name: "name", type: "string", required: true}
],
create: fn data, _ctx -> Repositories.Organization.create(data) end,
teardown: fn record, _ctx -> Repositories.Organization.delete(record["id"]) end
}),
"User" => Autonoma.Factory.define_factory(%{
input_fields: [
%{name: "email", type: "string", required: true},
%{name: "name", type: "string", required: true},
%{name: "organization_id", type: "string", required: true}
],
create: fn data, _ctx -> Repositories.User.create(data) end
})
},
# Called after `up` - returns credentials so Autonoma can make authenticated requests
auth: fn _user, _context ->
%{"headers" => %{"Authorization" => "Bearer REPLACE_WITH_A_REAL_TOKEN"}}
end
}
forward "/api/autonoma", Autonoma.Plug.Handler, @autonoma_config
end
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/elixir/phoenix)
***
## What `input_fields` does
The field list you pass as `input_fields`:
1. **Drives discover** - the SDK uses the field definitions to describe the model to the dashboard (field names, types, required/optional). No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK checks that all required fields are present and strips unknown keys. Your factory body works on a clean map.
3. **Keeps it simple** - no external dependencies required. Use `"string"`, `"integer"`, `"number"`, `"boolean"`, `"timestamp"`, `"date"`, `"uuid"`, or `"json"` as the type.
# Java
> Autonoma Environment Factory example with Spring Boot.
The Java SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s `inputClass` (a Java class). There is no database introspection, no JDBC executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## Spring Boot
Uses `AutonomaController` from `ai.autonoma.spring`. Configured as a Spring `@Configuration` bean. The factories use whatever `JdbcTemplate`, JPA repository, or service layer your app already has - the SDK does not need a database connection.
AutonomaConfig.java
```java
@Configuration
public class AutonomaConfig {
public record OrganizationInput(String name) {}
public record UserInput(String email, String name, String organizationId) {}
@Bean
public AutonomaController autonomaController() {
OrganizationRepository organizationRepo = new OrganizationRepository(dataSource);
UserRepository userRepo = new UserRepository(dataSource);
HandlerConfig config = new HandlerConfig(
// The column that scopes all models to a tenant - used to isolate test data
"organization_id",
// Shared with Autonoma - verifies incoming requests via HMAC-SHA256
System.getenv("AUTONOMA_SHARED_SECRET"),
// Private to your server - signs the refs token so teardown only deletes what was created
System.getenv("AUTONOMA_SIGNING_SECRET"),
// Called after `up` - returns credentials so Autonoma can make authenticated requests
(user, context) -> AuthResult.ofHeaders(
Map.of("Authorization", "Bearer REPLACE_WITH_A_REAL_TOKEN")
)
);
// Every model the dashboard can create needs a factory.
// The factory's inputClass drives both validation and discover.
config.setFactories(Map.of(
"Organization", FactoryUtil.defineFactory(
(data, ctx) -> organizationRepo.create(data),
OrganizationInput.class,
(record, ctx) -> organizationRepo.delete((String) record.get("id"))
),
"User", FactoryUtil.defineFactory(
(data, ctx) -> userRepo.create(data),
UserInput.class
)
));
return new AutonomaController(config);
}
}
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/java/spring-boot)
***
## What `inputClass` does
The Java class you pass as the first argument to `defineFactory`:
1. **Drives discover** - the SDK uses reflection to walk the class’s declared fields and map Java types to the dashboard’s type system. No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK uses Jackson’s `ObjectMapper.convertValue` to deserialize the incoming map into an instance of your class. Type mismatches fail validation.
3. **Uses standard Java conventions** - field names come from Jackson `@JsonProperty` annotations (or the field name itself); Java types map to SDK types automatically (`String`→“string”, `int/long`→“integer”, `double`→“number”, `boolean`→“boolean”, `Instant`→“timestamp”, `UUID`→“uuid”).
# Ruby
> Autonoma Environment Factory example with Rails.
The Ruby SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s `input_fields`. There is no database introspection, no ActiveRecord executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## Rails
Uses `AutonomaRails::Handler` mixin in a standard Rails controller. The factories use whatever ActiveRecord models, service objects, or repositories your app already has - the SDK does not need a database connection.
app/controllers/autonoma\_controller.rb
```ruby
require "autonoma"
require "autonoma_rails"
class AutonomaController < ApplicationController
include AutonomaRails::Handler
def handle
autonoma_handle(autonoma_config)
end
private
def autonoma_config
@autonoma_config ||= Autonoma::HandlerConfig.new(
# The column that scopes all models to a tenant - used to isolate test data
scope_field: "organization_id",
# Shared with Autonoma - verifies incoming requests via HMAC-SHA256
shared_secret: ENV.fetch("AUTONOMA_SHARED_SECRET", ""),
# Private to your server - signs the refs token so teardown only deletes what was created
signing_secret: ENV.fetch("AUTONOMA_SIGNING_SECRET", ""),
# Every model the dashboard can create needs a factory.
# The factory's input_fields drives both validation and discover.
factories: {
"Organization" => Autonoma::Factory.define_factory(
input_fields: [
{ name: "name", type: "string", required: true }
],
create: ->(data, _ctx) { OrganizationRepository.create(data) },
teardown: ->(record, _ctx) { OrganizationRepository.delete(record["id"]) }
),
"User" => Autonoma::Factory.define_factory(
input_fields: [
{ name: "email", type: "string", required: true },
{ name: "name", type: "string", required: true },
{ name: "organization_id", type: "string", required: true }
],
create: ->(data, _ctx) { UserRepository.create(data) }
),
},
# Called after `up` - returns credentials so Autonoma can make authenticated requests
auth: ->(_user, _context) {
{ "headers" => { "Authorization" => "Bearer REPLACE_WITH_A_REAL_TOKEN" } }
}
)
end
end
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/ruby/rails)
***
## What `input_fields` does
The field definitions you pass as `input_fields`:
1. **Drives discover** - the SDK uses the field definitions to describe the model to the dashboard (field names, types, required/optional). No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK checks that all required fields are present and strips unknown keys. Your factory body works on a clean Hash.
3. **Keeps it simple** - no external gems required. Use `"string"`, `"integer"`, `"number"`, `"boolean"`, `"timestamp"`, `"date"`, `"uuid"`, or `"json"` as the type.
# Rust
> Autonoma Environment Factory example with Axum.
The Rust SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s `input_fields`. There is no database introspection, no SQLx executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## Axum
Uses `create_axum_handler` from `autonoma_sdk::axum`. Factories are registered in a `HashMap`. The factories use whatever SQLx pool, Diesel connection, or service layer your app already has - the SDK does not need a database connection.
src/main.rs
```rust
use autonoma_sdk::axum::create_axum_handler;
use autonoma_sdk::factory::{define_factory, define_factory_create_only};
use autonoma_sdk::types::{FactoryContext, FactoryRegistry, FieldDef, HandlerConfig};
use std::collections::HashMap;
let mut factories: FactoryRegistry = HashMap::new();
factories.insert(
"Organization".to_string(),
define_factory(
vec![FieldDef { name: "name".into(), field_type: "string".into(), required: true }],
|data, ctx| Box::pin(create_organization(data, ctx)),
Some(|record, ctx| Box::pin(delete_organization(record, ctx))),
None,
),
);
factories.insert(
"User".to_string(),
define_factory_create_only(
vec![
FieldDef { name: "email".into(), field_type: "string".into(), required: true },
FieldDef { name: "name".into(), field_type: "string".into(), required: true },
FieldDef { name: "organization_id".into(), field_type: "string".into(), required: true },
],
|data, ctx| Box::pin(create_user(data, ctx)),
),
);
let config = HandlerConfig {
// The column that scopes all models to a tenant - used to isolate test data
scope_field: "organization_id".to_string(),
// Shared with Autonoma - verifies incoming requests via HMAC-SHA256
shared_secret,
// Private to your server - signs the refs token so teardown only deletes what was created
signing_secret,
factories,
// Deprecated no-op, but the struct still requires the field
allow_production: false,
// Called after `up` - returns credentials so Autonoma can make authenticated requests
auth: Box::new(|_user, _ctx| {
Box::pin(async move {
let mut out: HashMap = HashMap::new();
out.insert(
"headers".into(),
serde_json::json!({ "Authorization": "Bearer REPLACE_WITH_A_REAL_TOKEN" }),
);
out
})
}),
sdk: None,
before_down: None,
after_up: None,
};
let app = Router::new()
.route("/api/autonoma", post(create_axum_handler(config)));
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/rust/axum)
***
## What `input_fields` does
The `Vec` you pass as the first argument to `define_factory`:
1. **Drives discover** - the SDK uses the field definitions to describe the model to the dashboard (field names, types, required/optional). No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK checks that all required fields are present in the `serde_json::Map`. Your factory body works on a validated map.
3. **Keeps it simple** - no external dependencies required beyond `serde_json`. Use `"string"`, `"integer"`, `"number"`, `"boolean"`, `"timestamp"`, `"date"`, `"uuid"`, or `"json"` as the type.
# Go
> Autonoma Environment Factory example with Gin.
The Go SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s `InputStruct` (a Go struct type). There is no database introspection, no SQL executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## Gin
Uses `autonoma.GinHandler` with factories registered in an `autonoma.FactoryRegistry` map. The factories use whatever `*sql.DB`, GORM, or service layer your app already has - the SDK does not need a database connection.
main.go
```go
import (
"os"
"reflect"
"github.com/autonoma-ai/sdk-go/autonoma"
"github.com/gin-gonic/gin"
)
type OrganizationInput struct {
Name string `json:"name"`
}
type UserInput struct {
Email string `json:"email"`
Name string `json:"name"`
OrganizationID string `json:"organization_id"`
}
config := &autonoma.HandlerConfig{
// The column that scopes all models to a tenant - used to isolate test data
ScopeField: "organization_id",
// Shared with Autonoma - verifies incoming requests via HMAC-SHA256
SharedSecret: os.Getenv("AUTONOMA_SHARED_SECRET"),
// Private to your server - signs the refs token so teardown only deletes what was created
SigningSecret: os.Getenv("AUTONOMA_SIGNING_SECRET"),
// Every model the dashboard can create needs a factory.
// The factory's InputStruct drives both validation and discover.
Factories: autonoma.FactoryRegistry{
"Organization": autonoma.FactoryDefinition{
InputStruct: reflect.TypeOf(OrganizationInput{}),
Create: func(input interface{}, ctx autonoma.FactoryContext) (map[string]any, error) {
in := input.(*OrganizationInput)
return createOrganization(db, in)
},
Teardown: func(record interface{}, ctx autonoma.FactoryContext) error {
rec := record.(map[string]any)
return deleteOrganization(db, rec["id"].(string))
},
},
"User": autonoma.FactoryDefinition{
InputStruct: reflect.TypeOf(UserInput{}),
Create: func(input interface{}, ctx autonoma.FactoryContext) (map[string]any, error) {
in := input.(*UserInput)
return createUser(db, in)
},
},
},
// Called after `up` - returns credentials so Autonoma can make authenticated requests
Auth: func(user map[string]any, ctx autonoma.AuthContext) (map[string]any, error) {
return map[string]any{
"headers": map[string]any{"Authorization": "Bearer REPLACE_WITH_A_REAL_TOKEN"},
}, nil
},
}
r := gin.Default()
r.POST("/api/autonoma", autonoma.GinHandler(config))
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/go/gin)
***
## What `InputStruct` does
The Go struct type you pass as `InputStruct`:
1. **Drives discover** - the SDK uses `reflect` to walk the struct’s fields and `json` tags to describe the model to the dashboard (field names, types, required/optional). No database introspection runs.
2. **Validates the create payload** - before invoking your `Create` function, the SDK uses `json.Unmarshal` into a new instance of the struct. Type mismatches and missing required fields fail validation. Your factory body receives a typed pointer to the struct.
3. **Uses standard Go conventions** - field names come from `json` struct tags; Go types map to SDK types automatically (`string`→“string”, `int`→“integer”, `float64`→“number”, `bool`→“boolean”, `time.Time`→“timestamp”, `uuid.UUID`→“uuid”).
# PHP
> Autonoma Environment Factory example with Laravel.
The PHP SDK is **factory-driven**: you register one factory per model and the SDK derives the discover schema from each factory’s `inputFields`. There is no database introspection, no Eloquent executor, and no SQL fallback - your factories own creation, the SDK owns the protocol.
> **Replace the auth callback before you ship:**
>
> The `auth` callback below returns a hardcoded placeholder token so the example stays readable. **It will not work.** Autonoma uses whatever `auth` returns to sign in as the user the scenario just created, so a fixed string means every test fails at login.
>
> Swap it for your app’s real session or token creation - the same code path your login endpoint uses. See [Authentication](/environment-factory/authentication/) for the three supported shapes: session cookies, bearer tokens, and raw credentials.
## Laravel
Uses the auto-discovered service provider from `autonoma-ai/sdk`. The entire setup is configuration-driven via `config/autonoma.php`. The factories use whatever Eloquent models, repositories, or service classes your app already has - the SDK does not need a database connection.
config/autonoma.php
```php
'organization_id',
// Shared with Autonoma - verifies incoming requests via HMAC-SHA256
'shared_secret' => env('AUTONOMA_SHARED_SECRET', ''),
// Private to your server - signs the refs token so teardown only deletes what was created
'signing_secret' => env('AUTONOMA_SIGNING_SECRET', ''),
'path' => 'api/autonoma',
// Every model the dashboard can create needs a factory.
// The factory's inputFields drives both validation and discover.
'factories' => [
'Organization' => Factory::define(
inputFields: [
new FieldInfo('name', 'string', true),
],
create: function (array $data, FactoryContext $ctx) {
return (new OrganizationRepository())->create(['name' => $data['name']]);
},
teardown: function (array $record, FactoryContext $ctx) {
(new OrganizationRepository())->delete($record['id']);
}
),
'User' => Factory::define(
inputFields: [
new FieldInfo('email', 'string', true),
new FieldInfo('name', 'string', true),
new FieldInfo('organization_id', 'string', true),
],
create: function (array $data, FactoryContext $ctx) {
return (new UserRepository())->create([
'email' => $data['email'],
'name' => $data['name'],
'organization_id' => $data['organization_id'],
]);
}
),
],
// Called after `up` - returns credentials so Autonoma can make authenticated requests
'auth' => function (?array $user, array $context): array {
return ['headers' => ['Authorization' => 'Bearer REPLACE_WITH_A_REAL_TOKEN']];
},
];
```
[Full source code on GitHub](https://github.com/Autonoma-AI/sdk/tree/main/examples/php/laravel)
***
## What `inputFields` does
The `FieldInfo` array you pass as `inputFields`:
1. **Drives discover** - the SDK uses the field definitions to describe the model to the dashboard (field names, types, required/optional). No database introspection runs.
2. **Validates the create payload** - before invoking your `create` function, the SDK checks that all required fields are present and strips unknown keys. Your factory body works on a clean associative array.
3. **Keeps it simple** - no external dependencies required. Use `'string'`, `'integer'`, `'number'`, `'boolean'`, `'timestamp'`, `'date'`, `'uuid'`, or `'json'` as the type.
# Secrets
> How to give your preview apps the credentials they need - API keys, database URLs, tokens - without committing them, and how the platform stores and injects them.
A secret is any value you wouldn't commit to your repo - a Stripe key, a database URL, a signed token. You set it once, the platform stores it encrypted, and every preview deploy mounts it into your app as an environment variable. Your code just reads `process.env.STRIPE_API_KEY` and gets the value.
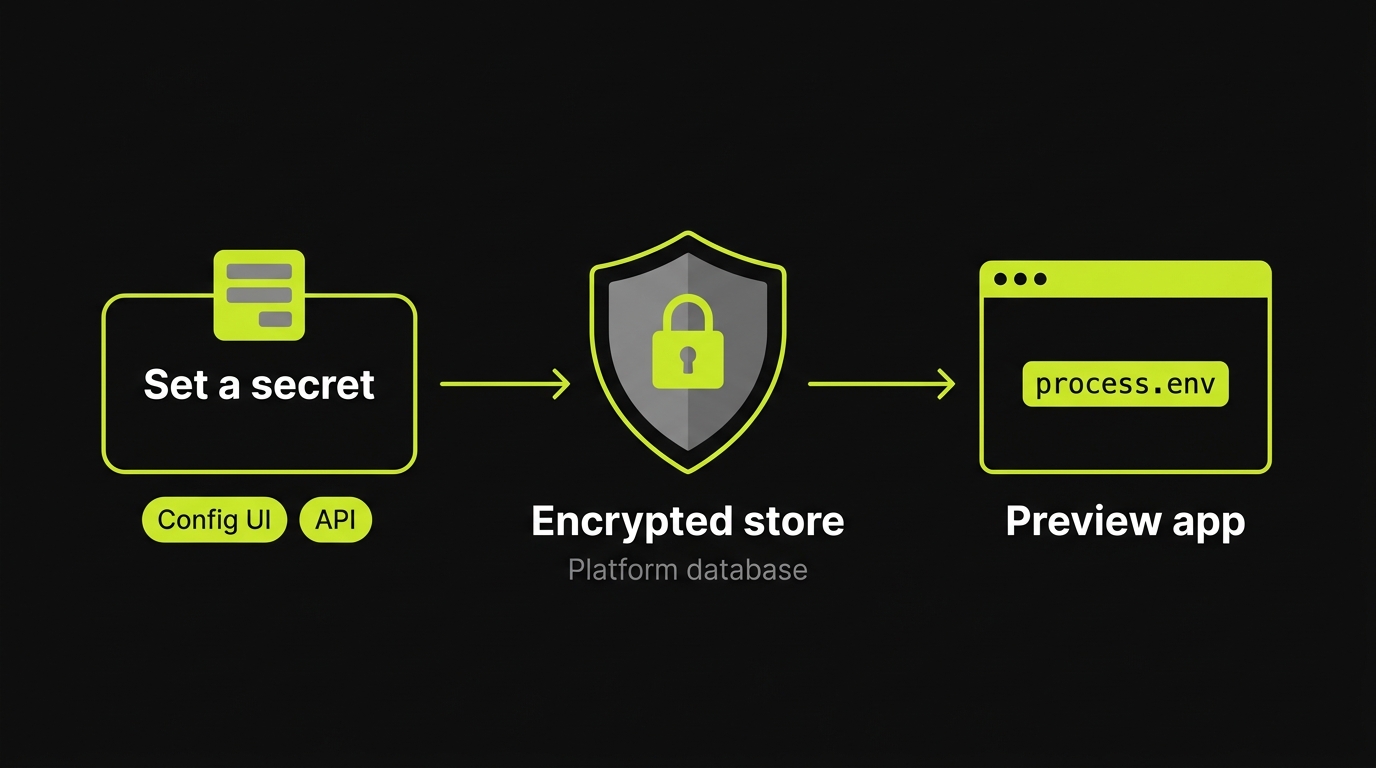
## Two ways to set a secret
* **In the config UI (most common).** The **Variables** step of preview setup holds every variable for an app in one list, with an editor beside it. This is the right place for a one-off, or when you’re setting things up by hand for the first time.
* **From the API (for CI / automation).** Script it when you have many keys, or rotate them from a pipeline. See [Managing secrets from the API](#managing-secrets-from-the-api) below.
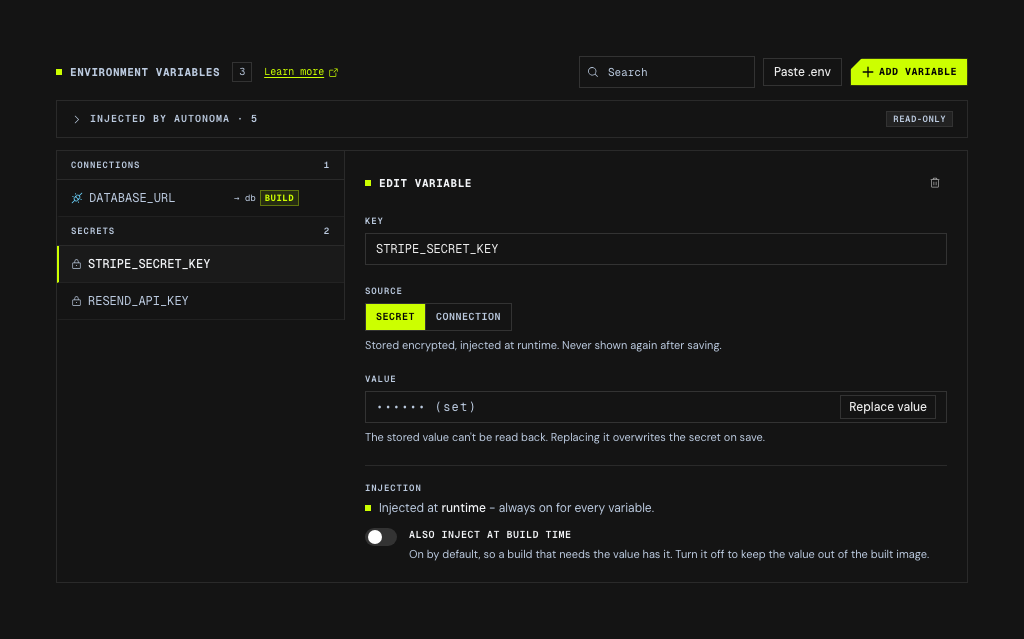
Two things in that panel are worth knowing before you start. A saved secret can only be **replaced**, never read back - the value field shows `•••••• (set)` and nothing else. And the **Source** control is where the secret-versus-connection decision below actually gets made, with the product writing the one-line rationale for each next to it.
Both routes write to the same encrypted store, so a value set in the UI is visible to the API and vice versa. The value lives encrypted in the platform’s database - never in your config, never in your repo - and is only ever readable by your own organization. Updates take effect on the next preview deploy for that app.
Because a secret lives outside the config, it also saves on its own. When the only thing you have changed is secrets, the save button reads **Save secrets** and writes just those - so a rotation goes through even when the rest of the config is mid-edit or has a problem of its own. The build-time toggle saves the same way: it is a property of the secret, not of the config.
## Secret, connection, or config value?
Not everything your app reads from `process.env` is a secret. Picking the right home is the thing people get wrong most often, so start here:
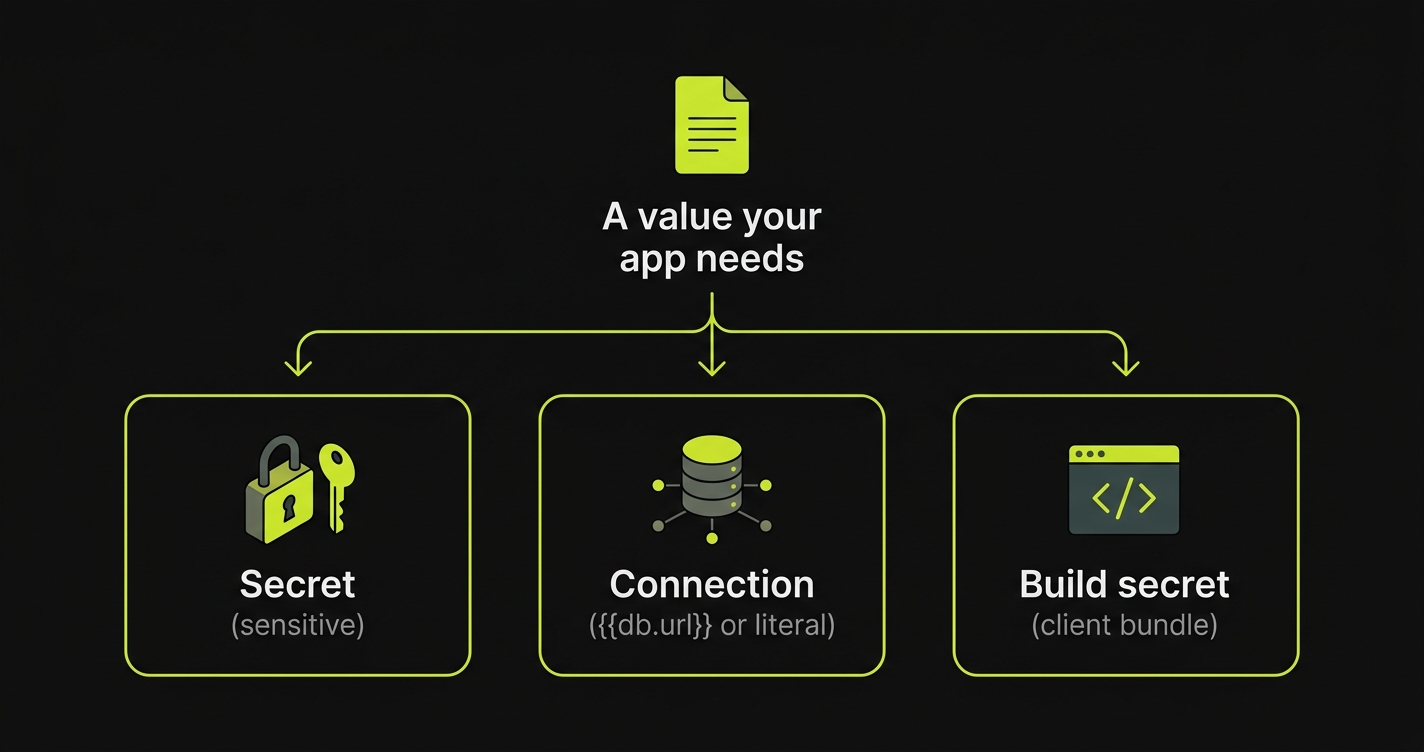
| Value | Where it goes | Why |
| ------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------- |
| Sensitive - API keys, database URLs, signed tokens | **Secret** (UI Variables step or API) | Stored encrypted, never in the repo or config. |
| The address of another app/service in the same preview (`{{db.host}}`, `{{api.url}}`) | **[Connection](/preview-environments/connections/)** - a templated value in the Variables step | The platform resolves the real in-cluster address at deploy time. Nothing to upload. |
| Non-sensitive value that varies per environment (`PLAID_ENV=sandbox`) | **[Connection](/preview-environments/connections/)** with a literal value | Pinned alongside the rest of the config. Nothing to upload. |
| A value baked into a client bundle at build time (`NEXT_PUBLIC_*`, `VITE_*`) | **Secret, marked build-time** | Must be present *during* the build, not just at runtime. See [Build-time secrets](#build-time-secrets). |
| PR / owner / namespace metadata (`{{pr}}`, `AUTONOMA_PREVIEWKIT_PR`) | Injected automatically | Reserved built-ins. See [Built-in environment variables](#built-in-environment-variables). |
When in doubt, if the value is sensitive, make it a **Secret**. A secret added in the UI is build-time by default, so the client-bundle case works without you thinking about it - see [Build-time secrets](#build-time-secrets) for when to turn that off.
## Managing secrets from the API
Automate secrets from CI with four endpoints:
```plaintext
GET /v1/previewkit/secrets/:applicationId/:app # list keys (no values)
PUT /v1/previewkit/secrets/:applicationId/:app # batch upsert; body: {"items":[{"key","value"},...]}
PUT /v1/previewkit/secrets/:applicationId/:app/:key # single upsert; body: {"value":"..."}
DELETE /v1/previewkit/secrets/:applicationId/:app/:key # delete one key
```
`applicationId` is your autonoma Application row id. Look it up once via the dashboard and hardcode it in your CI. `app` matches an app’s `name` in your stack configuration. For a single-app repo it’s just that one name; for a monorepo each app has its own bundle.
### Authentication
Every call needs an `Authorization: Bearer ` header. Create an API key from the autonoma dashboard (Settings → API keys); keys are scoped to your organization, so they can only see and modify your own applications’ secrets. Treat them like a password.
```bash
export AUTONOMA_API_KEY="ak_live_..."
# Batch upsert
curl -X PUT "https://api.autonoma.app/v1/previewkit/secrets/app_abc123/web" \
-H "Authorization: Bearer $AUTONOMA_API_KEY" \
-H "Content-Type: application/json" \
-d '{"items":[{"key":"STRIPE_API_KEY","value":"sk_live_..."},{"key":"SENTRY_DSN","value":"https://..."}]}'
# Single key upsert
curl -X PUT "https://api.autonoma.app/v1/previewkit/secrets/app_abc123/web/STRIPE_API_KEY" \
-H "Authorization: Bearer $AUTONOMA_API_KEY" \
-H "Content-Type: application/json" \
-d '{"value":"sk_live_..."}'
# List keys (names only, never values)
curl "https://api.autonoma.app/v1/previewkit/secrets/app_abc123/web" \
-H "Authorization: Bearer $AUTONOMA_API_KEY"
# Delete
curl -X DELETE "https://api.autonoma.app/v1/previewkit/secrets/app_abc123/web/STRIPE_API_KEY" \
-H "Authorization: Bearer $AUTONOMA_API_KEY"
```
Calls without a valid Bearer token get a 401. Calls referencing an `applicationId` your key doesn’t have access to are indistinguishable from “no secrets yet” - the API never reveals whether a foreign application exists.
## Build-time secrets
`NEXT_PUBLIC_*` values for Next.js, `VITE_*` values for Vite, anything else baked into a client bundle at compile time - these need to be present during `next build` / `vite build`, not just at runtime.
Build-time-ness belongs to the secret itself, so you set it where you set the value - and a new secret is build-time by default, in the UI (**Also inject at build time**, on) and over the API alike. The client-bundle case therefore works without you thinking about it.
Turn it off for a value the image must not carry:
```bash
# MCP
set_secret(repoFullName, prNumber, app, key, value, buildTime: false)
```
Omitting `buildTime` on a key that already exists leaves its setting alone, so rotating a value never quietly changes when it is used.
A build-time value is written into the image, so anyone who can pull that image can read it. Preview images are private to your organization and thrown away with the preview, which is why the default leans towards builds that work - but a value you would not want sitting in an image belongs off the toggle.
Server-only secrets (those your running pod reads via `process.env`) do not *need* to be build-time - every secret is in the runtime mount regardless.
Because the flag lives on the value, a key cannot be marked build-time before it has one. Set the value and the flag together and the build has what it needs; leave the value unset and the build simply does not receive that variable.
## Config-level overrides
If you also define a key as an app [connection](/preview-environments/connections/) in your stack configuration, the connection’s value wins over the uploaded secret. Use this for behaviour switches you want pinned alongside the rest of the config:
```yaml
apps:
- name: api
port: 4000
connections:
# Pin a preview to safe defaults so it can't talk to live services.
- key: PLAID_ENV
value: "sandbox"
- key: SEND_EMAILS_LOCALLY
value: "false"
```
Connection values are templates - `{{api.host}}`, `{{pr}}`, and friends resolve at deploy time. See the [template reference](/preview-environments/connections/#template-reference).
## Built-in environment variables
Autonoma injects a few variables into every preview app automatically. You don’t upload them, and you can’t override them - the names are reserved. The dashboard rejects them, but this REST API does not validate the key - setting one here returns success and is then silently overridden at deploy time, so do not rely on an error to catch a typo.
| Variable | Value | Notes |
| ------------------------- | ------------------------------------- | --------------------------------------------------------------------------------------------------- |
| `AUTONOMA_PREVIEWKIT` | `true` | Always set inside a preview. Use it to detect the environment. |
| `AUTONOMA_PREVIEWKIT_PR` | `123` | The pull request number this preview was built from. |
| `AUTONOMA_PREVIEWKIT_URL` | `https://.preview.autonoma.app` | The public HTTPS URL of this app in the preview. In a multi-app preview, each app gets its own URL. |
A common use is tagging your error reporter so preview errors are grouped per PR:
```ts
import * as Sentry from "@sentry/node";
Sentry.init({
dsn: process.env.SENTRY_DSN,
// "pr-123" in a preview, "production" everywhere else.
environment: process.env.AUTONOMA_PREVIEWKIT_PR != null
? `pr-${process.env.AUTONOMA_PREVIEWKIT_PR}`
: "production",
});
```
# Scenario Recipe Schema
> Canonical JSON contract for the scenario recipes file uploaded to Autonoma at POST /v1/setup/setups/:id/scenario-recipe-versions.
This page documents the **canonical upload contract** for scenario recipes. It is language-agnostic: the schema is described as JSON with per-field expectations. The source of truth lives in `packages/types/src/schemas/scenarios.ts` (`ScenarioRecipesFileSchema`).
The file is posted as the JSON body of:
```plaintext
POST /v1/setup/setups/:setupId/scenario-recipe-versions
```
The planner **analyzes** your project in place but **writes** everything it generates - the discovery output, the scenarios document, and the recipe file itself - to its own output directory at `~/.autonoma//`. Nothing is written into the repository, so the `source` paths below point into that directory, not at committed files.
## Top-level shape
```json
{
"version": 1,
"source": {
"discoverPath": "string",
"scenariosPath": "string"
},
"validationMode": "sdk-check" | "endpoint-lifecycle",
"recipes": [ /* at least one ScenarioRecipe */ ]
}
```
| Field | Type | Required | Notes |
| ---------------------- | --------------------------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `version` | integer, must equal `1` | yes | Contract version. Currently only `1` is accepted. Not a string. |
| `source` | object | yes | Provenance pointers into the planner’s output directory. Additional keys are preserved. |
| `source.discoverPath` | string | yes | Path to the discovery output the recipes were derived from, inside the planner’s output directory (`~/.autonoma//`), e.g. `autonoma/discover.json`. **Required** - omitting it causes Zod to fail with `Invalid input: expected string, received undefined`. |
| `source.scenariosPath` | string | yes | Path to the human-readable scenarios document, in the same output directory, e.g. `autonoma/scenarios.md`. |
| `validationMode` | `"sdk-check"` \| `"endpoint-lifecycle"` | yes | How Autonoma validated the recipes before upload. `sdk-check` = `checkScenario`/`checkAllScenarios`. `endpoint-lifecycle` = real HTTP `up`/`down`. |
| `recipes` | array, minimum length `1` | yes | One entry per scenario. See below. |
## `ScenarioRecipe` (one entry in `recipes[]`)
```json
{
"name": "string",
"description": "string",
"create": { /* arbitrary model graph, see below */ },
"variables": { /* optional, see below */ },
"validation": {
"status": "validated",
"method": "checkScenario" | "checkAllScenarios" | "endpoint-up-down",
"phase": "ok",
"up_ms": 0,
"down_ms": 0
}
}
```
| Field | Type | Required | Notes |
| -------------------- | --------------------------------------------------------------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `name` | string | yes | Stable identifier. Must match the scenario name used in the LLM-facing docs. |
| `description` | string | yes | Human-readable summary of the scenario state. |
| `create` | object | yes | The model graph passed to the SDK’s `createScenario` / `up` flow. A flat map: keys are model names, values are arrays of seeded rows. Rows link with `_alias` / `_ref`, and a `_ref` is resolved wherever it appears - including nested inside an object or an array. Extra keys are preserved. |
| `variables` | object (map of name → definition) | no | **Deprecated.** Still accepted for recipes that already declare it, but no longer generated or documented. Use the built-in tokens below instead. |
| `validation` | object | yes | Proof that the recipe was validated. All fields must be present. |
| `validation.status` | literal string `"validated"` | yes | |
| `validation.method` | one of `"checkScenario"`, `"checkAllScenarios"`, `"endpoint-up-down"` | yes | Which validator produced this result. |
| `validation.phase` | literal string `"ok"` | yes | |
| `validation.up_ms` | non-negative integer | no | Milliseconds the `up` phase took. |
| `validation.down_ms` | non-negative integer | no | Milliseconds the `down` phase took. |
## Built-in tokens
Every value in `create` must be concrete, with exactly two exceptions. These tokens are written in **double braces** and need no declaration - Autonoma substitutes them when it provisions the scenario.
| Token | Value |
| -------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `{{testRunId}}` | The id of this provisioning run - the same value Autonoma sends the Environment Factory as the `up` request’s `testRunId`, so your recipe and your handler agree on one identity. |
| `{{testRunShortId}}` | An 8-character hash of `{{testRunId}}`, for columns too short to hold a UUID (usernames, slugs, subdomains). |
They exist for one reason: concurrent runs of the same scenario would otherwise collide on unique columns. Use them anywhere a value must be unique per run, including inside a longer string.
```json
"User": [
{
"_alias": "admin",
"email": "admin-{{testRunShortId}}@acme.test",
"externalId": "{{testRunId}}"
}
]
```
Any other `{{token}}` is rejected on upload - there is no general variable mechanism.
> **Deprecated: the :**
>
> Recipes could once declare a `variables` map of `literal` / `derived` / `faker` definitions. Autonoma still resolves it for recipes that already carry one, but it is no longer generated and should not be added to new recipes. The two built-in tokens above cover the only case it was needed for.
## Full example
```json
{
"version": 1,
"source": {
"discoverPath": "autonoma/discover.json",
"scenariosPath": "autonoma/scenarios.md"
},
"validationMode": "sdk-check",
"recipes": [
{
"name": "adminWithTwoProjects",
"description": "Organization with an admin user and two projects.",
"create": {
"Organization": [{ "_alias": "org-1", "name": "Acme" }],
"User": [
{
"email": "admin-{{testRunShortId}}@acme.test",
"role": "admin",
"organizationId": { "_ref": "org-1" }
}
],
"Project": [
{ "name": "Alpha", "organizationId": { "_ref": "org-1" } },
{ "name": "Beta", "organizationId": { "_ref": "org-1" } }
]
},
"validation": {
"status": "validated",
"method": "checkScenario",
"phase": "ok",
"up_ms": 142,
"down_ms": 61
}
}
]
}
```
## Common rejection reasons
* **`Invalid input: expected string, received undefined` under `source.discoverPath`** - the `source` object is missing `discoverPath`. Both `discoverPath` and `scenariosPath` are required.
* **`These tokens resolve to nothing: {{}}. Autonoma only substitutes {{testRunId}} and {{testRunShortId}}; replace the rest with concrete values.`** - the `create` graph uses a `{{token}}` that is not one of the two built-ins. Replace it with a concrete value.
* **`These _ref targets match no _alias in the graph`** - a row references an alias no row declares. Add the `_alias`, or drop the reference.
* **`The create graph must map each model name to an array of records`** - a model maps to a scalar or a bare array of non-objects. The Environment Factory rejects the whole seed in that shape.
* **`version` must be literal `1`** - don’t send `"1"` or `"1.0"`. Integer `1`.
* **`recipes` must contain at least 1 element** - empty arrays are rejected.
* **`validation.status` / `validation.phase` mismatch** - both are fixed literals (`"validated"` / `"ok"`). Any other value fails.
## Related
* [Test Planner](/test-planner/) - how scenarios are designed and recipes are validated before upload.
* [Environment Factory](/environment-factory/) - the `up` / `down` / `discover` SDK that consumes these recipes at runtime.
# Development Setup
> How to get Autonoma AI running locally - from prerequisites through a working dev environment.
## Prerequisites
You need three things installed before starting:
| Tool | Version | How to get it |
| --------------------------------- | ------- | --------------------------------------------------------------- |
| [Node.js](https://nodejs.org/) | >= 24 | Use [nvm](https://github.com/nvm-sh/nvm) or download directly |
| [pnpm](https://pnpm.io/) | 11.x | Run `corepack enable` - the version is pinned in `package.json` |
| [Docker](https://www.docker.com/) | Latest | Docker Desktop or Docker Engine |
**Optional tools** (only needed if you’re working on specific engines):
* [Playwright](https://playwright.dev/) - for `engine-web` development
* [Appium](https://appium.io/) - for `engine-mobile` development
## Clone and install
```bash
git clone https://github.com/autonoma-ai/autonoma.git
cd agent
pnpm install
```
`pnpm install` handles the entire monorepo - all apps and packages get their dependencies in one pass.
## Start infrastructure
PostgreSQL and Redis run via Docker Compose:
```bash
docker compose up -d
```
This starts:
* **PostgreSQL 18** on `localhost:5432` (user: `postgres`, password: `postgres`)
* **Redis** on `localhost:6379`
Verify they’re running:
```bash
docker compose ps
```
Both containers should show `running` status.
## Environment variables
Copy the example file and fill in the required values:
```bash
cp .env.example .env
```
### Minimum required variables
| Variable | Description | Where to get it |
| ---------------------- | ------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `DATABASE_URL` | PostgreSQL connection string | Use `postgresql://postgres:postgres@localhost:5432/autonoma` for the Docker Compose setup |
| `REDIS_URL` | Redis connection string | Use `redis://localhost:6379` for the Docker Compose setup |
| `BETTER_AUTH_SECRET` | Session signing secret | Generate any random string: `openssl rand -hex 32` |
| `BETTER_AUTH_URL` | The API’s own address - where `/v1/auth/*` is reachable | `http://localhost:4000` for local dev. Better-auth uses this (not `APP_URL`) as `baseURL`, so it’s what OAuth providers redirect back to. |
| `GOOGLE_CLIENT_ID` | Google OAuth client ID | Create OAuth credentials in the [Google Cloud Console](https://console.cloud.google.com/apis/credentials). Set the authorized redirect URI to `http://localhost:4000/v1/auth/callback/google` |
| `GOOGLE_CLIENT_SECRET` | Google OAuth client secret | Same Google Cloud Console OAuth credentials page |
| `GEMINI_API_KEY` | Google Gemini API key | Get one from [Google AI Studio](https://aistudio.google.com/apikey) |
### Optional: GitHub sign-in
The login page offers Google and GitHub. GitHub is optional - the API only registers the provider when both variables below are set, so leaving them empty gives you a Google-only login.
| Variable | Description | Where to get it |
| ---------------------- | ------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `GITHUB_CLIENT_ID` | GitHub OAuth app client ID | Create an OAuth app at [github.com/settings/developers](https://github.com/settings/developers). Set the authorization callback URL to `http://localhost:4000/v1/auth/callback/github` |
| `GITHUB_CLIENT_SECRET` | GitHub OAuth app client secret | Generate one on the same OAuth app page - GitHub shows it only once |
To create the OAuth app:
1. Go to **Settings -> Developer settings -> OAuth Apps -> New OAuth App** on GitHub.
2. **Application name**: anything you’ll recognize, e.g. `Autonoma (local)`.
3. **Homepage URL**: `http://localhost:3000` (the UI).
4. **Authorization callback URL**: `http://localhost:4000/v1/auth/callback/github` (the API - better-auth serves the callback, not the UI).
5. Register the app, copy the client ID, then **Generate a new client secret** and copy that too.
6. Put both in `.env` as `GITHUB_CLIENT_ID` and `GITHUB_CLIENT_SECRET`, and restart the API.
> **Caution:**
>
> These are not the `GITHUB_APP_*` variables. Those belong to the separate GitHub App that reads repositories and posts PR checks. Sign-in uses an OAuth app, which is a different thing you create on the same settings page.
Signing in with GitHub against an email that already has a Google account links the two, so you land in the same account either way. Linking requires both emails to be verified - GitHub sign-in with an unverified GitHub email lands back on the login page with an error.
### How environment variables work in the codebase
The project uses `createEnv` from `@t3-oss/env-core` for environment variable validation. Each app has an `env.ts` file that defines its required variables with Zod schemas. Variables are validated at startup - if something is missing, you get a clear error message telling you exactly what to add.
You should never read `process.env` directly in application code. Instead, import from the app’s `env.ts` file.
See `.env.example` for the full list of variables grouped by service. Most optional variables have sensible defaults or are only needed for specific features (S3 storage, Sentry, PostHog, etc.).
## Database setup
Generate the Prisma client and run migrations:
```bash
pnpm db:generate
pnpm db:migrate
```
`db:generate` creates the TypeScript client from the Prisma schema. `db:migrate` applies all migrations to create the database tables.
You need to re-run `db:generate` whenever the Prisma schema changes (after pulling new changes or editing the schema yourself).
## Start development servers
```bash
pnpm dev
```
This starts both servers concurrently:
* **UI** at `http://localhost:3000` (Vite + React)
* **API** at `http://localhost:4000` (Hono + tRPC)
To run them individually:
```bash
pnpm api # API only (port 4000)
pnpm ui # UI only (port 3000)
```
## Verify everything works
1. Open `http://localhost:3000` in your browser
2. You should see the login page
3. Sign in with Google (or GitHub, if you configured an OAuth app for it)
4. If you see the dashboard, everything is working
Run the full check suite to make sure nothing is broken:
```bash
pnpm typecheck # TypeScript type checking
pnpm lint # ESLint
pnpm test # Vitest
pnpm build # Full build
```
## Other useful commands
| Command | Description |
| ------------------ | ------------------------------------------------ |
| `pnpm dev` | Start API + UI in development mode |
| `pnpm build` | Build all packages and apps |
| `pnpm typecheck` | Run TypeScript type checking across all packages |
| `pnpm lint` | Lint all packages |
| `pnpm test` | Run tests across all packages |
| `pnpm format` | Format code with Biome |
| `pnpm check` | Lint and format with Biome |
| `pnpm db:generate` | Generate Prisma client from schema |
| `pnpm db:migrate` | Run database migrations |
| `pnpm docs` | Start the documentation site (port 4321) |
## Troubleshooting
### `pnpm install` fails
Make sure you’re using pnpm 12.x. Run `corepack enable` to let Node manage the pnpm version, then try again.
### Database connection refused
Check that Docker Compose is running: `docker compose ps`. If PostgreSQL isn’t up, check logs with `docker compose logs postgres`.
### Prisma generate fails
This usually means dependencies aren’t installed. Run `pnpm install` first, then `pnpm db:generate`.
### Port already in use
Another process is using port 3000 or 4000. Find and kill it:
```bash
lsof -i :3000 # or :4000
kill
```
### Google OAuth redirect error
Make sure your Google Cloud OAuth credentials have `http://localhost:4000/v1/auth/callback/google` as an authorized redirect URI - better-auth uses `BETTER_AUTH_URL` (the API’s own address) as `baseURL`, so that’s what it sends Google as the `redirect_uri`, not the UI’s origin.
### GitHub OAuth redirect error
Same cause as the Google one: the authorization callback URL on your GitHub OAuth app must be `http://localhost:4000/v1/auth/callback/github` (the API’s address from `BETTER_AUTH_URL`), not the UI’s origin. GitHub rejects a mismatch with `redirect_uri is not associated with this application`.
If the GitHub button sends you straight back to `/login` with a “Sign in failed” toast, check the API logs - a boot log line reading `GitHub OAuth credentials not configured` means `GITHUB_CLIENT_ID` or `GITHUB_CLIENT_SECRET` is missing, so the provider was never registered.
### `Failed to decrypt private key` error from Better Auth
The API’s JWKS keypair (`jwks` table) is encrypted with `BETTER_AUTH_SECRET`. If that row was created under a different secret than the one currently in your `.env` - for example after regenerating `BETTER_AUTH_SECRET`, since Docker Compose keeps Postgres data in a persistent volume across restarts - decryption fails once, then self-heals (Better Auth regenerates the keypair under the current secret on the next request). If you’d rather not wait for that, clear the stale row yourself:
```bash
psql $DATABASE_URL -c "TRUNCATE TABLE jwks;"
```
### “Missing environment variable” error on startup
The app validates all required environment variables at startup using `createEnv`. Check the error message for which variable is missing, then add it to your `.env` file.
### TypeScript errors after pulling changes
Run `pnpm db:generate` first (the Prisma client may have changed), then `pnpm build` to rebuild all packages. TypeScript errors in the UI or API often come from stale package builds.
# Architecture Overview
> High-level architecture of Autonoma AI - how the monorepo is organized, how data flows, and why each technology was chosen.
## How Autonoma works
Autonoma is an agentic E2E testing platform. Tests are written in natural language - usually generated from the codebase by the planner rather than written by hand - and an AI agent executes them in a real browser. The core loop is:
1. A test says what to verify (“Log in, go to settings, check the avatar is visible”)
2. The execution agent takes a screenshot of the current screen
3. An LLM decides which action to perform (click, type, scroll, assert)
4. A platform driver executes it - Playwright, against the pull request’s preview environment
5. The agent records the step and repeats until the test is done
Around that loop sits the rest of the product: previewkit builds the environment each run needs, the Environment Factory seeds its data, and the API and workers orchestrate the whole thing and report back on the pull request.
## Monorepo structure
The codebase is split into **apps** (deployable services) and **packages** (shared libraries). Each package has exactly one concern.
```plaintext
apps/
api/ Hono + tRPC API server
ui/ Vite + React 19 SPA
previewkit/ Preview environments - builds and deploys a PR's stack to Kubernetes
cli/ @autonoma-ai/planner - the published test-planner CLI
workers/ Temporal workers: diffs, general, web, mobile
jobs/ Standalone background jobs
cronjobs/ Scheduled tasks
docs/ Astro Starlight documentation site
packages/
agent-core/ The agent loop, tool plumbing, and compaction
agent-guidance/ Guidance Autonoma gives an agent or human when a request cannot proceed
ai/ Sharp-free AI core - model registry, structured generation
visual-ai/ Screenshot-driven AI - visual checkers, point detection
analytics/ PostHog server-side event tracking
auth/ Authentication
billing/ Credits, top-ups, and Stripe
blacklight/ Shared UI component library
checkpoint/ Run checkpoints
db/ Prisma schema + generated client
diffs/ Change analysis for a pull request
emulator/ Mobile emulator management (dormant)
engine/ Platform-agnostic execution agent core
engine-web/ Playwright web test execution
engine-mobile/ Appium mobile test execution (dormant - see below)
errors/ Custom error hierarchy
github/ GitHub App and API client
image/ Image processing utilities
integration-test/ Test harness with Testcontainers
k8s/ Kubernetes helpers
logger/ Sentry-based structured logging
scenario/ Environment Factory scenario logic
secrets/ Secret storage and retrieval
storage/ S3 file storage
test-suite/ A branch's suite lineage - snapshots, the open snapshot, and runs
try/ Go-style [value, error] result tuples
types/ Shared Zod schemas and TypeScript types
utils/ Shared utilities
workflow/ Temporal workflow definitions
```
> **Mobile is dormant:**
>
> `engine-mobile` and `emulator` are still in the tree and still compile, but they are **not part of what ships today**. Neither has a Dockerfile, and neither has had feature work since June 2026 - changes since have been repo-wide sweeps. The product is web-only: read anything below about Appium, devices, or emulators as describing code that exists, not a capability you can use.
### Why apps vs packages?
**Apps** are independently deployable. Each one becomes its own image and runs as its own process - the API, the UI, previewkit, and each worker never share a runtime. `apps/cli` is the exception: it is published to npm as `@autonoma-ai/planner` and runs on the user’s machine.
**Packages** are shared code, consumed at build time via pnpm workspaces; none of them runs on its own. A package like `@autonoma/engine` is used by every engine, and `@autonoma/ai` by anything that calls a model.
## How the apps connect
```plaintext
Browser
|
| HTTP (port 3000)
v
UI (Vite + React SPA)
|
| tRPC (port 4000)
v
API (Hono + tRPC)
|
|--- Prisma ---> PostgreSQL
|--- Redis ----> Caching
|
| (starts a Temporal workflow)
v
Workers (apps/workers)
|
|--- previewkit ---> builds and deploys the PR's stack
|--- Environment Factory ---> seeds test data for the run
v
Engine Web
|
| Execution Agent (packages/engine)
|--- Playwright
|--- AI models (packages/ai, packages/visual-ai)
v
Results, recordings, artifacts -> reviewed -> comment on the PR
```
**UI to API**: The React SPA communicates with the API exclusively through tRPC. Types flow end-to-end - the frontend never manually defines API response types. Zod schemas in `packages/types` are the single source of truth for both sides.
**API to Database**: The API uses Prisma as its ORM. The schema lives in `packages/db` and is shared across all backend services.
**API to workers**: A pull-request event starts a Temporal workflow rather than calling an engine directly. The workers in `apps/workers` own the long-running pipeline - provisioning the preview, seeding data, running the suite, reviewing the result - so a restart never loses a run in flight.
**Engines to AI**: During execution, engines call `packages/ai` for structured generation and `packages/visual-ai` for element detection and visual assertions. The two are split because `visual-ai` depends on `sharp`, which some hosts (the API among them) cannot load. Calls go to external providers - Google Gemini, Groq, OpenRouter.
## Tech stack
| Layer | Technology | Why |
| -------------- | ------------------------------------------ | ---------------------------------------------------------------------------------------------------- |
| Runtime | Node.js 24, ESM-only | Latest LTS with native ESM. No CommonJS compatibility issues |
| Monorepo | pnpm workspaces + Turborepo | pnpm for fast, disk-efficient installs. Turborepo for cached, parallel builds |
| Language | TypeScript (strictest) | Full type safety with `noUncheckedIndexedAccess`, `exactOptionalPropertyTypes`, and all strict flags |
| API | Hono + tRPC | Hono is fast and lightweight. tRPC gives end-to-end type safety without code generation |
| Frontend | React 19 + Vite + TanStack Router | Vite for fast dev builds. TanStack Router for type-safe routing with built-in data loading |
| Database | PostgreSQL + Prisma | PostgreSQL for reliability. Prisma for type-safe queries and migration management |
| Cache/Locking | Redis | Caching, and distributed locking where instances share a resource |
| AI | Gemini, Groq, OpenRouter via Vercel AI SDK | Multiple providers for different tasks. Vercel AI SDK unifies the interface |
| Web testing | Playwright | Most reliable browser automation library. Supports all major browsers |
| Mobile testing | Appium | Present in `engine-mobile`, currently dormant - the shipped product is web-only |
| UI components | Radix UI + Tailwind CSS v4 + CVA | Accessible primitives (Radix), utility-first styling (Tailwind), type-safe variants (CVA) |
| Observability | Sentry | Error tracking, performance monitoring, and structured logging in one tool |
| Analytics | PostHog | Product analytics with server-side event tracking |
| Deployment | Kubernetes + Temporal | K8s for orchestration. Temporal for workflow-based test execution pipelines |
## The execution flow
This is the most important flow in the system - how a test goes from natural language to executed results.
### 1. Test creation
Tests are natural-language markdown. Most are generated by the planner (`apps/cli`) reading the customer’s codebase and uploaded to Autonoma; they can also be edited by hand. The API stores them in PostgreSQL.
### 2. Test dispatch
A pull-request event starts a Temporal workflow. It provisions the preview environment for that PR, asks the Environment Factory to seed the data the scenario needs, and then hands the suite to the web engine.
### 3. Execution agent loop
The execution agent (`packages/engine`) runs a loop powered by the Vercel AI SDK:
```plaintext
Screenshot -> LLM decides action -> Execute command -> Record step -> Repeat
```
The agent has access to these commands:
| Command | What it does |
| ---------- | --------------------------------------------------------------------------------------- |
| **click** | Uses vision AI to locate an element from a natural language description, then clicks it |
| **type** | Locates an element, clicks it, then types text |
| **scroll** | Scrolls up or down |
| **assert** | Checks visual conditions against the current screenshot |
| **wait** | Pauses for a specified duration (for loading states) |
The LLM (currently Gemini) sees the screenshot, the test instruction, and the steps taken so far, then decides which command to call next. When it determines the test is complete (or has failed), it calls `execution-finished`.
### 4. AI-powered element detection
Instead of CSS selectors or XPaths, the agent uses vision models to find UI elements. The `PointDetector` takes a screenshot and a natural language description (“the blue Submit button”) and returns pixel coordinates. This is what makes tests resilient to UI changes - the AI adapts to visual changes automatically.
### 5. Results and artifacts
Every test run produces:
* Step-by-step execution log with before/after screenshots
* Video recording of the entire session
* AI conversation log (what the model “thought” at each step)
* Success/failure status with reasoning
These artifacts are stored in S3 and accessible through the UI.
## Key design decisions
### ESM-only
Every `package.json` has `"type": "module"`. No CommonJS anywhere. This eliminates an entire class of import/export bugs and aligns with the direction of the Node.js ecosystem.
### Strictest TypeScript
All strict flags enabled, including `noUncheckedIndexedAccess` (array/object access returns `T | undefined`) and `exactOptionalPropertyTypes`. This catches real bugs at compile time. It’s more work upfront, but prevents entire categories of runtime errors.
### Constructor injection
All dependencies are passed through constructors. No DI framework, no decorators, no magic. You can read any class and immediately see what it depends on.
### Separate Docker images
Each worker (web, mobile) and each job type gets its own Docker image, linking in the engine package it needs. This keeps images small and deployment independent. A change to the web engine doesn’t require redeploying the mobile worker.
### Platform-agnostic agent core
All execution logic lives in `packages/engine`. Platform-specific apps (`engine-web`, `engine-mobile`) only implement driver interfaces (`ScreenDriver`, `MouseDriver`, etc.). The same agent loop, command system, and AI integration works for both Playwright and Appium.
## Deployment model
The platform runs on Kubernetes:
* **API** and **UI** are standard deployments with horizontal scaling
* **Engines** run on device-hosting machines (physical or virtual). Web engines need browsers, mobile engines need connected devices or emulators
* **Jobs** run as Temporal workflows - triggered on demand via Temporal workers
* **Redis** handles distributed device locking across engine instances
* **PostgreSQL** is the single source of truth for all state
# Package Guide
> What each package and app does, what it exports, and when you would modify it.
## Packages
Every package in `packages/` is a shared library consumed by one or more apps. Each has exactly one concern.
Internal tooling is deliberately left out - the eval harnesses and their results database exist to measure and improve the agents, and have nothing to do with building or running the product.
> **Mobile is dormant:**
>
> `emulator` and `engine-mobile` are still in the tree and still compile, but they are not part of what ships today - the only image that would link them, `workers/mobile`, is never built or deployed by any workflow, and neither package has had feature work since June 2026. The product is web-only. They are listed here because the code exists, not because it is a capability you can use.
### agent-core
The agent loop itself - tool plumbing, the step cycle, retries, and context compaction. Platform-agnostic and model-agnostic; `engine` builds the execution agent on top of it.
**Key exports:** `Agent`, tool base classes, compaction helpers
**When to modify:** Changing how any agent in the codebase loops, calls tools, or compacts its context.
### agent-guidance
One source of truth for the guidance Autonoma gives an agent or human when a request cannot proceed - the AI catalog of MCP/connect surfaces, the `llms.txt` generator, the “needs a human” prompt, and the unauthorized-access guidance the API returns.
**Key exports:** `aiCatalog`, `aiCatalogLinkHeader`, `llmsTxt`, `needsHuman`, `unauthorizedGuidance`
**When to modify:** Changing what Autonoma tells an agent about its own surfaces, or the wording a blocked request returns.
### ai
The **sharp-free** AI core: the model registry (LLM instances, providers, per-call cost collection), structured output generation, and text utilities. Everything screenshot-driven lives in `visual-ai` instead, so hosts that cannot load `sharp` - the API among them - can still call a model.
**Key exports:** `ModelRegistry`, `CostCollector`, `ObjectGenerator`, `AssertionSplitter`, `MODEL_ENTRIES`
**When to modify:** Adding a model or provider, changing pricing or cost attribution, or adjusting structured generation.
### analytics
PostHog server-side event tracking. Wraps `posthog-node` with Sentry trace linking. No-ops when not initialized, so it’s safe to import in dev and test environments.
**Key exports:** `analytics` (singleton)
**When to modify:** Adding new server-side analytics events, changing event properties, or adjusting the PostHog integration.
### auth
Authentication - sessions, organisation membership, and the checks the API applies to every request.
**When to modify:** Changing how users sign in, or how access to an organisation or application is decided.
### billing
Subscription and billing logic. Handles plan management, usage tracking, and payment integration.
**Key exports:** Billing service classes and plan definitions
**When to modify:** Changing pricing plans, adding billing features, or integrating new payment providers.
### blacklight
Shared UI component library built on Radix UI + Tailwind CSS v4 + CVA. This is where all reusable frontend components live - buttons, cards, inputs, dialogs, tables, and more. Follows shadcn/ui patterns.
**Key exports:** `Button`, `Card`, `Input`, `Dialog`, `Table`, `Select`, `cn()`, and many more components
**When to modify:** Adding new UI components, updating component styles, or changing the design system. The path alias `@/*` maps to `packages/blacklight/src/*` inside the package.
### checkpoint
Run checkpoints: the record of what a run had established at each point, so a later run can compare against it.
**When to modify:** Changing what a checkpoint captures or how runs are compared over time.
### db
Prisma schema and generated client for PostgreSQL. This is the single source of truth for the database structure.
**Key exports:** `PrismaClient`, generated types for all models
**When to modify:** Adding or changing database tables, columns, relations, or indexes. After editing the schema, run `pnpm db:generate` and `pnpm db:migrate`.
### diffs
Test diff computation. Computes differences between test suite versions for change tracking and review.
**Key exports:** Diff computation functions
**When to modify:** Changing how test diffs are calculated or displayed.
### emulator
Mobile emulator management. Handles lifecycle management of iOS simulators and Android emulators.
**Key exports:** Emulator management classes
**When to modify:** Adding support for new device types, changing emulator configuration, or adjusting lifecycle management.
### engine
The core of test execution. This is a platform-agnostic AI agent that web and mobile engines extend. Contains the execution agent loop, command system (click, type, scroll, assert), driver interfaces, runner orchestration, and artifact management.
Everything is parameterized with generics (`TSpec` for command specs, `TContext` for driver context), so the same agent core works for both Playwright and Appium.
**Key exports:** `ExecutionAgent`, `ExecutionAgentRunner`, `AgentCommand`, `CommandRegistry`, driver interfaces (`ScreenDriver`, `MouseDriver`, `KeyboardDriver`, `NavigationDriver`, `ApplicationDriver`)
**When to modify:** Adding new commands to the agent, changing the execution loop, adjusting the system prompt, or modifying how steps are recorded.
### engine-mobile
Appium-based mobile test execution for iOS and Android. Implements the driver interfaces from `engine` using Appium/WebDriver. Uses `@autonoma/device-lock` for Redis-based device allocation. Linked into the `workers/mobile` image.
**When to modify:** Changing mobile-specific test execution behavior, adjusting Appium configuration, or adding support for new device types.
### engine-web
Playwright-based web test execution. Implements the driver interfaces from `engine` using Playwright’s API. Handles browser lifecycle, screenshot capture, network idle detection, and video recording. Linked into the `workers/web` and `workers/diffs` images.
**When to modify:** Changing web-specific test execution behavior, adjusting Playwright configuration, or fixing browser-related issues.
### errors
Custom error hierarchy for the project. All errors extend `AutonomaError` with specific subclasses for different failure types.
**Key exports:** `AutonomaError`, `TestError`, `DriverError`, `PreconditionError`, `VerificationError`, `ThirdPartyError`
**When to modify:** Adding new error types or changing how errors are categorized.
### github
The GitHub App and API client - installation tokens, repository access, pull-request events, and the comments Autonoma posts back.
**When to modify:** Changing anything that talks to GitHub.
### image
Image processing utilities. Handles screenshot manipulation, resizing, and format conversion used throughout the execution pipeline.
**Key exports:** Image processing functions
**When to modify:** Changing how screenshots are processed, adding new image operations, or adjusting compression settings.
### integration-test
Test harness using Testcontainers. Provides `IntegrationHarness` and `integrationTestSuite` for writing integration tests that use real PostgreSQL and Redis containers.
**Key exports:** `IntegrationHarness`, `integrationTestSuite`
**When to modify:** Changing the test harness setup, adding new test utilities, or supporting new infrastructure in tests.
### k8s
Kubernetes helpers. Utilities for interacting with the K8s API, managing pods, and reading cluster state.
**Key exports:** Kubernetes client wrappers and helpers
**When to modify:** Changing how the platform interacts with Kubernetes, or adding new K8s operations.
### logger
Sentry-based structured logging. Provides a logger that integrates with Sentry for error tracking, performance monitoring, and structured context.
**Key exports:** `logger` (root logger), `Logger` type
**When to modify:** Changing the logging format, adjusting Sentry integration, or adding new logging capabilities.
### scenario
Environment Factory scenario logic. Handles test scenario definitions, data seeding, and teardown for isolated test environments. It also owns which deployment the SDK endpoint belongs to: the branch deployment recording where a branch’s tests point, and whether Autonoma hosts that preview at all. How the endpoint URL is spelled lives in `types` (`sdk-endpoint.ts`) instead, so callers that cannot depend on this package can still reach it.
**Key exports:** Scenario classes and types, `resolveSdkConfig`, `resolveConfiguredSdkPath`, `recordBranchDeployment`, `autonomaHostsPreviews`
**When to modify:** Adding new test scenarios, changing how test data is seeded, adjusting the Environment Factory protocol, or changing how a preview URL is recorded and reached.
### secrets
Storage and retrieval of customer secrets - preview environment variables, signing secrets, and third-party tokens.
**When to modify:** Changing how secrets are stored, encrypted, or resolved at deploy time.
### storage
S3 file storage. Handles uploading and downloading artifacts (screenshots, videos, test results) to S3-compatible storage.
**Key exports:** Storage service classes
**When to modify:** Changing storage providers, adjusting upload/download logic, or adding new artifact types.
### test-suite
The data-access layer for a branch’s test suite lineage: the line of immutable snapshots the suite evolves through, the single open snapshot being written, the branch’s `activeSnapshotId` / `pendingSnapshotId` / `baseSnapshotId` pointers, and the runs. It owns `test_case`, `test_plan`, `test_case_assignment`, `branch_snapshot`, `branch` and `test_generation`, and writes nothing else.
**Key exports:** `TestSuiteStore`, `OpenSnapshot`, `deriveForkPointSnapshotId`
**When to modify:** Changing how a branch’s suite evolves - opening or finalizing a snapshot, adding or adopting a test, revising a plan.
### try
Go-style error handling. Wraps a fallible call into a `[value, error]` tuple so the error path is explicit at the call site instead of hidden in a `try`/`catch`.
**Key exports:** `Try`, `Success`, `Failure`
**When to modify:** Rarely - it is a small, stable utility.
### types
Shared Zod schemas and TypeScript types. This is the contract layer between the API and frontend. Schemas defined here are used for tRPC input validation and frontend type inference.
**Key exports:** Zod schemas for all API inputs/outputs, TypeScript types, constants
**When to modify:** Adding new API endpoints, changing request/response shapes, or adding shared constants.
### utils
Shared utilities that don’t fit into a more specific package.
**Key exports:** Various utility functions
**When to modify:** Adding general-purpose utilities used across multiple packages.
### visual-ai
The screenshot-driven half of the AI stack: visual condition checking, assertion checking, point detection (locating an element from a natural-language description), and object detection. Depends on `ai` and on `image`, which means `sharp`.
**Key exports:** `PointDetector`, `ObjectDetector`, `VisualConditionChecker`, `AssertChecker`
**When to modify:** Changing how elements are located on screen, or adjusting assertion logic.
### workflow
Temporal workflow definitions and client. Orchestrates test execution pipelines using Temporal workflows and activities.
**Key exports:** Workflow builder classes
**When to modify:** Changing how test execution is orchestrated, adjusting workflow templates, or adding new pipeline steps.
## Apps
### api
The backend server. Built with Hono (HTTP framework) and tRPC (type-safe API layer). Routers are thin - they wire tRPC procedures to controller files in `controllers//`. One file per procedure.
**When to modify:** Adding new API endpoints, changing business logic, or adjusting authentication.
### ui
The frontend SPA. Built with React 19, Vite, and TanStack Router. Compiled to static files - no SSR. Uses `@autonoma/blacklight` for all UI components.
**When to modify:** Adding new pages, changing the UI, or adjusting frontend behavior.
### previewkit
Preview environments. Builds each app in a pull request, provisions the databases and extra services it needs, deploys the whole stack to its own Kubernetes namespace, and tears it down when the PR closes.
**When to modify:** Changing how previews are built, deployed, configured, or destroyed.
### cli
Published to npm as `@autonoma-ai/planner`. Runs on the user’s machine, reads their codebase, and generates the knowledge base, scenarios, test-data recipe, and E2E test suite. Bundled with tsup.
**When to modify:** Changing the planner pipeline, its terminal dashboard, or the coding-agent handoff for test data.
### workers
Temporal workers. Each subdirectory is its own deployable: `diffs`, `general`, `web`, `mobile`. They own the long-running pipeline - provisioning, seeding, running, reviewing - so a restart never loses a run in flight.
**When to modify:** Adding a workflow or activity, or changing how a run is orchestrated.
### cronjobs
Scheduled tasks that run on a timer rather than in response to an event.
**When to modify:** Adding or changing a scheduled task.
### docs
This documentation site. Built with Astro Starlight and deployed to S3 + CloudFront.
**When to modify:** Adding or updating documentation pages.
### jobs
Background job services, each deployed as a separate Docker image:
| Job | Purpose |
| ------------------------------- | ------------------------------------------------------------------------ |
| **run-completion-notification** | Stripe billing refund on failed generations, plus the mark-failed reaper |
## Dependency graph
The general dependency flow (simplified):
```plaintext
apps (api, ui, workers, jobs)
|
+-- packages/types (shared schemas - used by almost everything)
+-- packages/db (database - used by api, jobs)
+-- packages/engine-web (Playwright execution - used by workers/web, diffs)
+-- packages/engine-mobile (Appium execution - used by workers/mobile)
+-- packages/engine (execution core - used by the engine packages)
+-- packages/ai (AI primitives - used by engine, jobs)
+-- packages/try (error handling - used by everything)
+-- packages/logger (logging - used by everything)
+-- packages/errors (error types - used by engine, api)
+-- packages/storage (S3 - used by api, engines, jobs)
+-- packages/blacklight (UI components - used by ui only)
+-- packages/analytics (PostHog - used by api)
+-- packages/workflow (Temporal workflows - used by api, workers)
```
Key relationships:
* `packages/engine` depends on `packages/ai` for all AI operations
* `packages/ai` is self-contained - it only depends on `try`, `logger`, and `image`
* `packages/types` is a leaf dependency - it depends on nothing else in the monorepo
* `packages/try` is a leaf dependency - used everywhere, depends on nothing
* Both `engine-web` and `engine-mobile` depend on `packages/engine` but never on each other
# Code Conventions
> The rules of the Autonoma AI codebase - TypeScript patterns, error handling, logging, testing, and style guidelines.
## ESM-only
Every `package.json` has `"type": "module"`. No CommonJS anywhere in the codebase.
**Never use `.js` extensions in imports.** TypeScript and the bundler resolve modules automatically.
```ts
// Good
import { foo } from "./foo";
import { bar } from "@autonoma/types";
// Bad
import { foo } from "./foo.js";
```
## TypeScript strictness
All strict flags are enabled. Every package extends `tsconfig.base.json`, which includes:
* `strict: true` (enables all strict checks)
* `noUncheckedIndexedAccess` - array and object index access returns `T | undefined`
* `exactOptionalPropertyTypes` - optional properties can’t be assigned `undefined` explicitly unless typed that way
* `verbatimModuleSyntax` - enforces explicit `type` imports
In practice, this means:
* You must check array access results before using them
* You must narrow types before passing them to functions that expect non-nullable values
* You must use `import type { ... }` for type-only imports
## Classes vs functions
**Needs state or dependencies?** Use a class with constructor injection.
**Pure logic with no state?** Use a function file.
In practice, almost everything is a class because most logic needs a logger, a database client, or some other dependency.
## Dependency injection
Plain constructor injection. No DI framework, no decorators.
```ts
class StepExecutor {
private readonly logger: Logger;
constructor(
private readonly engine: Engine,
private readonly db: PrismaClient,
) {
this.logger = logger.child({ name: this.constructor.name });
}
}
```
You can read any class constructor and immediately see all its dependencies. No magic, no hidden state.
## One export per file
A file exports exactly one thing - a class, a function, or a type. The exported item tells the story top-to-bottom. Private helpers follow in call order.
This keeps files focused and makes imports predictable.
### Custom error hierarchy
```plaintext
AutonomaError (base)
TestError - test execution failures
DriverError - Appium/Playwright driver failures
PreconditionError - setup/precondition failures
VerificationError - assertion failures
ThirdPartyError - external service failures
```
## Prefer undefined over null
Always use `undefined` as the absence-of-value sentinel. Use optional properties (`?`) instead of `| null` types. Never initialize to `null`.
```ts
// Good
private timeout?: number
// Bad
private timeout: number | null = null
```
This applies everywhere: class properties, function parameters, return types, object shapes.
## Nullish checks
Always `??`, never `||`. Always `!= null` / `== null`, never truthy/falsy checks.
```ts
// Good
const timeout = config.timeout ?? 3000;
if (element != null) { /* ... */ }
// Bad - truthy/falsy has unexpected behavior with 0, "", false
const timeout = config.timeout || 3000; // 0 becomes 3000!
if (element) { /* ... */ }
```
The `!= null` check covers both `null` and `undefined`, which is exactly what you want.
## Early returns
Always prefer early returns to reduce nesting. If a function has deeply nested `if` blocks, extract the inner logic into a separate function with guard clauses.
```ts
// Good
function processOrder(order: Order): Result {
if (order.status === "cancelled") throw new OrderCancelledError();
if (order.items.length === 0) throw new EmptyOrderError();
return calculateTotal(order);
}
// Bad - deeply nested
function processOrder(order: Order): Result {
if (order.status !== "cancelled") {
if (order.items.length > 0) {
return calculateTotal(order);
}
}
// ...
}
```
## No complex destructuring or spread
If constructing an object requires multiple `...` spreads or ternary-based spreads, build the object explicitly instead.
```ts
// Good
const permissions = isAdmin ? allPermissions : readOnly;
return {
name: baseConfig.name,
timeout: baseConfig.timeout,
permissions,
retries: overrides.retries ?? baseConfig.retries,
};
// Bad
return {
...baseConfig,
...((isAdmin) ? { permissions: allPermissions } : { permissions: readOnly }),
...overrides,
};
```
## Extract complex conditions
If a condition isn’t immediately obvious, extract it into a descriptively named variable.
```ts
// Good
const isTrialExpired = subscription.status === "trial" && subscription.endsAt < now;
const hasNoPaymentMethod = user.paymentMethods.length === 0;
if (isTrialExpired && hasNoPaymentMethod) { /* ... */ }
// Bad - what does this check?
if (subscription.status === "trial" && subscription.endsAt < now && user.paymentMethods.length === 0) { /* ... */ }
```
## Avoid let + conditional assignment
Instead of using `let` and assigning in `if/else` blocks, extract a function with early returns.
## Logging with Sentry
Every class and every function file must have logging. When in doubt, add a log. Overlogging is always better than underlogging.
### What to log
* Service startup and configuration
* Incoming requests and their resolution (success/failure)
* External API calls (start, success, failure)
* State transitions (agent steps, job status changes)
* Resource acquisition/release (device locks, browser sessions)
* Every public method entry with relevant parameters
* Every method exit with relevant results
Use structured context (Sentry breadcrumbs, tags, extra data) so logs are searchable. Never log sensitive data (credentials, tokens).
### Class logger pattern
Every class gets a `private readonly logger` instance, created in the constructor as a child of the root logger with the class name and identifying context.
```ts
import { type Logger, logger } from "@autonoma/logger";
export class SnapshotEditService {
private readonly logger: Logger;
constructor(private readonly snapshotId: string) {
this.logger = logger.child({ name: this.constructor.name, snapshotId });
}
public async addTest(input: AddTestInput) {
this.logger.info("Adding test to edit session", { name: input.name });
// ... do work ...
this.logger.info("Test added to edit session");
}
}
```
### Function logger pattern - called from classes
If a reusable function is called from a class method, accept a `Logger` parameter to preserve the logging context chain.
```ts
import type { Logger } from "@autonoma/logger";
export function computeChanges(branchId: string, logger: Logger) {
logger.info("Computing changes", { branchId });
// ... do work ...
logger.info("Changes computed", { count: changes.length });
return changes;
}
```
### Function logger pattern - standalone files
If a file exports independently useful functions (not called from a single class), import the root logger and create a child per function.
```ts
import { logger as rootLogger } from "@autonoma/logger";
export function syncDevices(deviceIds: string[]) {
const logger = rootLogger.child({ name: "syncDevices" });
logger.info("Syncing devices", { count: deviceIds.length });
// ... do work ...
logger.info("Devices synced");
}
```
## Testing
### Philosophy
* **Vitest** for all tests
* **Prefer integration tests** over unit tests. Test the real thing, not mocks
* **Never mock the database.** Use Testcontainers with a real PostgreSQL container
* Only test what makes sense - don’t test trivial getters
### Setup
Test files go in `test/` directories that mirror the `src/` structure. File naming: `*.test.ts`.
For integration tests that need a database, use the `@autonoma/integration-test` package:
```ts
import { integrationTestSuite } from "@autonoma/integration-test";
integrationTestSuite("MyService", (harness) => {
it("should create a record", async () => {
const db = harness.db;
// ... test with a real database
});
});
```
The harness spins up a real PostgreSQL container via Testcontainers, runs migrations, and gives you a fresh database for each test suite.
### Running tests
```bash
pnpm test # run all tests
pnpm test --filter=ai # run tests in a specific package
```
## Database transactions
Wrap sequential database queries in a Prisma `$transaction` when they must be consistent. If a service method reads then writes (or writes to multiple tables), use `$transaction`:
```ts
async createGeneration(userId: string, orgId: string, appId: string) {
return await this.db.$transaction(async (tx) => {
const app = await tx.application.findFirst({
where: { id: appId, organizationId: orgId },
});
if (app == null) throw new Error("Application not found");
const generation = await tx.applicationGeneration.create({
data: { /* ... */ },
});
await tx.onboardingState.upsert({
where: { applicationId: appId },
/* ... */
});
return { id: generation.id };
});
}
```
Pass `tx` to all queries inside the transaction - not the original `db` client.
## Adding dependencies
**Always check `pnpm-workspace.yaml` first.** The catalog section defines pinned versions for shared dependencies. When adding a dependency:
1. Check if it already exists in the `catalog:` section
2. If it does, use `"catalog:"` as the version in `package.json`
3. If it doesn’t, consider whether it should be added to the catalog (used by multiple packages) or pinned locally
```jsonc
// Good - uses catalog version
"dependencies": {
"zod": "catalog:"
}
// Bad - hardcodes a version when a catalog entry exists
"dependencies": {
"zod": "^3.23.0"
}
```
## Environment variables
Never read `process.env` directly. Define all environment variables in a dedicated `env.ts` file using `createEnv` from `@t3-oss/env-core` with Zod schemas:
```ts
import { createEnv } from "@t3-oss/env-core";
import { z } from "zod";
export const env = createEnv({
server: {
DATABASE_URL: z.string().url(),
REDIS_URL: z.string().url(),
BETTER_AUTH_SECRET: z.string().min(1),
},
runtimeEnv: process.env,
});
```
This gives you type safety, runtime validation, and a single source of truth for all required variables. Pass validated env values as function parameters rather than reading `process.env` in library code.
# Common Workflows
> Step-by-step guides for common development tasks - adding routes, pages, commands, models, tests, and more.
This page covers the most common development tasks you will perform in the Autonoma monorepo. Each workflow is a step-by-step guide with file paths and code patterns.
## Adding a New tRPC Route
Types flow through tRPC from API to frontend. Never manually define API response types on the frontend.
**1. Define Zod schemas** in `packages/types/src/schemas/`:
packages/types/src/schemas/my-feature.ts
```ts
import z from "zod";
export const myFeatureInput = z.object({
name: z.string(),
organizationId: z.string(),
});
export const myFeatureOutput = z.object({
id: z.string(),
createdAt: z.date(),
});
```
**2. Create a controller** in `apps/api/src/controllers//.ts`. Controllers hold all business logic:
apps/api/src/controllers/myFeature/create.ts
```ts
import type { PrismaClient } from "@autonoma/db";
import type { z } from "zod";
import type { myFeatureInput } from "@autonoma/types";
export async function createMyFeature(
db: PrismaClient,
input: z.infer,
) {
return db.myFeature.create({
data: { name: input.name, organizationId: input.organizationId },
});
}
```
**3. Create or update the router** in `apps/api/src/routers/`. Routers are thin wiring - they delegate to controllers:
apps/api/src/routers/my-feature.ts
```ts
import { router, protectedProcedure } from "../trpc";
import { myFeatureInput } from "@autonoma/types";
import { createMyFeature } from "../controllers/myFeature/create";
export const myFeatureRouter = router({
create: protectedProcedure
.input(myFeatureInput)
.mutation(async ({ ctx, input }) => {
return createMyFeature(ctx.db, input);
}),
});
```
**4. Add to `appRouter`** in `apps/api/src/router.ts` (if this is a new router):
```ts
export const appRouter = router({
// ...existing routers
myFeature: myFeatureRouter,
});
```
**5. Use on the frontend.** For queries, use `useSuspenseQuery` with `queryOptions`:
```ts
const { data } = useSuspenseQuery(
trpc.myFeature.list.queryOptions({ organizationId }),
);
```
For mutations, use `useAPIMutation` with `mutationOptions`:
```ts
const createMutation = useAPIMutation(
trpc.myFeature.create.mutationOptions(),
);
```
## Adding a New Page
TanStack Router with file-based routing makes this straightforward.
**1. Create a route file** in `apps/ui/src/routes/`:
apps/ui/src/routes/my-feature.tsx
```ts
import { createFileRoute } from "@tanstack/react-router";
export const Route = createFileRoute("/my-feature")({
component: MyFeaturePage,
});
function MyFeaturePage() {
return
My Feature
;
}
```
**2. That’s it.** The TanStack Router plugin auto-generates the route tree. The page is immediately accessible at `/my-feature`.
For pages that need data, add a `loader`:
```ts
export const Route = createFileRoute("/my-feature")({
loader: ({ context }) => {
context.queryClient.ensureQueryData(
trpc.myFeature.list.queryOptions(),
);
},
component: MyFeaturePage,
});
```
## Database Schema Changes
**1. Edit the schema** at `packages/db/prisma/schema.prisma`.
**2. Create a migration:**
```bash
pnpm db:migrate
```
This generates a migration file and applies it to your local database.
**3. Regenerate the Prisma client:**
```bash
pnpm db:generate
```
**4. Run typecheck** to catch any type errors from the schema change:
```bash
pnpm typecheck
```
If multiple queries in a service method need to be consistent (read-then-write, or writes to multiple tables), wrap them in a Prisma `$transaction`:
```ts
return await this.db.$transaction(async (tx) => {
const existing = await tx.myTable.findFirst({ where: { id } });
if (existing == null) throw new Error("Not found");
return tx.myTable.update({ where: { id }, data: { ... } });
});
```
## Adding a New Command to the Execution Agent
See the [Execution Agent](/architecture/execution-agent/#adding-a-new-command) page for a detailed walkthrough. The short version:
**1. Define the spec** with a `CommandSpec` interface and Zod schema in `packages/engine/src/commands/commands//.def.ts`.
**2. Implement the command** by extending `Command` in `packages/engine/src/commands/commands//.command.ts`.
**3. Create the tool wrapper** by extending `CommandTool` in `packages/engine/src/execution-agent/agent/tools/commands/.tool.ts`.
**4. Add the spec** to the union type in `packages/engine/src/commands/command-defs.ts`.
**5. Register the tool** in the `ExecutionAgentFactory` subclass for the relevant platform(s).
**6. Write tests** in `packages/engine/src/commands/commands//.test.ts`. Use the test utilities in `packages/engine/src/commands/test-utils/` for fake drivers and model registries.
## Adding a New AI Model
See the [AI Package](/architecture/ai-package/#adding-a-new-model) page for full details. The short version:
**1. Add the model entry** to `MODEL_ENTRIES` in `packages/ai/src/registry/model-entries.ts`:
```ts
MY_MODEL: {
createModel: () => googleProvider.getModel("my-model-id"),
pricing: simpleCostFunction({
inputCostPerM: 0.5,
outputCostPerM: 1.5,
}),
},
```
**2. Add a provider** in `packages/ai/src/registry/providers.ts` if the model uses a new provider. Add the API key to `packages/ai/src/env.ts` using `createEnv`.
**3. Use it** via `registry.getModel({ model: "MY_MODEL", tag: "my-use-case" })`.
## Running and Writing Tests
Vitest is used everywhere. Every package has it installed.
### Running Tests
```bash
# Run all tests across the monorepo
pnpm test
# Run tests for a specific package
pnpm --filter @autonoma/engine test
# Run a specific test file
pnpm --filter @autonoma/ai test -- src/visual/assert-checker.test.ts
# Run in watch mode
pnpm --filter @autonoma/engine test -- --watch
```
### Writing Tests
**Prefer integration tests over unit tests.** Only test what provides value - don’t test trivial getters.
Test files go in `test/` directories or alongside source files as `*.test.ts`.
**Never mock the database.** For tests that need a database, use Testcontainers with a real PostgreSQL container via the `@autonoma/integration-test` package:
```ts
import { integrationTestSuite } from "@autonoma/integration-test";
integrationTestSuite("MyService", ({ getDb }) => {
it("creates a record", async () => {
const db = getDb();
const result = await myService.create(db, { name: "test" });
expect(result.name).toBe("test");
});
});
```
For command tests, use the fake drivers in `packages/engine/src/commands/test-utils/`:
```ts
import { FakeScreenDriver } from "../test-utils/fake-screen.driver";
import { FakeMouseDriver } from "../test-utils/fake-mouse.driver";
```
## Working with the UI Component Library
All frontend components come from `@autonoma/blacklight`, built on Radix UI + Tailwind CSS v4 + CVA.
### Using Components
```tsx
import { Button, Card, Input, cn } from "@autonoma/blacklight";
function MyComponent() {
return (
);
}
```
### Icons
Use Lucide React for all icons:
```tsx
import { Plus, Settings } from "lucide-react";
```
### Custom Variants
Use CVA (class-variance-authority) for component variants:
```tsx
import { cva } from "class-variance-authority";
const badgeVariants = cva("rounded-full px-2 py-0.5 text-xs font-medium", {
variants: {
status: {
active: "bg-green-100 text-green-800",
inactive: "bg-gray-100 text-gray-800",
},
},
});
```
## Adding Environment Variables
Never read `process.env` directly. Always use `createEnv` from `@t3-oss/env-core`.
**1. Define the variable** in a dedicated `env.ts` file for the package or app:
packages/my-package/src/env.ts
```ts
import { createEnv } from "@t3-oss/env-core";
import z from "zod";
export const env = createEnv({
server: {
MY_API_KEY: z.string().min(1),
MY_TIMEOUT: z.coerce.number().default(5000),
},
runtimeEnv: process.env,
});
```
**2. Use the validated env** in your code:
```ts
import { env } from "./env";
const client = new MyClient({ apiKey: env.MY_API_KEY });
```
**3. For library code**, prefer passing values as function parameters rather than reading env directly. This keeps the library testable and reusable:
```ts
// Good - library accepts config
export class MyService {
constructor(private readonly apiKey: string) {}
}
// App wires it up with env
const service = new MyService(env.MY_API_KEY);
```
**4. Check the catalog** in `pnpm-workspace.yaml` before adding `@t3-oss/env-core` as a dependency. If it is already in the catalog, use `"@t3-oss/env-core": "catalog:"` in your `package.json`.
## Adding Dependencies
Before adding any dependency, check `pnpm-workspace.yaml` for the catalog:
```bash
# Check if the package exists in the catalog
grep "my-package" pnpm-workspace.yaml
```
If the package is in the catalog, use `catalog:` as the version:
```json
{
"dependencies": {
"zod": "catalog:"
}
}
```
If it is not in the catalog but will be shared across multiple packages, consider adding it there first.
Then install:
```bash
pnpm install
```
## Building and Type Checking
```bash
# Build everything (Turborepo handles dependency order)
pnpm build
# Type check all packages
pnpm typecheck
# Lint all packages
pnpm lint
# Run dev servers (web on 3000, API on 4000)
pnpm dev
```
All packages are ESM-only. Never use `.js` extensions in imports - TypeScript resolves modules automatically.
# Environment Variables
> Complete reference for every environment variable used across the Autonoma AI monorepo - API server, frontend, AI services, database, storage, logging, billing, and infrastructure.
## Quick Start - Minimum for Local Development
To get the API and UI running locally, you need a surprisingly small set of variables. Copy `.env.example` to `.env` at the repo root and fill in these essentials:
```bash
# Database
DATABASE_URL=postgresql://postgres:postgres@localhost:5432/autonoma
# Redis
REDIS_URL=redis://localhost:6379
# API server
API_PORT=4000
SCENARIO_ENCRYPTION_KEY=any-string-at-least-1-char
# Google OAuth (create credentials at console.cloud.google.com)
GOOGLE_CLIENT_ID=your-google-client-id
GOOGLE_CLIENT_SECRET=your-google-client-secret
# GitHub OAuth (optional - create an OAuth app at github.com/settings/developers)
GITHUB_CLIENT_ID=your-github-oauth-client-id
GITHUB_CLIENT_SECRET=your-github-oauth-client-secret
# AI model keys (needed for test execution)
GEMINI_API_KEY=your-gemini-key
GROQ_KEY=your-groq-key
OPENROUTER_API_KEY=your-openrouter-key
# S3-compatible storage (can use MinIO locally)
S3_BUCKET=autonoma-local
S3_REGION=us-east-1
S3_ACCESS_KEY_ID=minioadmin
S3_SECRET_ACCESS_KEY=minioadmin
```
Everything else has sensible defaults or is optional for local development. The sections below cover every variable in detail.
## How Environment Variables Work in This Project
Every app and package defines its environment variables in a dedicated `env.ts` file using [`createEnv` from `@t3-oss/env-core`](https://env.t3.gg/). This gives you:
* **Zod validation at startup** - the process crashes immediately if a required variable is missing or malformed, rather than failing mysteriously at runtime.
* **Type safety** - `env.DATABASE_URL` is typed as `string`, not `string | undefined`. No more `process.env.DATABASE_URL!` casts.
* **Composability** - packages export their `env` object, and apps extend them. For example, the API server’s `env.ts` extends the database, storage, logger, and billing envs, inheriting all their variables.
You should **never read `process.env` directly** in application code. Always import from the nearest `env.ts`:
```ts
// Good
import { env } from "./env";
const port = env.API_PORT;
// Bad - bypasses validation
const port = process.env.API_PORT;
```
The `emptyStringAsUndefined: true` option is enabled everywhere, so setting a variable to an empty string is treated the same as not setting it at all.
For boolean variables, the codebase uses `z.stringbool()` which accepts `"true"`, `"false"`, `"1"`, `"0"`, `"yes"`, and `"no"`.
***
## Core API Server
**Source:** `apps/api/src/env.ts`
The API server extends the database, storage, logger, and billing environments, so all variables from those sections apply here too.
| Variable | Required | Default | Description |
| -------------------------- | -------- | ------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `API_PORT` | Yes | - | Port the API server listens on. Typically `4000`. |
| `INTERNAL_DOMAIN` | No | `autonoma.app` | Internal domain used for routing and service discovery. |
| `ALLOWED_ORIGINS` | No | `http://localhost:3000` | Comma-separated list of CORS origins. Must include the frontend URL. |
| `SCENARIO_ENCRYPTION_KEY` | Yes | - | Key used to encrypt scenario data. Any non-empty string works for local dev. |
| `GOOGLE_CLIENT_ID` | Yes | - | OAuth 2.0 client ID from Google Cloud Console. Required for user authentication. |
| `GOOGLE_CLIENT_SECRET` | Yes | - | OAuth 2.0 client secret from Google Cloud Console. |
| `GITHUB_CLIENT_ID` | No | - | Client ID of a GitHub OAuth app, enabling GitHub sign-in. Callback URL: `/v1/auth/callback/github`. Not the same as `GITHUB_APP_*`. |
| `GITHUB_CLIENT_SECRET` | No | - | Client secret of that GitHub OAuth app. GitHub sign-in is offered only when both this and `GITHUB_CLIENT_ID` are set. |
| `AGENT_VERSION` | No | `latest` | Version tag for the execution agent. Used when dispatching engine jobs. |
| `POSTHOG_KEY` | No | - | PostHog project API key for server-side analytics. Omit to disable analytics. |
| `POSTHOG_HOST` | No | `https://us.i.posthog.com` | PostHog ingestion endpoint. Override for self-hosted PostHog instances. |
| `OPENROUTER_API_KEY` | No | - | Server-side OpenRouter key the managed LLM proxy (`/v1/llm-proxy`, planner CLI) forwards requests with. The proxy returns `503` without it. |
| `LLM_PROXY_ENABLED` | No | `false` | Master switch for the managed LLM proxy. The route mounts only when this and `STRIPE_ENABLED` are both `true`, so usage is always metered. |
| `LLM_PROXY_ALLOWED_MODELS` | No | `google/gemini-3-flash-preview` | Comma-separated allowlist of OpenRouter model ids the proxy may route. Empty falls back to the default. |
| `REDIS_URL` | Yes | - | Redis connection string (e.g., `redis://localhost:6379`). Used for device locking, caching, and pub/sub. |
| `TESTING` | No | `false` | Set to `true` in test environments. Prevents importing certain modules. Not for general use. |
| `ENGINE_BILLING_SECRET` | No | - | Shared secret for authenticating billing calls from the engine. |
***
## Frontend (UI)
**Source:** `apps/ui/src/env.ts`
The frontend uses Vite’s `import.meta.env` and requires the `VITE_` prefix for all variables.
| Variable | Required | Default | Description |
| ---------------------- | -------- | ----------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `VITE_API_URL` | No | `http://localhost:4000` | URL of the API server. The frontend makes all tRPC calls to this address. |
| `VITE_INTERNAL_DOMAIN` | No | `autonoma.app` | Internal domain, used for UI routing logic. |
| `VITE_TEMPORAL_URL` | No | - | URL of the Temporal UI. When set, enables links to workflow runs in the dashboard. |
| `VITE_SENTRY_DSN` | No | - | Sentry DSN for frontend error tracking. Omit to disable Sentry in the browser. |
| `VITE_SENTRY_URL` | No | - | Sentry organization URL. Used for linking to Sentry issues from the UI. |
| `VITE_POSTHOG_KEY` | No | - | PostHog project API key for frontend analytics. Omit to disable analytics. PostHog events are proxied through the API server at `/rs` (feature flags at `/flags`) to bypass ad blockers. |
***
## Database
**Source:** `packages/db/src/env.ts`
| Variable | Required | Default | Description |
| -------------- | -------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| `DATABASE_URL` | Yes | - | PostgreSQL connection string. Format: `postgresql://user:password@host:port/database`. Used by Prisma for all database operations. |
> **Note:**
>
> For local development, a typical value is `postgresql://postgres:postgres@localhost:5432/autonoma`. Make sure PostgreSQL is running and the database exists before starting the API.
***
## AI Services
**Source:** `packages/ai/src/env.ts`
These keys are required by the execution engines (web and mobile) and any service that runs AI inference. The API server does not run inference itself, so it needs none of them.
| Variable | Required | Default | Description |
| -------------------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------------------------------------- |
| `GEMINI_API_KEY` | Yes | - | Google Gemini API key. Used for the primary model (Gemini 3 Flash/Pro), point detection, object detection, and visual condition checking. |
| `GROQ_KEY` | Yes | - | Groq API key. Used for fast inference with open-source models (e.g., GPT-OSS-120B). |
| `OPENROUTER_API_KEY` | Yes | - | OpenRouter API key. Provides access to Ministral-8B and serves as a fallback provider for open-source models. |
> **Note:**
>
> Validation is skipped when running in Vitest (`VITEST` env var is set), so you do not need these keys to run unit tests.
***
## Storage (S3)
**Source:** `packages/storage/src/env.ts`
Used for storing screenshots, video recordings, test artifacts, and other binary assets.
| Variable | Required | Default | Description |
| ---------------------- | -------- | ------- | ------------------------------------------------------------------ |
| `S3_BUCKET` | Yes | - | S3 bucket name for storing artifacts. |
| `S3_REGION` | Yes | - | AWS region of the S3 bucket (e.g., `us-east-1`). |
| `S3_ACCESS_KEY_ID` | Yes | - | AWS access key ID (or MinIO equivalent) for S3 authentication. |
| `S3_SECRET_ACCESS_KEY` | Yes | - | AWS secret access key (or MinIO equivalent) for S3 authentication. |
> **Local development with MinIO:**
>
> You can run [MinIO](https://min.io/) locally as an S3-compatible object store. The default credentials are `minioadmin`/`minioadmin`. Point `S3_REGION` to any valid region string (e.g., `us-east-1`) and create a bucket matching your `S3_BUCKET` value.
***
## Logging and Observability
**Source:** `packages/logger/src/env.ts`
| Variable | Required | Default | Description |
| ---------------- | -------- | ------------- | ---------------------------------------------------------------------------------------------------------- |
| `NODE_ENV` | No | `development` | Node environment. Accepts `development`, `production`, or `test`. Affects log formatting and behavior. |
| `SENTRY_DSN` | No | - | Sentry DSN for backend error tracking and performance monitoring. Omit to disable Sentry. |
| `SENTRY_ENV` | No | `production` | Sentry environment tag (e.g., `staging`, `production`). |
| `SENTRY_RELEASE` | No | `unknown` | Sentry release identifier. Typically set to the git SHA or version tag in CI. |
| `DEBUG` | No | - | Debug filter string. When set, enables verbose debug logging for matching namespaces (e.g., `autonoma:*`). |
***
## Billing (Stripe)
**Source:** `packages/billing/src/env.ts`
Billing is entirely optional. When `STRIPE_ENABLED` is `false` (the default), all billing features are disabled and no other Stripe variables are needed.
| Variable | Required | Default | Description |
| --------------------------- | -------- | ----------------------- | -------------------------------------------------------------------------------------------------------------- |
| `STRIPE_ENABLED` | No | `false` | Master switch for billing. Set to `true` to enable Stripe integration. |
| `STRIPE_SECRET_KEY` | No | - | Stripe secret API key. Required when `STRIPE_ENABLED` is `true`. |
| `STRIPE_WEBHOOK_SECRET` | No | - | Stripe webhook signing secret for verifying incoming webhook events. Required when `STRIPE_ENABLED` is `true`. |
| `BILLING_GRACE_PERIOD_DAYS` | No | `3` | Number of days after a subscription lapses before access is revoked. |
| `APP_URL` | No | `http://localhost:3000` | Frontend application URL. Used in Stripe checkout redirect URLs and billing emails. |
***
## Kubernetes and Workflows
**Source:** `packages/k8s/src/env.ts` and `packages/workflow/src/env.ts`
These variables are only needed in production or when running engine jobs on Kubernetes. Not required for local development.
| Variable | Required | Default | Description |
| ----------- | ------------ | ------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `NAMESPACE` | Yes (in K8s) | `local` (API) | Kubernetes namespace this environment runs in - `production`, `beta`, or a per-PR alpha namespace. Used by `@autonoma/k8s` to deploy jobs, and by the API to namespace session keys. See the warning below. |
> **NAMESPACE:**
>
> Every environment shares one Redis, and sessions live **only** there - `storeSessionInDatabase` is off. The API prefixes its session keys with `better-auth::` (`apps/api/src/auth.ts`), so two environments sharing a value share one session store: a session minted by an alpha, running unreviewed PR code, would be a valid production session. Changing the value invalidates every session in the environment that adopts it.
The workflow package also reads:
| Variable | Required | Default | Description |
| -------------- | -------- | ------- | ----------------------------------------------------------------------------------------------- |
| `DATABASE_URL` | Yes | - | PostgreSQL connection string. The workflow package needs direct DB access for job coordination. |
| `SENTRY_ENV` | No | - | Sentry environment tag for workflow jobs. |
***
## Engine - Web (Playwright)
**Source:** `packages/engine-web/src/platform/env.ts` and `packages/engine-web/src/execution-agent/env.ts`
The web engine extends the AI, database, logger, and storage environments. All variables from those sections apply.
| Variable | Required | Default | Description |
| -------------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------- |
| `REMOTE_BROWSER_URL` | No | - | WebSocket URL of a remote browser instance (e.g., Browserless or Playwright remote). When omitted, launches a local Chromium browser. |
| `HEADLESS` | No | - | Set to any value to run Playwright in headless mode. When omitted, the browser window is visible (useful for local debugging). |
***
## Engine - Mobile (Appium)
**Source:** `packages/engine-mobile/src/platform/env.ts`
The mobile engine extends the AI, database, logger, and storage environments. All variables from those sections apply.
| Variable | Required | Default | Description |
| -------------------------- | -------- | ------- | --------------------------------------------------------------------------------------------------------------- |
| `APPIUM_HOST` | No | - | Hostname of the Appium server. |
| `APPIUM_PORT` | No | - | Port of the Appium server. |
| `APPIUM_MJPEG_PORT` | No | - | Port for the Appium MJPEG video stream. Used for live frame capture during test execution. |
| `APPIUM_SYSTEM_PORT` | No | - | System port used by Appium’s UiAutomator2 (Android) or WebDriverAgent (iOS). |
| `APPIUM_SKIP_INSTALLATION` | No | `true` | When `true`, skips reinstalling the app before each test. Speeds up repeated runs on the same device. |
| `DEVICE_NAME` | No | - | Name of the target device or emulator (e.g., `iPhone 15 Pro`, `Pixel 7`). |
| `IOS_PLATFORM_VERSION` | No | - | iOS version to target (e.g., `17.2`). Required for iOS testing. |
| `ANDROID_DAEMON_HOSTS` | No | - | Comma-separated list of Android daemon host addresses for distributed device access. |
| `IOS_DAEMON_HOSTS` | No | - | Comma-separated list of iOS daemon host addresses for distributed device access. |
| `SKIP_DEVICE_DATE_UPDATE` | No | `false` | When `true`, skips updating the device date/time before tests. Useful when the device clock is already correct. |
***
## Jobs
### Execution Agent Runner
**Source:** `packages/engine/src/execution-agent/runner/env.ts`
| Variable | Required | Default | Description |
| -------------- | -------- | ------- | ------------------------------------------------------------------------------------------------------------------------ |
| `ARTIFACT_DIR` | No | - | Local directory for saving test artifacts (screenshots, videos, step logs). Used by the local runner during development. |
### Run Completion Notification
**Source:** `apps/jobs/run-completion-notification/src/env.ts`
| Variable | Required | Default | Description |
| ----------------------- | -------- | ------- | ------------------------------------------------------- |
| `DATABASE_URL` | Yes | - | PostgreSQL connection string. |
| `API_URL` | No | - | API server URL for callbacks. |
| `ENGINE_BILLING_SECRET` | No | - | Shared secret for authenticating billing-related calls. |
| `STRIPE_ENABLED` | No | `false` | Whether to process billing events on run completion. |
### Worker - Diffs
**Source:** `apps/workers/diffs/src/env.ts`
Diffs analysis and resolution run as Temporal activities in the `@autonoma/worker-diffs` worker. AI model keys come from the AI Services section; this worker adds the GitHub App credentials it needs to clone repositories and read PRs.
| Variable | Required | Default | Description |
| --------------------------- | -------- | ------- | --------------------------------------------------------------------- |
| `GITHUB_APP_ID` | Yes | - | GitHub App ID for repository access. |
| `GITHUB_APP_PRIVATE_KEY` | Yes | - | GitHub App private key, base64-encoded PEM (`cat key.pem \| base64`). |
| `GITHUB_APP_WEBHOOK_SECRET` | Yes | - | GitHub App webhook secret for verifying events. |
| `GITHUB_APP_SLUG` | Yes | - | GitHub App slug (URL-friendly name). |
| `SENTRY_DSN_WORKER_DIFFS` | No | - | Sentry DSN for the diffs worker. |
***
## GitHub App
These variables appear in `.env.example` and are used by the API server and the diffs worker for GitHub integration features (repository connections, PR-triggered test runs).
| Variable | Required | Default | Description |
| --------------------------- | -------- | ------- | -------------------------------------------------------------------------------------- |
| `GITHUB_APP_ID` | No | - | GitHub App ID. Required for GitHub integration features. |
| `GITHUB_APP_PRIVATE_KEY` | No | - | GitHub App private key, base64-encoded PEM (`cat key.pem \| base64`). Decoded at boot. |
| `GITHUB_APP_WEBHOOK_SECRET` | No | - | Secret for verifying GitHub webhook payloads. |
| `GITHUB_APP_SLUG` | No | - | GitHub App slug (URL-friendly name). Used for generating installation links. |
***
## Authentication
These variables are referenced in `.env.example` for the Better Auth integration used by the API server.
| Variable | Required | Default | Description |
| ---------------------------- | -------- | -------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `BETTER_AUTH_SECRET` | Yes | - | Secret key for Better Auth session signing. Generate with `openssl rand -hex 32`. |
| `BETTER_AUTH_URL` | Yes | - | Root origin of the API server (e.g., `http://localhost:4000`). Used by Better Auth for callback URLs. Origin only - see the warning below. |
| `OAUTH_PROXY_PRODUCTION_URL` | No | - | The one origin whose OAuth callback is registered with the providers, for the whole fleet. Every deployed environment sets the same value. Leave unset locally. |
| `OAUTH_PROXY_SECRET` | No | `BETTER_AUTH_SECRET` | Encrypts the profile payload the proxy hands back to the originating environment. Every participating environment must share the same value. |
> **BETTER\_AUTH\_URL:**
>
> Better Auth is mounted with basePath `/v1/auth` and appends that itself. A value like `https://yourdomain.com/v1` makes every auth endpoint 404.
### OAuth proxying
A provider only redirects to callback URLs registered with it ahead of time, and an alpha environment’s hostname is minted per PR - so it can never be one of them. Instead, every deployed environment sends the provider **production’s** callback URL and gets the resulting profile handed back, encrypted and short-lived, at its own origin, where it mints its own session. Production’s own `APP_URL` matches `OAUTH_PROXY_PRODUCTION_URL`, so it skips proxying and serves the callback for the fleet.
Two things about this are easy to get wrong:
* **Leave both unset locally.** Local dev has its own OAuth apps, and enabling the proxy would mean configuring production to hand encrypted session payloads to a developer’s machine.
* **`OAUTH_PROXY_PRODUCTION_URL` is not a plain on/off switch.** Setting it without every participating environment sharing the same `OAUTH_PROXY_SECRET` breaks sign-in on the non-production environments.
`OAUTH_PROXY_SECRET` is deliberately separate from `BETTER_AUTH_SECRET`: it is shared across environments, so a leak must not also be able to forge sessions. It falls back to `BETTER_AUTH_SECRET` when unset, which works but widens the blast radius.
***
## Tips for Local Development
**What you can skip entirely:**
* **Billing** - Leave `STRIPE_ENABLED=false` (the default). No Stripe keys needed.
* **Analytics** - Omit `POSTHOG_KEY` and `VITE_POSTHOG_KEY`. Analytics calls become no-ops.
* **Sentry** - Omit `SENTRY_DSN` and `VITE_SENTRY_DSN`. Error tracking is disabled gracefully.
* **Kubernetes** - Omit `NAMESPACE`. The API defaults it to `local`; only `@autonoma/k8s` needs a real one.
* **OAuth proxying** - Omit `OAUTH_PROXY_PRODUCTION_URL` and `OAUTH_PROXY_SECRET`. Local dev signs in against its own OAuth apps.
* **GitHub App** - Omit all `GITHUB_APP_*` variables unless you are working on GitHub integration.
* **Temporal** - Omit `VITE_TEMPORAL_URL`. The UI hides workflow links when this is unset.
**What uses defaults that just work:**
* `ALLOWED_ORIGINS` defaults to `http://localhost:3000` - correct for local dev.
* `VITE_API_URL` defaults to `http://localhost:4000` - correct for local dev.
* `APP_URL` defaults to `http://localhost:3000` - correct for local dev.
* `NODE_ENV` defaults to `development`.
* `AGENT_VERSION` defaults to `latest`.
**What you must provide:**
* `DATABASE_URL` - there is no default. You need a running PostgreSQL instance.
* `REDIS_URL` - there is no default. You need a running Redis instance.
* `GOOGLE_CLIENT_ID` and `GOOGLE_CLIENT_SECRET` - required for authentication. Create OAuth credentials in the [Google Cloud Console](https://console.cloud.google.com/apis/credentials).
* `GITHUB_CLIENT_ID` and `GITHUB_CLIENT_SECRET` - optional. Set both to add GitHub as a second sign-in option; see [Development Setup](/development/setup/) for the OAuth app steps.
* `SCENARIO_ENCRYPTION_KEY` - any non-empty string works locally.
* `BETTER_AUTH_SECRET` - generate one with `openssl rand -hex 32`.
* `BETTER_AUTH_URL` - set to `http://localhost:4000`. The origin only; appending `/v1` 404s every auth endpoint.
* AI keys (`GEMINI_API_KEY`, `GROQ_KEY`, `OPENROUTER_API_KEY`) - required if you are running test execution. Not needed if you are only working on the UI or API without triggering test runs.
* S3 credentials - required for artifact storage. Use MinIO locally.
# Execution Agent
> Deep dive into the core test execution engine - a platform-agnostic AI agent that powers web and mobile test execution through natural language.
The execution agent is the brain of Autonoma’s test execution. It is a **generic, platform-agnostic AI agent** that takes a natural language test instruction, interacts with a live application through screenshots and commands, and produces a structured test result with recorded steps.
Web (`engine-web`) and mobile (`engine-mobile`) engines both extend this shared core. Everything is parameterized with `TSpec` (command spec) and `TContext` (driver context), so the same agent logic works across Playwright and Appium without code duplication.
## The Agent Loop
Every test execution follows the same cycle:
```plaintext
┌─────────────────────────────────────────────────────┐
│ 1. Screenshot - capture current screen state │
│ 2. Inject context - screenshot + instruction + │
│ steps-so-far + memory into a user message │
│ 3. LLM decides - model picks a tool/command │
│ (or calls execution-finished) │
│ 4. Command executes - the chosen command runs │
│ against platform drivers │
│ 5. Record step - save before/after metadata, │
│ execution output, and screenshots │
│ 6. Loop or stop - continue until execution-finished │
│ is called or maxSteps is reached │
└─────────────────────────────────────────────────────┘
```
The agent wraps the Vercel AI SDK’s `ToolLoopAgent`. Before each step, it captures a screenshot and injects it alongside the test instruction, all previous steps, and any stored memory variables. The LLM then decides which command to call next.
**Loop detection:** If the model’s reasoning mentions “loop”, “stuck”, “no progress”, or “repeating” in a `success: false` finish, the result is flagged as a loop.
**Success validation:** Even if the model calls `execution-finished` with `success: true`, the agent verifies that at least one command step was executed and at least one `assert` step exists. If either check fails, the result is overridden to `success: false`.
## Directory Structure
```plaintext
packages/engine/src/
├── commands/ # Command abstraction system
│ ├── command-spec.ts # CommandSpec type definition
│ ├── command.ts # Abstract Command base class
│ ├── command-defs.ts # Union of all command specs
│ ├── step.ts # StepData type
│ └── commands/ # Built-in command implementations
│ ├── click/ # AI-powered element clicking
│ ├── type/ # Find element + type text
│ ├── scroll/ # Scroll with condition checking
│ ├── assert/ # Visual assertion checking
│ ├── hover/ # Hover over elements (web only)
│ ├── drag/ # Drag from one element to another
│ ├── read/ # Extract text from screen into memory
│ ├── navigate/ # Navigate to URL (web only, last resort)
│ ├── refresh/ # Refresh the current page
│ └── save-clipboard/ # Save clipboard content to memory
├── execution-agent/ # Core AI agent loop
│ ├── agent/
│ │ ├── execution-agent.ts # Main agent class
│ │ ├── execution-agent-factory.ts # Abstract factory for building agents
│ │ ├── execution-result.ts # Result types
│ │ ├── test-case.ts # TestCase interface
│ │ ├── system-prompt.ts # Agent system prompt
│ │ ├── memory/ # Variable memory store
│ │ └── tools/ # LLM tools
│ │ ├── command-tool.ts # Wraps Command as an AI SDK tool
│ │ ├── execution-finished-tool.ts
│ │ ├── ask-user-tool.ts
│ │ └── wait-tool.ts
│ ├── runner/
│ │ ├── execution-agent-runner.ts # Main runner - ties installer + factory + recording
│ │ ├── artifacts.ts # Writes screenshots, steps, video to disk
│ │ └── events.ts # Event hooks (beforeStep, attempt, frame)
│ └── local-dev/
│ ├── local-runner.ts # Local dev runner (loads markdown test files)
│ └── load-test-case.ts # Parses markdown frontmatter into test cases
└── platform/ # Platform driver interfaces
├── context/
│ ├── base-context.ts # BaseCommandContext (screen + application drivers)
│ ├── installer.ts # Abstract Installer
│ ├── image-stream.ts # Live frame streaming interface
│ └── video-recorder.ts # Abstract VideoRecorder with state machine
└── drivers/
├── screen.driver.ts # screenshot(), getResolution()
├── mouse.driver.ts # click(), hover(), drag(), scroll()
├── keyboard.driver.ts # type(), press(), selectAll(), clear()
├── application.driver.ts # waitUntilStable()
├── navigation.driver.ts # navigate(), getCurrentUrl(), refresh()
└── clipboard.driver.ts # read()
```
## CommandSpec - The Command Type System
Every command is defined by a `CommandSpec`:
```ts
interface CommandSpec {
interaction: string; // command name (e.g., "click")
params: object; // what gets stored on the step record
output: BaseOutput; // what the command returns (always includes `outcome: string`)
}
```
The `Command` abstract base class is what all commands extend:
```ts
abstract class Command {
abstract readonly interaction: TSpec["interaction"];
abstract readonly paramsSchema: z.ZodSchema>;
abstract execute(params: CommandParams, context: TContext): Promise>;
}
```
The `CommandTool` class wraps a `Command` to make it compatible with the AI SDK. It adds:
* An `inputSchema()` that defines what the LLM provides (may differ from `paramsSchema`)
* A `description()` shown to the AI model
* An `extractParams()` method that converts LLM input into command parameters
This separation means the LLM can provide a natural language description (“the blue submit button”) while the stored params contain the resolved coordinates and structured data recorded on the step.
## Built-in Commands
| Command | Exposed to LLM | Params | What it does |
| ------------------ | -------------- | ----------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **click** | Yes | `{ description, options }` | Takes a natural-language element description, uses `PointDetector` AI to locate pixel coordinates, calls `mouse.click(x, y)` |
| **type** | Yes | `{ description, text, overwrite }` | Uses `PointDetector` to find the input element, clicks it, then types the text. Supports overwrite mode to replace existing content |
| **assert** | Yes | `{ instruction }` | Takes an instruction (can contain multiple assertions). Uses `AssertionSplitter` to decompose, takes one screenshot, runs `AssertChecker` on all assertions in parallel |
| **scroll** | Yes | `{ elementDescription?, direction, condition, maxScrolls }` | Scrolls up or down on a specific element or the page, checking a visual condition after each scroll |
| **hover** | Yes | `{ description }` | Hovers over an element identified by natural language description (web only) |
| **drag** | Yes | `{ startDescription, endDescription }` | Drags from one element to another, both identified by natural language |
| **read** | Yes | `{ description, variableName }` | Extracts text from the screen and stores it in the agent’s memory under `variableName` for use in later steps via `{{variableName}}` syntax |
| **navigate** | Yes | `{ url }` | Navigates directly to a URL. Accepts full URLs, URLs without protocol (adds `https://`), or relative paths (resolved against the current page origin). **Last resort only** - prefer UI interaction (clicking links, buttons) to find bugs. Use only when you can’t reach something through the UI, or you’ve already tested the UI navigation in the same test (web only) |
| **refresh** | Yes | (none) | Refreshes the current page |
| **save-clipboard** | Yes | `{ variableName }` | Reads clipboard content and stores it in memory under `variableName` |
## LLM Tools (Non-Command)
These tools are available to the model but are not recorded as test steps:
| Tool | Purpose |
| ---------------------- | ------------------------------------------------------------------------------------------------------------------------ |
| **wait** | Sleeps for N seconds. Useful for loading screens or animations |
| **ask-user** | Sends questions to a human via WebSocket. Pauses execution until answered. Only available in frontend-connected sessions |
| **execution-finished** | Called by the model to end the test. Takes `{ success, reasoning }` |
## Driver Interfaces
Platform-specific apps (`engine-web`, `engine-mobile`) implement these interfaces:
### ScreenDriver
```ts
interface ScreenDriver {
getResolution(): Promise;
screenshot(): Promise;
}
```
### MouseDriver
```ts
interface MouseDriver> {
click(x: number, y: number, options?: TClickOptions): Promise;
hover?(x: number, y: number): Promise;
drag(startX: number, startY: number, endX: number, endY: number): Promise;
scroll(args: ScrollArgs): Promise;
}
```
### KeyboardDriver
```ts
interface KeyboardDriver {
selectAll(): Promise;
clear(): Promise;
type(text: string, options?: TypeOptions): Promise;
press(key: string): Promise;
}
```
### ApplicationDriver
```ts
interface ApplicationDriver {
waitUntilStable(): Promise;
}
```
### NavigationDriver
```ts
interface NavigationDriver {
navigate(url: string): Promise;
getCurrentUrl(): Promise;
refresh(): Promise;
}
```
### ClipboardDriver
```ts
interface ClipboardDriver {
read(): Promise;
}
```
The `BaseCommandContext` requires only `screen` and `application` drivers. Each platform extends this with additional drivers as needed.
## Memory System
The agent maintains a `MemoryStore` - a key-value store that persists across steps within a single execution. Commands like `read` and `save-clipboard` write values into memory, and any subsequent command can reference stored values using `{{variableName}}` template syntax.
When a command executes, the agent resolves `{{variableName}}` templates in the parameters before passing them to the command. The unresolved params are stored on the step record (keeping the template references), while the resolved values are used for actual execution.
## Adding a New Command
1. **Define the spec.** Create a `CommandSpec` type for the command’s interaction, params, and output:
packages/engine/src/commands/commands/my-command/my-command.def.ts
```ts
import z from "zod";
export interface MyCommandSpec {
interaction: "my-command";
params: { target: string; value: number };
output: { outcome: string; success: boolean };
}
export const myCommandParamsSchema = z.object({
target: z.string().describe("Description for the LLM"),
value: z.number().describe("A numeric value"),
});
```
2. **Implement the command.** Create a class extending `Command`:
packages/engine/src/commands/commands/my-command/my-command.command.ts
```ts
import { Command } from "../../command";
import { type MyCommandSpec, myCommandParamsSchema } from "./my-command.def";
export class MyCommand extends Command {
readonly interaction = "my-command" as const;
readonly paramsSchema = myCommandParamsSchema;
async execute(params, context) {
// Use context drivers to perform the action
return { outcome: "Did the thing", success: true };
}
}
```
3. **Create the tool wrapper.** Create a `CommandTool` subclass that defines how the LLM interacts with the command:
packages/engine/src/execution-agent/agent/tools/commands/my-command.tool.ts
```ts
import { CommandTool } from "../command-tool";
import type { MyCommandSpec } from "../../../../commands/commands/my-command/my-command.def";
export class MyCommandTool extends CommandTool {
protected inputSchema() { return myCommandParamsSchema; }
description() { return "Description shown to the AI model"; }
protected async extractParams(input, context) { return input; }
}
```
4. **Register it.** Add the tool to the command tools array in your `ExecutionAgentFactory` subclass.
5. **Add the spec to the union type** in `packages/engine/src/commands/command-defs.ts` so TypeScript knows about it.
## Extending for a New Platform
1. **Implement all driver interfaces** using your platform’s SDK. At minimum you need `ScreenDriver` and `ApplicationDriver` (the `BaseCommandContext`). Add `MouseDriver`, `KeyboardDriver`, `NavigationDriver`, and `ClipboardDriver` as needed.
2. **Create an `Installer` subclass** that builds the context. The installer receives application data (URL, device config, etc.) and returns the context with all drivers, plus an `ImageStream` and `VideoRecorder`:
```ts
class MyPlatformInstaller extends Installer {
async install(appData: MyAppData) {
// Launch browser/device, create driver instances
return { context, imageStream, videoRecorder };
}
}
```
3. **Create an `ExecutionAgentFactory` subclass** that builds the agent with platform-specific command tools:
```ts
class MyPlatformAgentFactory extends ExecutionAgentFactory {
async buildAgent(params) {
return new ExecutionAgent({
model: this.model,
systemPrompt: this.systemPrompt,
maxSteps: 50,
commandTools: [new ClickTool(...), new TypeTool(...), ...],
// ...rest of config
...params,
});
}
}
```
4. **Create a runner entry point** that wires the installer, factory, and event handlers together using `ExecutionAgentRunner`.
## The Runner and Artifacts
`ExecutionAgentRunner` orchestrates a full test run:
1. Calls `Installer.install()` to build the platform context (browser/device + drivers)
2. Registers a frame handler for live streaming
3. Builds the `ExecutionAgent` via the factory
4. Wraps `agent.generate()` in `VideoRecorder.withRecording()`
5. Returns `{ result, videoPath }`
`LocalRunner` extends this for local development - it loads test cases from markdown files and saves artifacts to disk:
```plaintext
artifacts/{timestamp}-{testName}/
├── screenshots/step-0-before.jpeg, step-0-after.jpeg, ...
├── steps.json # Array of step execution outputs
├── conversation.json # Sanitized AI turn log
├── instruction.txt # The test prompt
└── video.{ext} # Recording
```
## Attempt Timeline
The agent keeps a single in-memory timeline of **every** command attempt, modelled as a discriminated union on `status`:
**`GeneratedStep`** (`status: "success"`) - a command whose parameter extraction and `execute()` both completed:
* `executionOutput` - the command’s step data (interaction + params) and result
* `beforeMetadata` / `afterMetadata` - screenshots and other metadata from before/after the step
**`FailedStep`** (`status: "failed"`) - a command whose parameter extraction or `execute()` threw (e.g. a failed assertion, a point-detection miss, a driver error):
* `interaction` / `input` / `params` - the command attempted, the raw tool input, and the extracted params (absent if extraction itself threw)
* `error` / `errorName` - the thrown error’s message and class name (attribution signal)
* `beforeMetadata` - the screenshot the model saw when it chose the command
* `afterMetadata` - a best-effort after-screenshot (absent if even that capture failed)
**`StepAttempt`** - the union `GeneratedStep | FailedStep`. The successful steps are derived by filtering `status === "success"`; failed attempts never trigger memory writes.
Each attempt fires the runner’s `attempt` event as it happens, so the generation persister can live-persist it: successes write a `StepAttempt(success)` plus the `StepInput` / `StepOutput` committed step rows; failures write only a `StepAttempt(failed)`.
## Result Types
**`ExecutionResult`** - the full test result:
* `generatedSteps` - the successful steps only (the success subset of the attempt timeline)
* `memory` - final state of extracted variables
* `success` - whether the test passed (computed over successful steps only - a failed assertion never counts as a passing assertion)
* `finishReason` - `"success"`, `"max_steps"`, or `"error"`
* `reasoning` - the model’s explanation for finishing
* `conversation` - the full AI message history
**`LeanExecutionResult`** - a network-safe version that strips large image buffers from step metadata.
## Test Cases as Markdown
Test files use [gray-matter](https://github.com/jonschlinkert/gray-matter) frontmatter for parameters, with the body containing the natural language prompt:
```markdown
---
url: https://example.com
---
Navigate to the login page, enter "user@test.com" and "password123",
click Sign In, and assert the dashboard is visible.
```
The `loadTestCase` function parses the frontmatter against a Zod schema and extracts the prompt from the body.
# AI Package
> Deep dive into the AI primitives that power test execution - model registry, visual checkers, point detection, object detection, and structured output generation.
The `@autonoma/ai` package provides every AI primitive used by the execution agent. It handles model management, structured output generation, and evaluation benchmarking. The screenshot-driven primitives - visual checkers and point/object detection - live in `@autonoma/visual-ai`, which depends on `ai` and on `image` (`sharp`); this page covers both. No AI logic should be duplicated in platform apps - everything lives here.
## Directory Structure
```plaintext
packages/ai/src/
├── index.ts # Package re-exports
├── env.ts # Environment variables (API keys)
├── registry/ # Model registry and configuration
│ ├── model-registry.ts # Core ModelRegistry class
│ ├── model-entries.ts # Model definitions and pricing
│ ├── providers.ts # LLM provider singletons
│ ├── options.ts # ModelOptions, reasoning effort levels
│ ├── costs.ts # Cost calculation functions
│ ├── cost-collector.ts # Aggregated cost tracking
│ ├── usage.ts # Token usage tracking
│ └── monitoring.ts # Logging middleware and telemetry
├── text/
│ └── assertion-splitter.ts # Split compound assertions into atomic ones
└── object/ # Structured output generation
├── object-generator.ts # Core structured JSON generator
├── retry.ts # Retry with exponential backoff
├── user-messages.ts # Build multimodal messages (text + images + video)
└── video/
├── video-processor.ts # Upload videos to Google GenAI Files API
└── video-input.ts # Video input types and model support
packages/visual-ai/src/
├── visual/ # Visual AI primitives (depend on sharp)
│ ├── visual-condition-checker.ts # Check if a condition is met on a screenshot
│ ├── assert-checker.ts # Validate test assertions
│ ├── visual-chooser.ts # Pick which UI element matches an instruction
│ └── text-extractor.ts # Extract text from screenshots
└── freestyle/ # Point and object detection
├── resolution-fallback.ts # Coordinate resolution management
├── point/
│ ├── point-detector.ts # Abstract PointDetector base
│ ├── gemini-computer-use-point-detector.ts
│ └── object-point-detector.ts # Adapter: ObjectDetector -> PointDetector
└── object/
├── object-detector.ts # Abstract ObjectDetector base
└── gemini-object-detector.ts # Gemini-based bounding box detection
```
## Model Registry
`ModelRegistry` manages all LLM instances with middleware for cost calculation and monitoring. It wraps the Vercel AI SDK’s language models with provider-specific configuration.
### How It Works
The registry is constructed with a map of model entries. Each entry knows how to create its model instance and how to calculate costs:
```ts
const registry = new ModelRegistry({
models: MODEL_ENTRIES,
defaultSettings: { temperature: 0 },
monitoring: { onGenerate: (result) => { /* log it */ } },
});
```
The registry is a stateless, construct-once singleton - it holds no mutable per-run state. When you request a model, it wraps it with middleware for monitoring, cost calculation, and default settings:
```ts
const model = registry.getModel({
model: "GEMINI_3_FLASH_PREVIEW",
tag: "assert-checker",
reasoning: "low",
});
```
The `tag` field identifies the use case (e.g., “assert-checker”, “click-detector”) for monitoring and cost attribution. The `reasoning` field sets the thinking effort level.
### Current Models
| Key | Model ID | Provider |
| ------------------------ | ----------------------------- | ---------- |
| `GEMINI_3_FLASH_PREVIEW` | `gemini-3-flash-preview` | Google |
| `GEMINI_3_5_FLASH_LITE` | `gemini-3.5-flash-lite` | Google |
| `QWEN3_VL_32B` | `qwen/qwen3-vl-32b-instruct` | OpenRouter |
| `MINISTRAL_8B` | `mistralai/ministral-8b-2512` | OpenRouter |
| `GPT_OSS_120B` | `openai/gpt-oss-120b` | Groq |
| `MINIMAX_M3` | `minimax/minimax-m3` | OpenRouter |
An alternative `OPENROUTER_MODEL_ENTRIES` set routes all models through OpenRouter, including a Gemini variant (`google/gemini-3-flash-preview`) and a Llama variant (`meta-llama/llama-4-maverick`) in place of Ministral.
### Providers
Three LLM provider singletons are available, each lazily initialized with their respective API key:
| Provider | SDK | Env Variable |
| -------------------- | ----------------------------- | -------------------- |
| `googleProvider` | `@ai-sdk/google` | `GEMINI_API_KEY` |
| `groqProvider` | `@ai-sdk/groq` | `GROQ_KEY` |
| `openRouterProvider` | `@openrouter/ai-sdk-provider` | `OPENROUTER_API_KEY` |
The `LLMProvider` class wraps each provider as a singleton - the underlying SDK instance is created on first use.
### Reasoning Effort
The `ModelReasoningEffort` type supports four levels:
| Level | Groq | Google |
| ---------- | --------------------------- | ------------------------- |
| `"none"` | `reasoningEffort: "none"` | Thinking disabled |
| `"low"` | `reasoningEffort: "low"` | `thinkingLevel: "low"` |
| `"medium"` | `reasoningEffort: "medium"` | `thinkingLevel: "medium"` |
| `"high"` | `reasoningEffort: "high"` | `thinkingLevel: "high"` |
Reasoning effort is translated to provider-specific options in `buildSettings()`, so callers never need to think about which provider they are targeting.
### Cost Tracking
Per-run cost and usage tracking flows through a `CostCollector`. Construct one per run and pass it to `getModel`; every call issued by that model is metered into the collector:
```ts
const costCollector = new CostCollector();
const model = registry.getModel({ model: "GEMINI_3_FLASH_PREVIEW", tag: "assert-checker" }, costCollector);
// After execution, aggregate the per-call records:
const records = costCollector.getRecords();
// Each record carries { model, tag, inputTokens, outputTokens, reasoningTokens, cacheReadTokens, costMicrodollars }.
```
Keeping this state on a per-run collector (rather than the registry) lets a single shared registry attribute cost to many concurrent runs without mutable per-instance state. Group records by `tag` or `model` to trace costs back to specific use cases.
## Visual AI Primitives
### VisualConditionChecker
The base class for checking whether a condition is met on a screenshot. It extends `ObjectGenerator` with a predefined schema:
```ts
const checker = new VisualConditionChecker({ model });
const result = await checker.checkCondition(
"The login form is visible with email and password fields",
screenshot,
);
// result: { metCondition: true, reason: "The form is visible with both fields" }
```
Returns `{ metCondition: boolean, reason: string }`.
### AssertChecker
Extends `VisualConditionChecker` with a specialized system prompt for test assertions. It handles both positive assertions (“validate there’s a title that says Hello”) and negative assertions (“assert there’s no download button”):
```ts
const checker = new AssertChecker(model);
const result = await checker.checkCondition(
"The submit button is disabled",
screenshot,
);
```
Used by the `assert` command to validate each individual assertion against a screenshot.
### VisualChooser
Picks which UI element from a set of options matches a user instruction. It draws numbered bounding boxes on the screenshot and asks the model to choose:
```ts
const chooser = new VisualChooser({ model });
const result = await chooser.chooseOption({
options: [
{ boundingBox: { x: 10, y: 20, width: 100, height: 30 }, description: "Submit" },
{ boundingBox: { x: 10, y: 60, width: 100, height: 30 }, description: "Cancel" },
],
instruction: "Click the submit button",
screenshot,
});
// result: { reasoning: "Option 1 is the submit button", option: { ... } }
```
Throws `NoValidOptionFoundError` if no option matches, or `InvalidIndexError` if the model returns an out-of-bounds index.
### AssertionSplitter
Splits a compound assertion instruction into individual atomic assertions that can be checked independently:
```ts
const splitter = new AssertionSplitter(model);
const result = await splitter.splitAssertions(
"validate that the title is visible, the subtitle as well but the button is not",
);
// result.assertions: [
// "validate that the title is visible",
// "validate that the subtitle is visible",
// "validate that the button is not visible"
// ]
```
Importantly, the splitter ensures each split assertion contains enough context to stand alone. It repairs incomplete fragments (e.g., “the subtitle as well” becomes “validate that the subtitle is visible”).
## Point Detection
Point detectors locate where to interact on screen, given a natural language description. They are used by the `click`, `type`, `hover`, and `drag` commands.
### Abstract Base
All point detectors extend `PointDetector`:
```ts
abstract class PointDetector {
protected abstract detectPointForResolution(
screenshot: Screenshot,
prompt: string,
resolution: ScreenResolution,
): Promise;
async detectPoint(
screenshot: Screenshot,
prompt: string,
targetResolution?: ScreenResolution,
): Promise;
}
```
The public `detectPoint` method handles resolution fallback automatically - if no target resolution is provided, it defaults to the device resolution (if configured) or the image resolution.
### GeminiComputerUsePointDetector
Uses Google’s Gemini computer-use API with a `click_at` tool. The model returns coordinates in a normalized 0-1000 space, which are then scaled to actual pixel coordinates based on the target resolution.
### ObjectPointDetector
An adapter that converts an `ObjectDetector` into a `PointDetector`. It detects the bounding box of an element and returns the center point. Useful when you have an object detector but need point-level precision.
## Object Detection
### ObjectDetector (Abstract Base)
Detects objects in an image and returns bounding boxes:
```ts
abstract class ObjectDetector {
async detectObjects(
screenshot: Screenshot,
prompt: string,
targetResolution?: ScreenResolution,
): Promise;
}
```
Each `DetectedObject` contains a `boundingBox` and an optional `label`.
### GeminiObjectDetector
Uses Gemini’s structured output to return bounding boxes as normalized 0-1000 coordinates. Useful for detecting multiple UI elements at once.
## ObjectGenerator
The core structured output engine used by almost every AI primitive in the package. It wraps the AI SDK’s `generateText` with:
* **Zod schema validation** for structured JSON output
* **Automatic retry** with exponential backoff (default: 10 retries, 1s initial delay, 2x backoff factor, capped at 30s)
* **Multimodal input** via `GenerationParams` - supports text, images, and video
* **Null byte stripping** from responses for PostgreSQL compatibility
```ts
const generator = new ObjectGenerator({
model,
systemPrompt: "You are a UI analysis expert.",
schema: z.object({
elements: z.array(z.object({
label: z.string(),
visible: z.boolean(),
})),
}),
});
const result = await generator.generate({
userPrompt: "List all visible buttons",
images: [screenshot],
});
```
Video capability is declared by the registry entry: one that can take video declares a `createUploader`, and `ModelRegistry.getVideoModel` returns the model paired with it. Google entries upload through the GenAI Files API (`VideoProcessor`); OpenRouter-routed entries inline the recording as base64 mp4 (`InlineMp4VideoUploader`). Either way the caller passes the resulting `UploadedVideo` as `video` and never handles transport itself.
If generation fails after all retries, an `ObjectGenerationFailedError` is thrown wrapping the original error.
## Adding a New Model
1. **Add the model entry** to `packages/ai/src/registry/model-entries.ts`:
```ts
export const MODEL_ENTRIES = {
// ...existing entries
MY_NEW_MODEL: {
createModel: () => googleProvider.getModel("my-new-model-id"),
pricing: simpleCostFunction({
inputCostPerM: 0.5,
outputCostPerM: 1.5,
}),
},
} as const;
```
2. **Choose the right cost function.** Use `simpleCostFunction` for models without cache pricing, or `inputCacheCostFunction` for models that support input caching (adds a `cachedInputCostPerM` field).
3. **Add a provider** if needed. If the model uses a provider not yet configured, add a new `LLMProvider` singleton in `providers.ts` and add the corresponding API key to `env.ts`.
4. **Use the model** by referencing its key when calling `registry.getModel()`:
```ts
const model = registry.getModel({
model: "MY_NEW_MODEL",
tag: "my-use-case",
reasoning: "medium",
});
```
## Adding a New Visual AI Primitive
Most visual primitives follow the same pattern: extend `ObjectGenerator` with a specialized schema and system prompt.
1. **Define the output schema** with Zod:
```ts
const myPrimitiveSchema = z.object({
elements: z.array(z.object({
name: z.string(),
confidence: z.number(),
})),
});
type MyPrimitiveResult = z.infer;
```
2. **Create the class** extending `ObjectGenerator`:
```ts
export class MyPrimitive extends ObjectGenerator {
constructor(model: LanguageModel) {
super({
model,
systemPrompt: "Your specialized system prompt here.",
schema: myPrimitiveSchema,
});
}
async analyze(screenshot: Screenshot, instruction: string): Promise {
return this.generate({ images: [screenshot], userPrompt: instruction });
}
}
```
3. **Export it** from the package index.
For point or object detection, extend `PointDetector` or `ObjectDetector` instead and implement the `detectPointForResolution` or `detectObjectsForResolution` method.
## Evaluation Framework
The `evals/` directory contains a Vitest-integrated framework for benchmarking AI accuracy:
* **`Evaluation`** - base class that defines test cases and runs them against models
* **`ModelEvaluation`** - tracks token usage and cost per model across an evaluation run
* **Three eval types:**
* `assert-condition/` - measures assertion checking accuracy
* `freestyle-click/` - measures point detection accuracy
* `wait-for-instruction/` - measures wait condition generation accuracy
Results are saved as JSON with pass rates and per-case breakdowns, making it easy to compare models and track accuracy over time.
# Billing
> How Autonoma bills - the shared credit ledger, the five ways credits are consumed, the four ways they are granted, and the two settlement rails (Stripe and Vercel Marketplace) that sit on top of them.
Every organization on Autonoma spends **credits**. One ledger tracks them, one package (`@autonoma/billing`) owns every read and write to it, and two **settlement rails** put money behind them: Stripe for direct customers, the Vercel Marketplace for organizations that installed Autonoma from Vercel.
The distinction that matters most, and the one most often gotten wrong: the two rails are separate at the **money** layer and identical at the **credit** layer. A Vercel organization’s credits live in the same column, move through the same deduction code, and are granted by the same function as a Stripe organization’s. Only the settlement differs.
## The ledger
`BillingCustomer.creditBalance` is the single authoritative total, one row per organization. `CreditTransaction` is the append-only history behind it - one row per event, signed (negative for consumption, positive for grants), each carrying the balance it produced.
`subscriptionCreditBalance` sits beside it and is **not a second pool**. It is a tag recording how much of `creditBalance` came from the current plan cycle. “Top-up credits” in the UI is derived, not stored: `creditBalance - subscriptionCreditBalance`.
### Idempotency
Nothing in this package asks “have I already processed this?”. Instead every write derives a **deterministic transaction id** from whatever it is charging for, and lets the primary key collide:
| Path | Transaction id |
| ---------------------- | ------------------------------- |
| Test generation | `ctr_gen_${generationId}` |
| LLM proxy request | `ctr_llm_${requestId}` |
| AI cost batch | `ctr_ai_${firstAiCostRecordId}` |
| Preview runtime window | `ctr_preview_${usageWindowId}` |
| Previewkit build | `ctr_build_${appBuildId}` |
The insert is `ON CONFLICT (id) DO NOTHING`, and the balance `UPDATE` in the same statement is gated on `EXISTS (SELECT 1 FROM inserted)` - so a retry cannot double-charge even though the two writes are separate clauses. Stripe-anchored grants use unique foreign-key columns instead (`stripePaymentIntentId`, `stripeInvoiceId`, `stripeRefundId`).
## Spending credits
Five paths consume credits. Three share one primitive; two predate it.
**`deductCreditsFloored`** is the shared primitive. It never refuses: it clamps the balance at the organization’s `creditFloor` (default `0`) instead of requiring sufficient funds, because work already in flight must never be half-billed. For an organization with unlimited credits it writes the ledger row and leaves both balances untouched - see [Guardrails](#guardrails).
| Path | Priced by | Uses the primitive |
| ----------------------------- | --------------------------------------------- | -------------------------------------- |
| AI cost (analysis activities) | credits-per-USD rate | yes |
| Preview runtime compute | `usdPerVcpuHourMicros` / `usdPerGbHourMicros` | yes |
| Previewkit build compute | same compute rates | yes |
| Test generation | per-architecture generation cost | no - hard sufficiency gate that throws |
| LLM proxy (planner CLI) | credits-per-USD rate | no - floors at literal `0` |
The bottom two rows are historical accidents rather than intent.
### AI cost attribution
AI-consuming activities never pass an organization id. `persistAiCosts` reads it from the **ambient observability context**, bound by the Temporal activity interceptor from the activity’s own input. A new AI-consuming activity therefore gets correct attribution and billing with no call-site wiring.
The deduction is best-effort: a pricing or database failure logs and moves on, because a billing side-effect must never sink an activity that already produced its real result.
### Compute metering
Running previews and build jobs are measured differently because they have to be. A live preview’s usage is read from Prometheus in fifteen-minute windows by the `preview-usage-meter` cronjob. Build jobs cannot be read the same way - buildkit nodes are excluded from the scrape - so build usage is derived from the build’s duration times its node’s known shape.
Both are priced with the same per-hour rates, and those rates are checked against **real AWS pricing**: a weekly job derives what the underlying instances actually cost, blending on-demand and spot by buildkit’s genuine recent mix, and alerts when the reference drifts more than 10% from what was stored. It only ever writes a reference table - a human decides whether to move any organization’s live rate.
Both compute rates default to zero, so compute is metered but not charged until an admin sets them.
## Getting credits
* **Top-up purchases** - a credit package from the shared catalog, bought through Stripe Checkout or, on the Vercel rail, granted on the spot and invoiced on the installation.
* **Auto top-up** - optional per organization: when the balance falls below `autoTopUpThreshold`, buy the chosen package again automatically. It settles by the organization’s own rail, so a Stripe organization is charged off-session and a Vercel one has the package invoiced. On the Stripe rail it cannot be enabled without a saved card, because there would be nothing to charge, and a card is only saved by completing a purchase.
Where it runs differs by rail, and not arbitrarily. A Stripe charge can go from any host that holds the secret key, so it fires straight off the deduction. A Vercel recharge has to raise an invoice, which needs `VERCEL_ENCRYPTION_KEY` - and the workers doing the deducting do not hold it, so there it logs and skips rather than granting credits nothing can bill for. The `vercel-billing-invoicer` cronjob, which does hold the key, sweeps for those organizations instead. That sweep reads state rather than reacting to an event, so a recharge missed for any reason is picked up next run.
A recharge that fails is recorded on the customer (`autoTopUpLastFailureReason`) and shown on the billing page, cleared by the next successful charge. That record exists because auto top-up fires from whichever host ran the deduction - a worker, the previewkit runner, a cronjob - and none of those can send email; only the API host also sends one.
A deduction is not the only thing that should cause a recharge, so it is not the only thing that does. The `auto-topup-reconciler` cronjob sweeps every 15 minutes for organizations sitting below their threshold and recharges them, whatever did or did not happen to them. Without it, the recharge is edge-triggered and misses every case where one becomes possible without a deduction - most importantly a spend cap whose calendar month rolls over while the organization is out of credits: it is blocked at the credit gate, so nothing deducts, so nothing triggers, and the fresh headroom is never used. A card replaced after a decline and a package reactivated after being pulled have the same shape. The deduction hook stays as the fast path; the sweep is the floor under it. A recorded failure suppresses further attempts for six hours, so a card that will keep declining is not re-charged every tick.
* **Promo codes** - redeemable once per organization, with optional redemption limits and date windows.
* **Free start credits** - a one-time grant keyed on the **email address**, not the organization, so creating a second organization does not earn a second grant.
* **Refunds** - a refunded purchase revokes credits proportionally.
## Guardrails
**Credit floor** - how far below zero an organization’s balance may go. Work already running keeps going and is charged in full; the floor only blocks *new* work starting, via `checkPreviewDeployCreditsGate` (preview deploys) and `checkAnalysisCreditsGate` (PR analysis runs).
A floor below zero is an extension of credit, so it applies only to an organization that has settled a bill at least once - a Stripe top-up (net of refunds), an active Stripe subscription, or a Vercel invoice Vercel reports paid and has not since refunded. A free-start organization that has never paid is gated at `0` no matter what its floor says, and `updateCreditFloor` refuses to set a negative one for it. The check runs on every gate rather than only at write time, so an organization that pays, earns an overdraft and then refunds its way back to nothing loses the overdraft with the payment that justified it.
**Grace period** - an unpaid invoice starts a countdown on either rail. Once it expires, the gates begin refusing work.
**Unlimited credits** - an organization marked `unlimitedCredits` is exempt from billing for usage: every gate passes whatever its balance, the grace period does not apply to it, and no deduction moves its balance. Consumption is still priced and written to the ledger, so the transaction history answers “what did this organization cost us” for the whole period the exemption was on. It is a deliberate admin action (`admin.billing.updateUnlimitedCredits`), not something an organization can reach on its own. Auto top-up is skipped for these organizations: a balance that consumption never moves would otherwise sit under `autoTopUpThreshold` forever and recharge a card for credits nothing spends. The previewkit credits watcher skips them for the same reason - it is level-triggered, so an exempt organization at or under its floor would read as exhausted on every pass.
**The exemption covers usage, not the plan.** Grants still land on the balance exactly as they always did - a promo code, a top-up purchase, a subscription renewal - and a subscription the organization holds keeps being charged by Stripe. So the balance can move while the exemption is on; what cannot move it is consumption. Revoking the exemption resumes deducting from whatever the balance reads at that moment. An organization that should stop paying altogether needs its subscription cancelled as well.
Note that `autoTopUpThreshold` is a *floor* that triggers a purchase, not a ceiling on spending. It is easy to mistake for one.
## The two rails
| | Stripe | Vercel Marketplace |
| ---------------------------- | ----------------------------------------- | ------------------------------------------------- |
| Recurring credits | Subscription invoice | Plan allotment per cycle |
| Buy a package | Checkout redirect, granted on the webhook | Granted immediately, invoiced on the installation |
| Auto top-up | Yes, charges the saved card | Yes, buys the same package and invoices it |
| Spending ceiling | Monthly spend cap | Monthly spend cap, plus the per-cycle overage cap |
| Extra credits without buying | none | Overage minted internally, billed in arrears |
Both rails sell the same catalog at the same price, and both honour the same monthly spend cap. Only the settlement differs, and it differs in one way worth knowing: **Stripe collects before it grants, Vercel grants before it collects.** A card is charged and the webhook then grants; a Vercel purchase is granted on the spot and an invoice raised on the installation for Vercel to collect. Reversed, a failure between the two would bill a customer for credits they never received.
The exposure that ordering creates is bounded at **one unpaid purchase per organization**: until Vercel reports the invoice paid, that organization cannot buy again. This is also why a plan carrying no payment method is still sold to - Vercel owns collection, and an organization that never settles walks away with a single package rather than an open tab.
Both rails call the same grant function when an invoice is paid, and the plan allotment for a Vercel organization is copied into the same pricing column a Stripe subscription uses. On both rails that grant is a **reset, not an addition** - each cycle overwrites the previous allotment and records the unused remainder as forfeited, so plan credits do not roll over. A purchased package is not part of that reset: it lands outside `subscriptionCreditBalance`, which is the portion the reset preserves.
On the Vercel rail, an unset overage cap means a **hard stop** at the plan allotment, not “unlimited”.
## Self-hosting
Setting `STRIPE_ENABLED=false` swaps the whole package for an implementation where every gate returns “allowed” and every deduction is a no-op. Self-hosted deployments are not metered.
## Known gaps
Documented because they are real, not because they are acceptable:
* Vercel invoice submission is not atomic across the network call, so a submitted-then-crashed run can invoice the same period twice.
* Refunding a Vercel *cycle* invoice does not claw back the plan allotment it granted. A refunded credit *purchase* does revoke its credits and reopen the cap headroom.
* An organization can hold more than one active Vercel installation; reads arbitrarily pick the newest.
* Overage is consulted only by the test-generation gate, so a Vercel organization with overage enabled is still blocked from preview deploys and analysis runs at its floor.